

A Lightweight Multi-Modal Semantic Segmentation Method Based on Dynamic Prompt and Knowledge Distillation
-
摘要: 语义分割是计算机视觉中场景理解的重要组成部分,然而传统方法大多基于可见光图像,在低亮度、强光照与遮挡等场景中性能急剧下降。尽管多模态融合能有效增强模型鲁棒性,现有方法普遍采用双支路网络架构,大幅增加模型参数量,难以部署在算力受限的嵌入式平台。针对上述问题,本文提出基于多模态特征融合提示网络的语义分割模型(Multi-modal Feature Fusion Prompt Network for robust semantic segmentation, MFFPNet)。该模型采用单支路骨干架构,引入轻量级动态视觉提示模块,将热红外或深度信息编码为动态提示向量,通过注意力机制注入预训练骨干网络,实现跨模态信息的高效交互。在此基础上,结合知识蒸馏对模型进行轻量化压缩,在硬件方面分层解耦架构屏蔽异构性,并引入多线程异步流水线,实现模型运行时推理优化,提升嵌入式平台上的语义分割实时性。实验结果表明,MFFPNet仅需更新9.4 M参数,约占模型总参数量的10.4%,在MFNet数据集上平均交并比(mIoU)达到63.3%,较基准方法提高1.9%,在NYUDv2数据集上mIoU达到60.6%,方法在精度与轻量化之间取得了较优平衡;轻量化变体MFFPNet-S在MFNet数据集上,以教师模型约20.0%的总参数量,保留其约88.8%的性能;提出的运行时优化策略在三种异构硬件平台上将吞吐量提升了21.7%~40.9%,满足了主流商用嵌入式平台与国产自主平台的实时部署需求。Abstract:
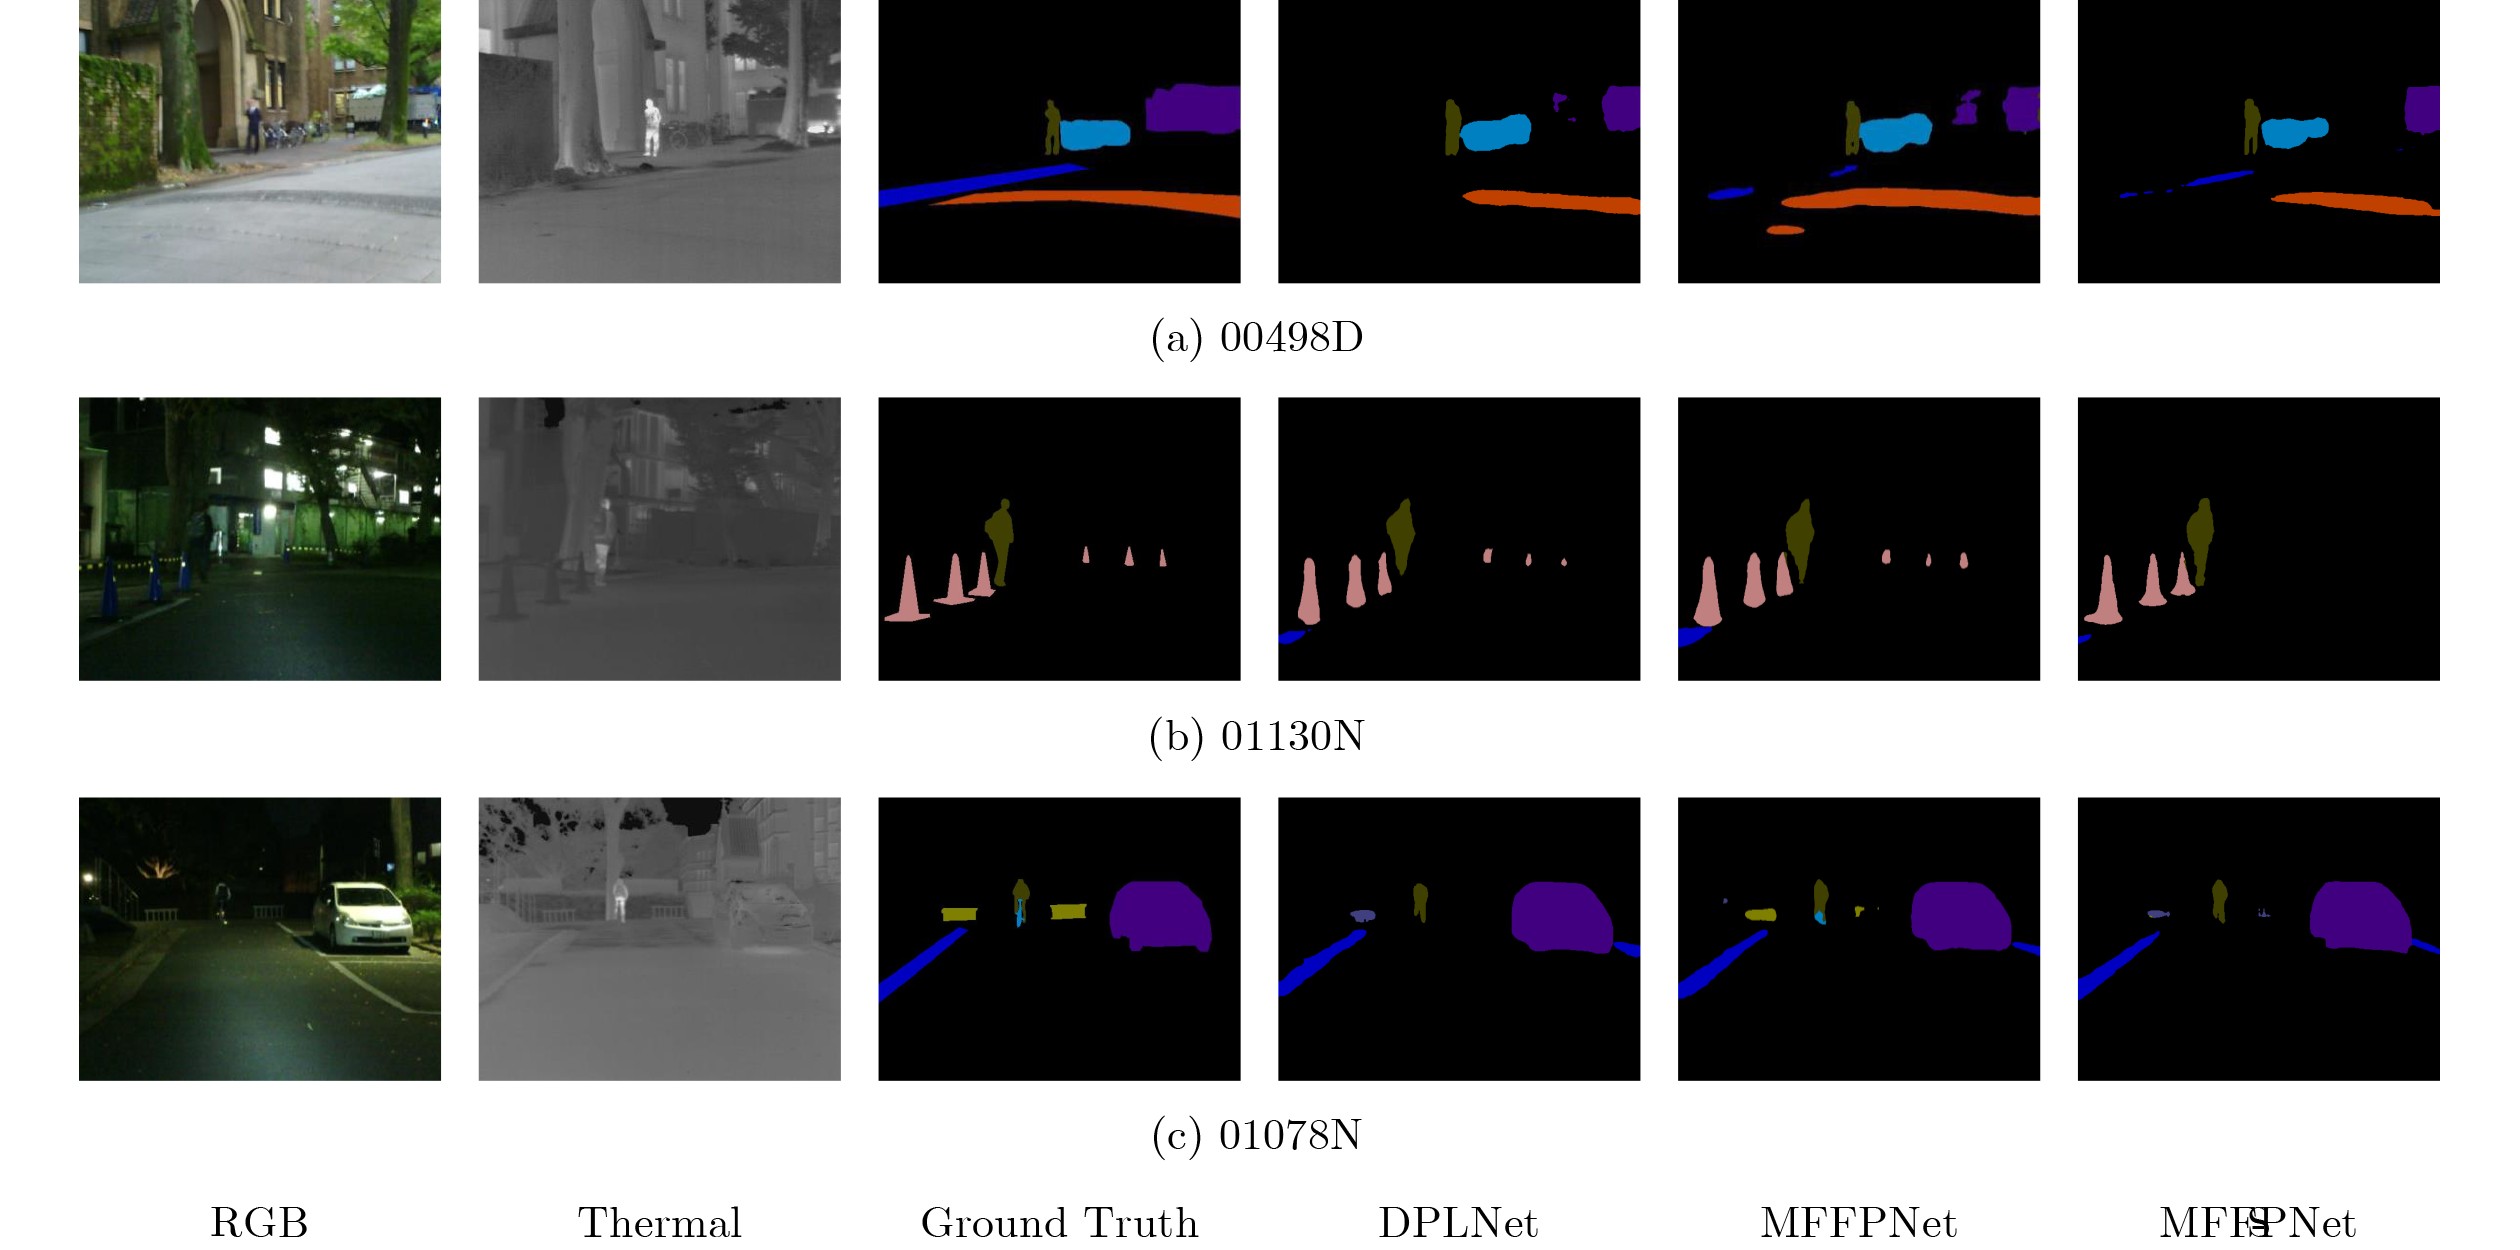
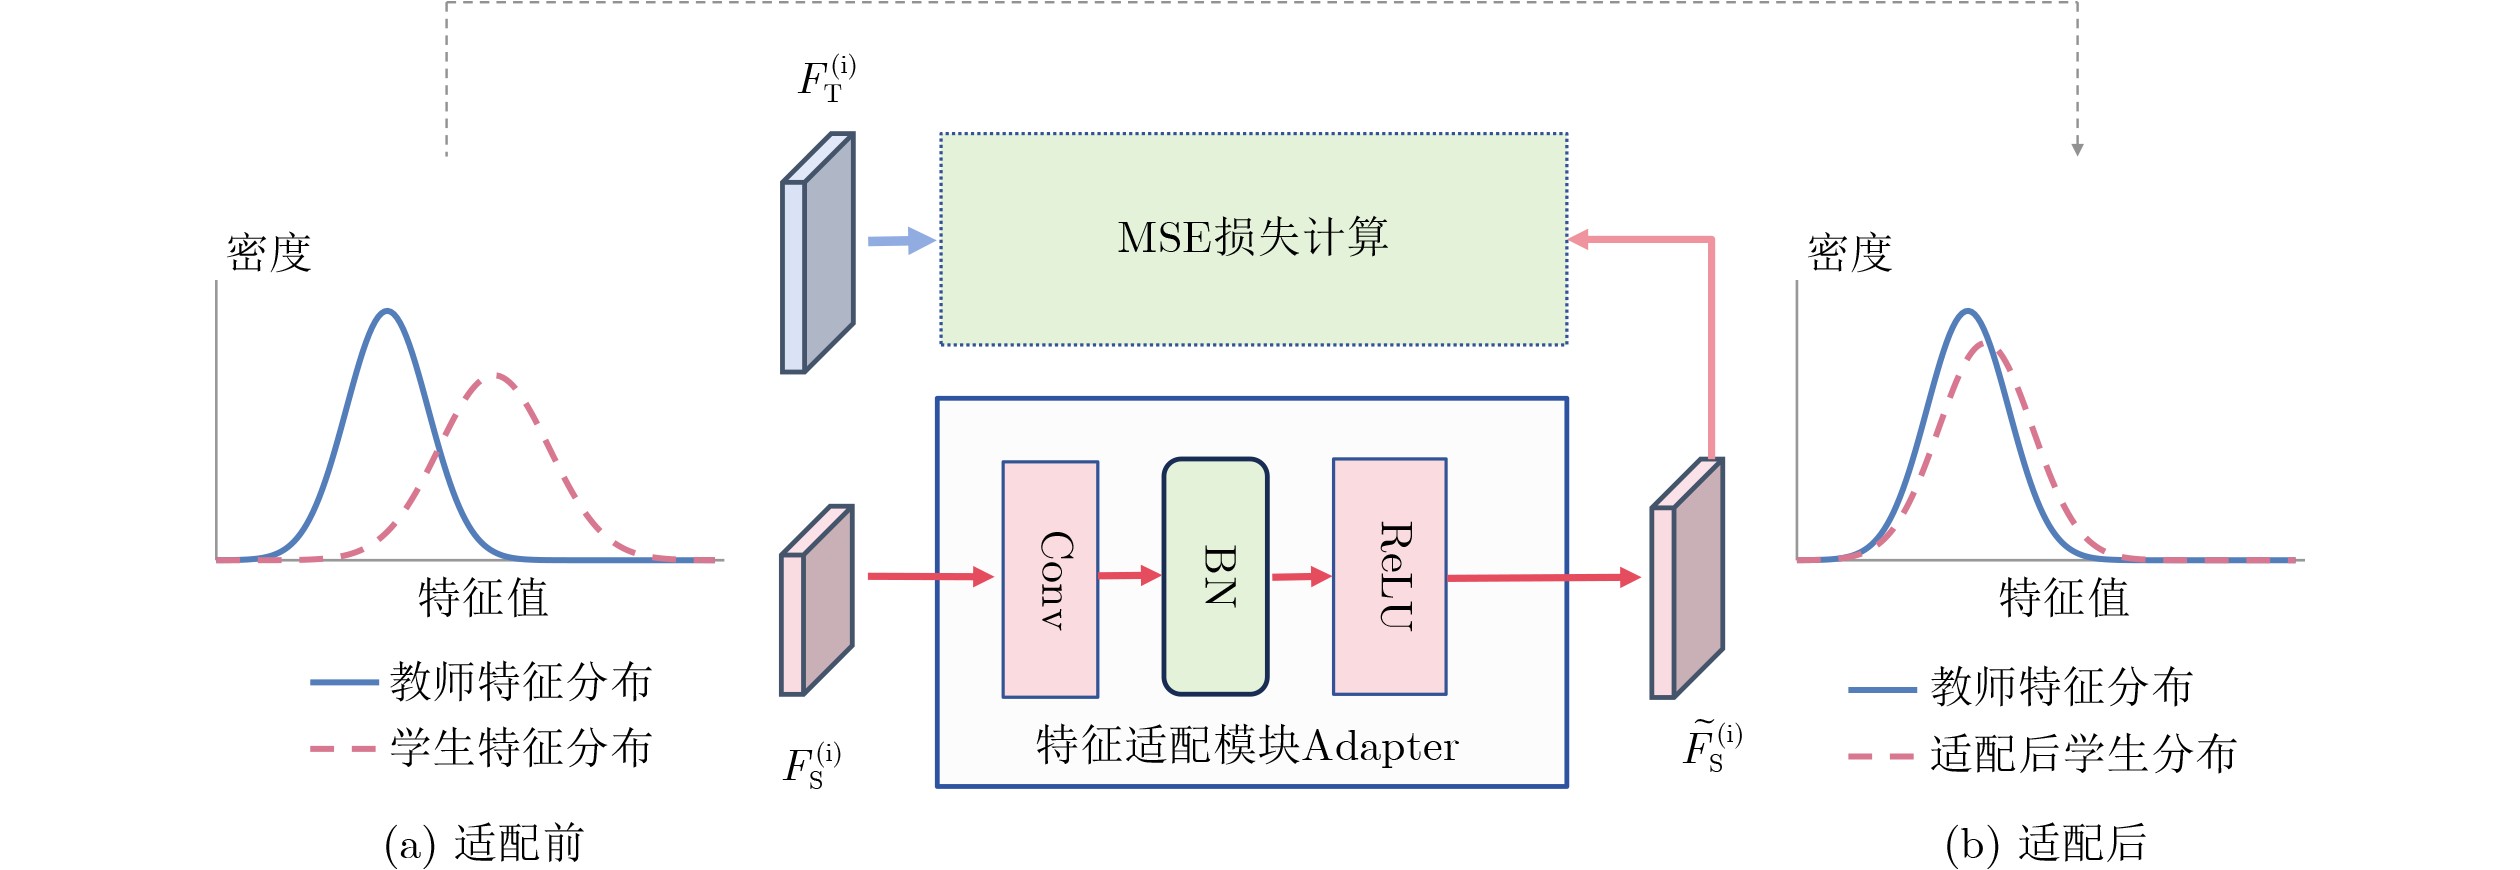
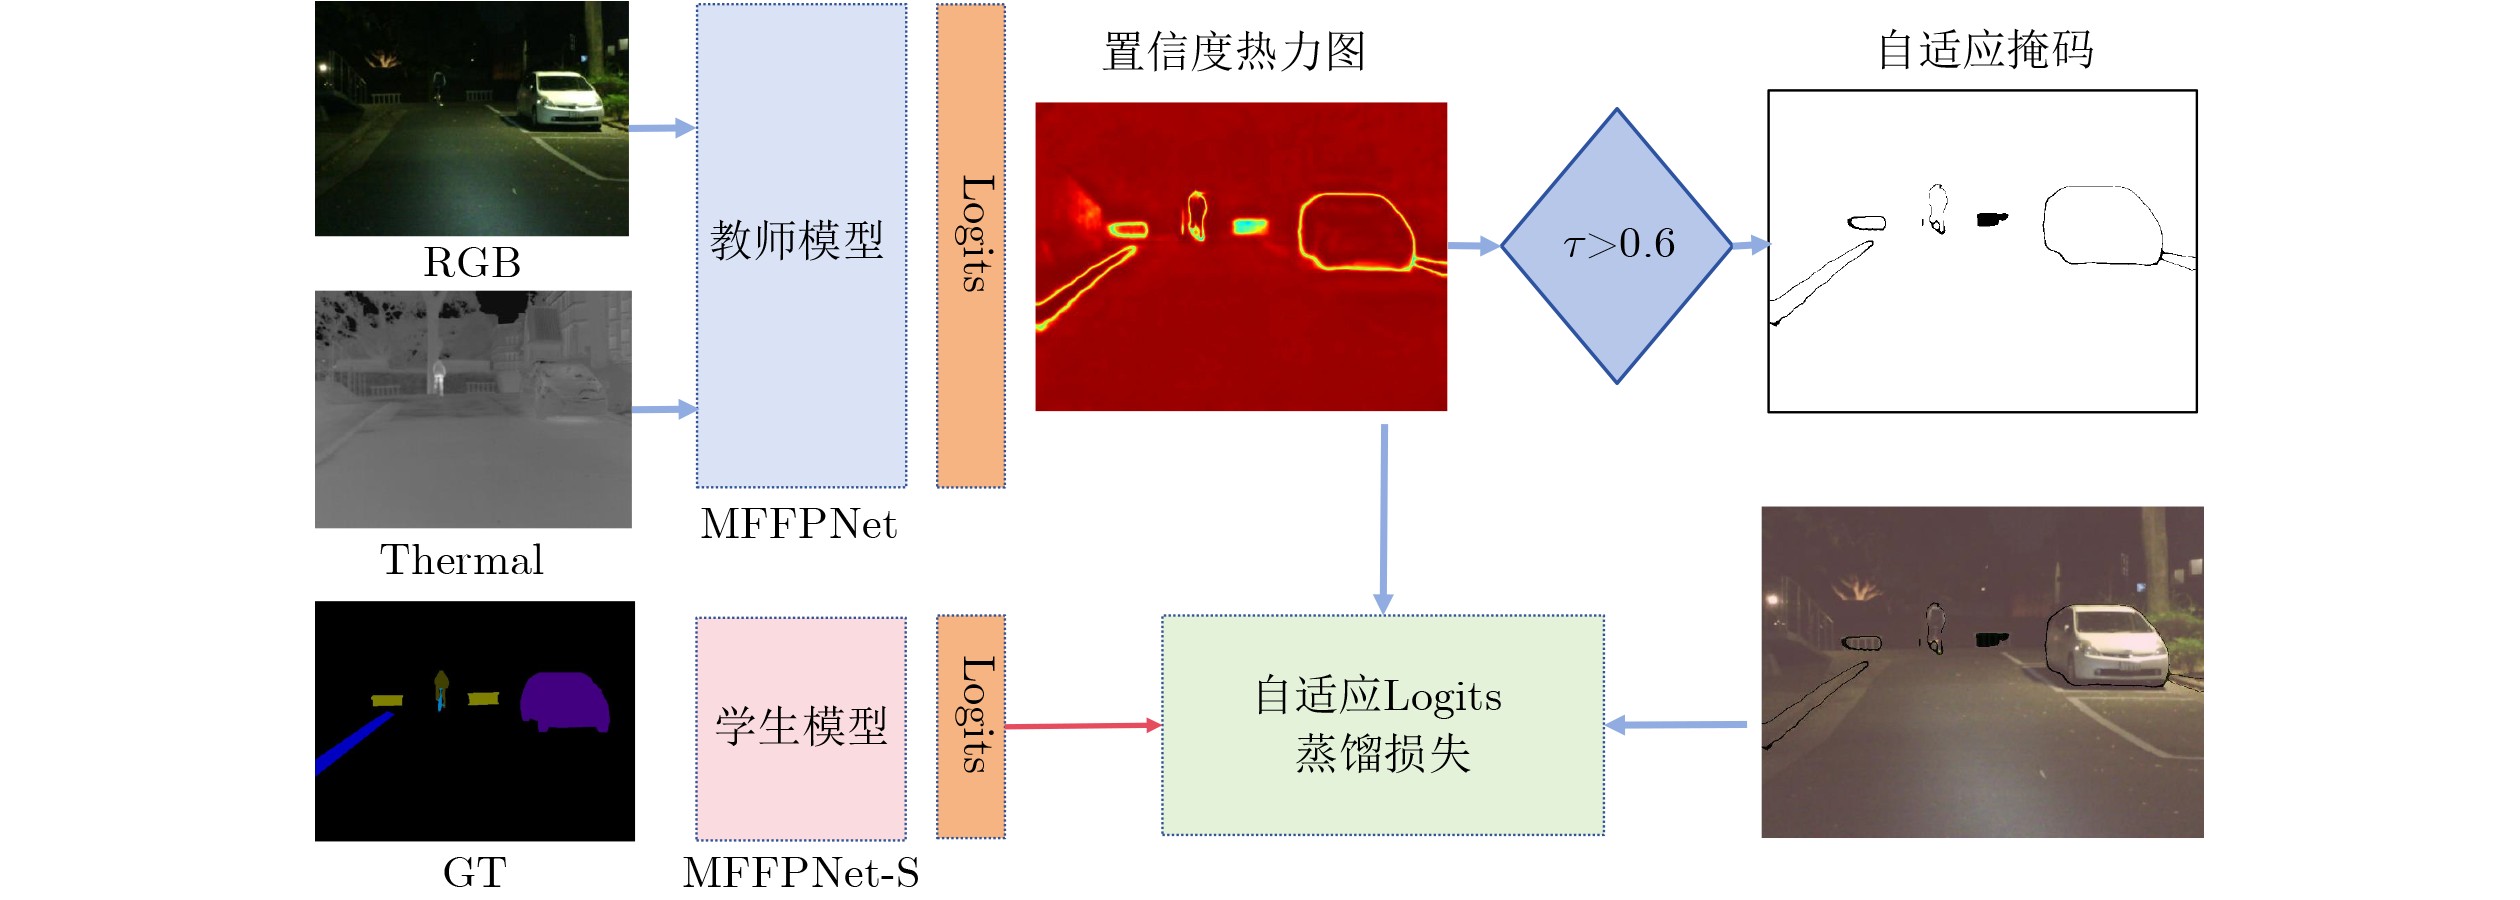
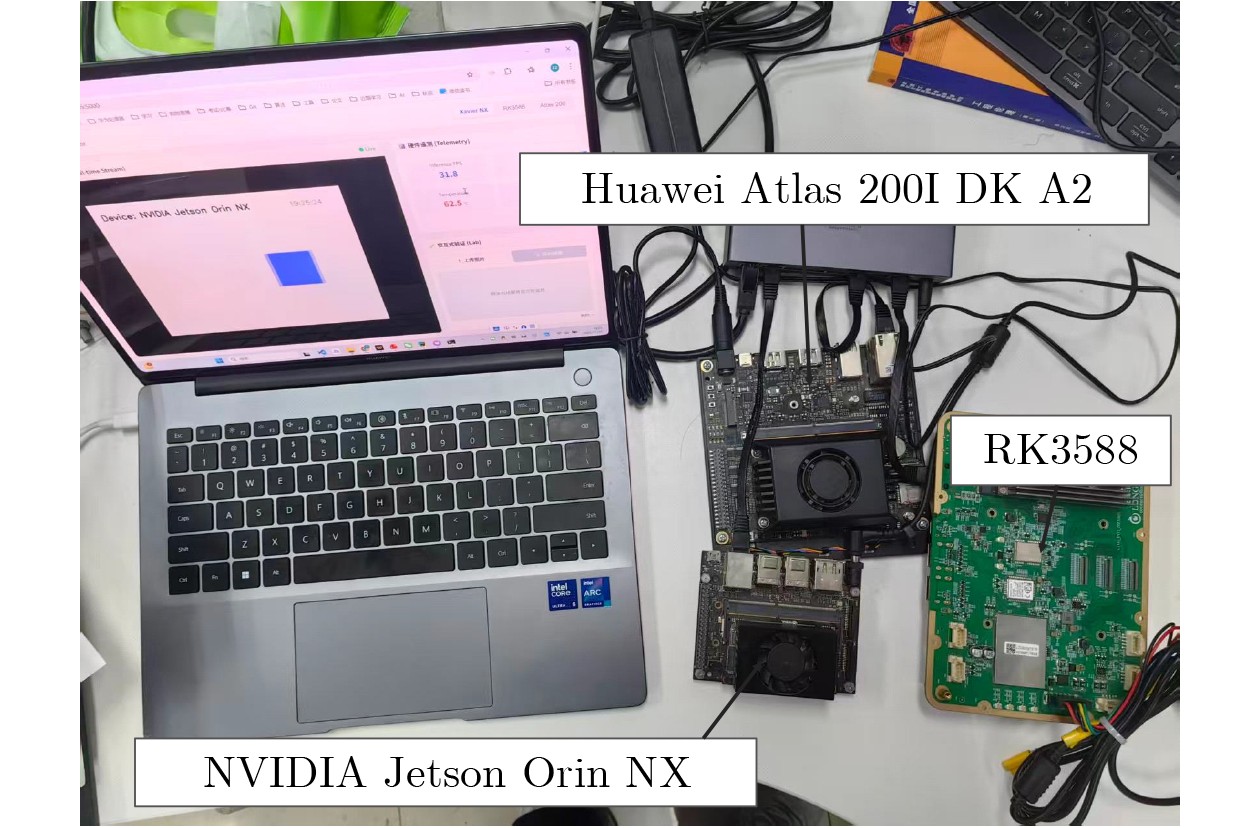
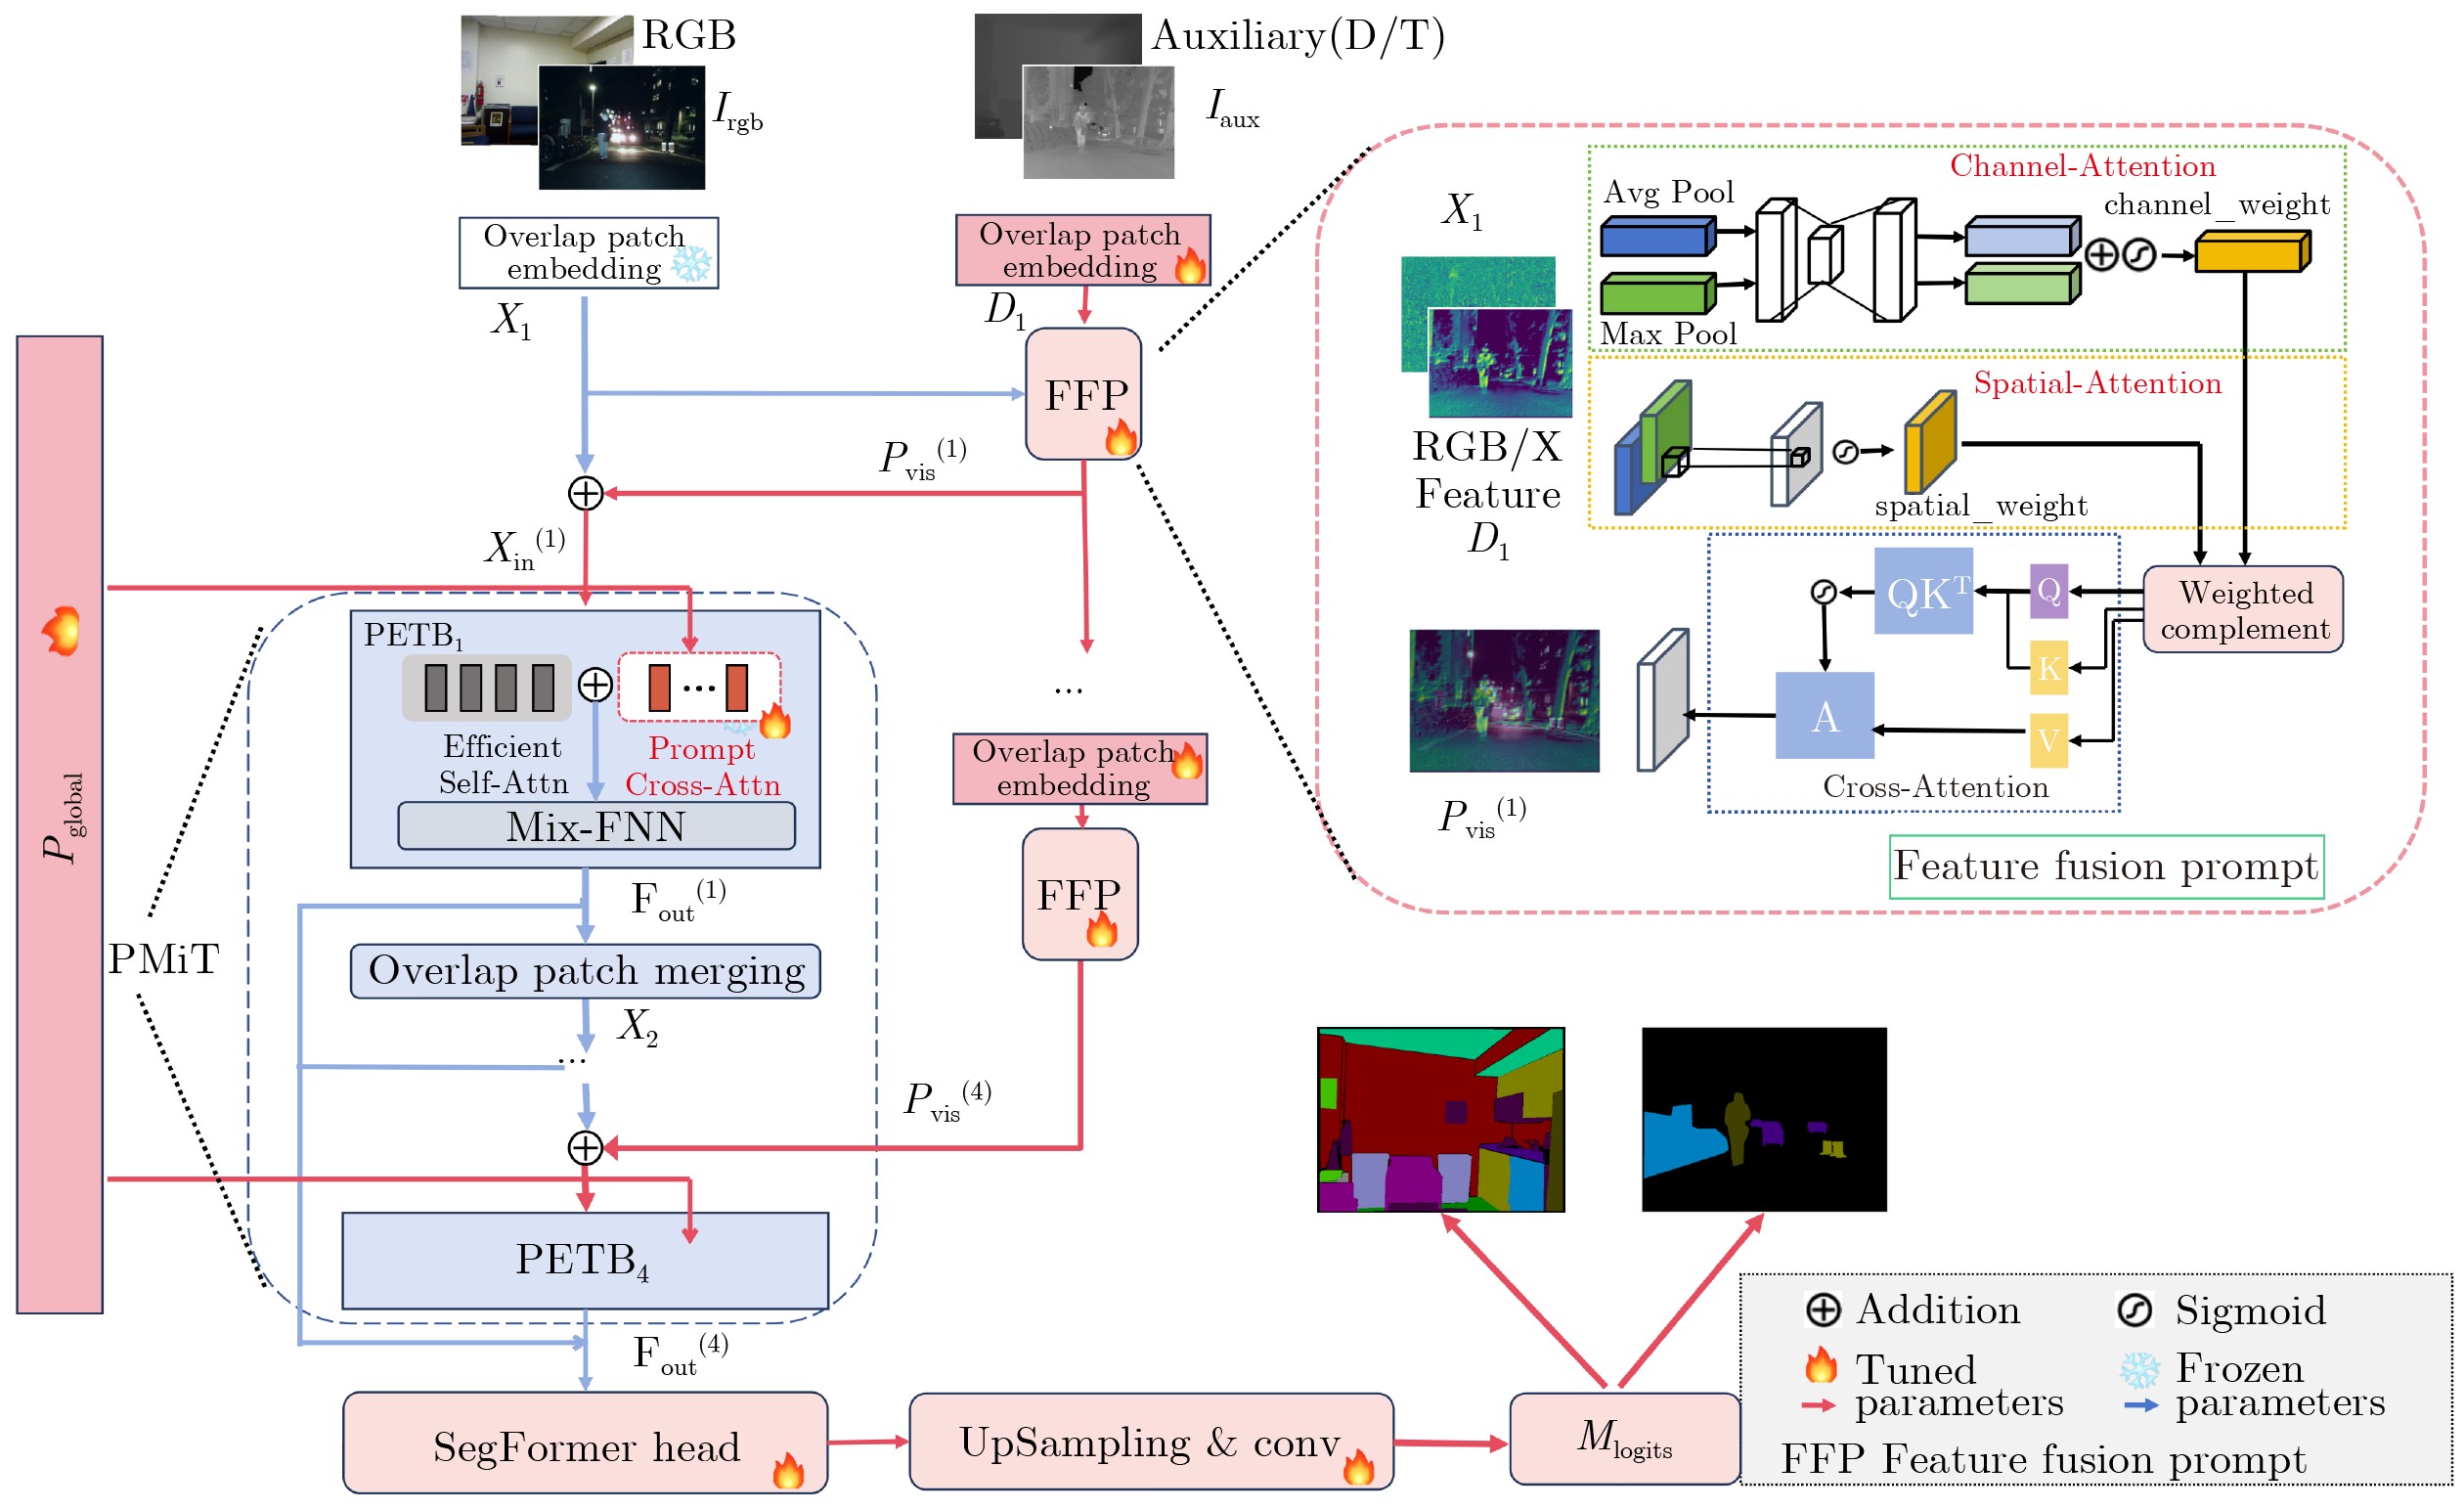
Objective Semantic segmentation assigns a semantic category to each image pixel and supports scene understanding in autonomous driving and robot navigation. Methods based on visible-light images can lose accuracy under low illumination, strong glare, and occlusion. Thermal infrared and depth images provide complementary information, but extracting features with two full backbone networks increases model size and computational cost. These costs limit deployment on embedded devices with restricted computing resources. Parameter-efficient adaptation reduces the number of weights updated during training, while a large pretrained backbone can still impose substantial inference overhead. Model compression and runtime optimization are therefore also needed. This study develops a multi-modal segmentation framework that combines dynamic visual prompts, structured knowledge distillation, and deployment optimization. The objective is to improve the use of auxiliary modality information with limited trainable parameters, transfer the resulting representations to a smaller student network, and improve inference throughput across heterogeneous embedded platforms. Methods A Multi-modal Feature Fusion Prompt Network (MFFPNet) is constructed using an ImageNet-pretrained Mix Transformer B5 (MiT-B5) backbone and a SegFormer decoder. Most pretrained backbone parameters remain frozen, while the prompt, fusion, normalization, and decoding components are adapted to the segmentation task. The encoder retains four hierarchical stages. A lightweight Feature Fusion Prompt (FFP) module encodes thermal infrared or depth information into dynamic visual prompts, which are added to visible-light features. The prompt generated at one stage is passed to the next stage after spatial and channel adjustment, allowing auxiliary information to contribute at multiple feature scales. Global learnable prompts provide an additional mechanism for adapting the pretrained representations to the task ( Fig. 1 ). Within the FFP module, spatial and channel attention assign different weights to the two modalities. Complementary feature reweighting is followed by cross-attention to capture cross-modal relationships and generate the visual prompt. The decoder aggregates outputs from all four stages to produce pixelwise predictions. Training combines label-smoothed cross-entropy and Dice losses to account for pixel classification and regional overlap. The backbone is initialized from pretrained weights, and training uses stochastic gradient descent with momentum and polynomial learning-rate decay. Data augmentation includes multi-scale resizing, random cropping, horizontal flipping, and photometric perturbations. For model compression, the trained MFFPNet serves as a frozen teacher in an offline distillation framework. MFFPNet-S uses MiT-B1 as its main student backbone, with MiT-B2 also evaluated on NYUDv2 (Fig. 4 ). A feature adapter applies convolution, batch normalization, and a rectified linear unit to reduce differences between student and teacher features (Fig. 5 ). Distillation combines feature content, channel relations, spatial structure, and logit supervision. A confidence mask emphasizes teacher predictions in regions with higher confidence, while a global supervision term and ground-truth labels retain training information outside the selected regions. Local and global supervision together preserve structural information while reducing the influence of low-confidence local predictions (Fig. 6 ). For deployment, Open Neural Network Exchange (ONNX) provides an intermediate model representation for platform-specific compilation. TensorRT uses half precision on NVIDIA Jetson Orin NX, the Compute Architecture for Neural Networks (CANN) software stack supports Huawei Atlas 200I DK A2, and the Rockchip Neural Network (RKNN) toolchain supports RK3588. Mixed precision on RK3588 retains higher precision for sensitive attention and output layers. Containerized environments and a common inference interface support deployment, while a three-stage asynchronous pipeline overlaps data loading, inference, and network communication.Results and Discussions Evaluation covers the MFNet RGB-Thermal and NYUDv2 RGB-Depth datasets. On MFNet, MFFPNet achieves 63.3% mean Intersection over Union (mIoU) with 9.4 million trainable parameters, approximately 10.4% of its 90.4 million total parameters. Its mIoU exceeds the listed CRM-B, DPLNet, and MixPrompt results by 1.9, 5.0, and 3.2 percentage points, respectively. MixPrompt uses fewer trainable parameters, indicating a tradeoff between segmentation accuracy and adaptation size ( Table 2 ). Visual comparisons illustrate improved pedestrian contours under challenging nighttime illumination (Fig. 2 ). On NYUDv2, MFFPNet reaches 60.6% mIoU with single-scale testing, compared with 58.3% for DPLNet under the same testing mode. The multi-scale DPLNet and MixPrompt results use a different evaluation mode and do not establish a comparison under identical testing conditions (Table 3 ). Indoor examples show finer object boundaries and better separation of visually similar regions (Fig. 3 ). Ablation results associate the global prompt and full fusion module with improved segmentation performance (Table 4 ). Removing cross-attention reduces MFNet mIoU from 63.3% to 62.1% (Table 5 ). Fusion across all four stages also exceeds insertion at only the first or last stage, supporting the use of information at multiple resolutions (Table 6 ). On MFNet, the MiT-B1 student achieves 56.2% mIoU with approximately 18.1 million parameters and 19.6 GFLOPs, compared with 63.3% mIoU, 90.4 million parameters, and 122.8 GFLOPs for the teacher. The student therefore retains about 88.8% of the teacher's mIoU at 20.0% of its parameter count and reduces computation by approximately 84%. Its measured inference speed is 23.9 frames per second (FPS), compared with 10.0 FPS for the teacher (Table 8 ). On NYUDv2, distillation raises the MiT-B1 student's mIoU from 38.6% to 42.9%, a gain of 4.3 percentage points. The MiT-B2 student reaches 48.5%, providing higher accuracy with a larger model (Table 9 ). The separate MFNet distillation ablation reports successive improvements as the supervision components are added (Table 10 ). In synchronous deployment tests, the student achieves 55.7% mIoU at 48.6 FPS on Jetson Orin NX, 51.5% at 31.5 FPS on Atlas 200I DK A2, and 49.4% at 28.6 FPS with mixed precision on RK3588. The RK3588 INT8 configuration reaches 31.2 FPS but lowers mIoU to 41.1%, illustrating the accuracy cost of more aggressive quantization (Table 12 ). Over a continuous1000 -frame input, asynchronous execution raises throughput to 68.5, 41.2, and 34.8 FPS on the three platforms, respectively, corresponding to gains of 40.9%, 30.8%, and 21.7% over their serial configurations (Table 13 ).Conclusions The results support dynamic visual prompting as a parameter-efficient approach to RGB-Thermal and RGB-Depth semantic segmentation. Structured distillation reduces the inference cost of the large teacher while retaining 88.8% of its mIoU on MFNet. The student results on NYUDv2 also indicate a tradeoff between model capacity and segmentation accuracy. Platform-specific compilation and asynchronous scheduling provide further throughput improvements, while the deployment results show that quantization can materially reduce segmentation accuracy. The framework thus addresses training adaptation, model compression, and runtime execution as complementary aspects of embedded deployment. Future work will investigate modality completion using generative models or cross-modal distillation to improve segmentation when auxiliary sensor information is unavailable. -
Key words:
- semantic segmentation /
- multi-modal fusion /
- visual prompt /
- knowledge distillation /
- embedded platform
-
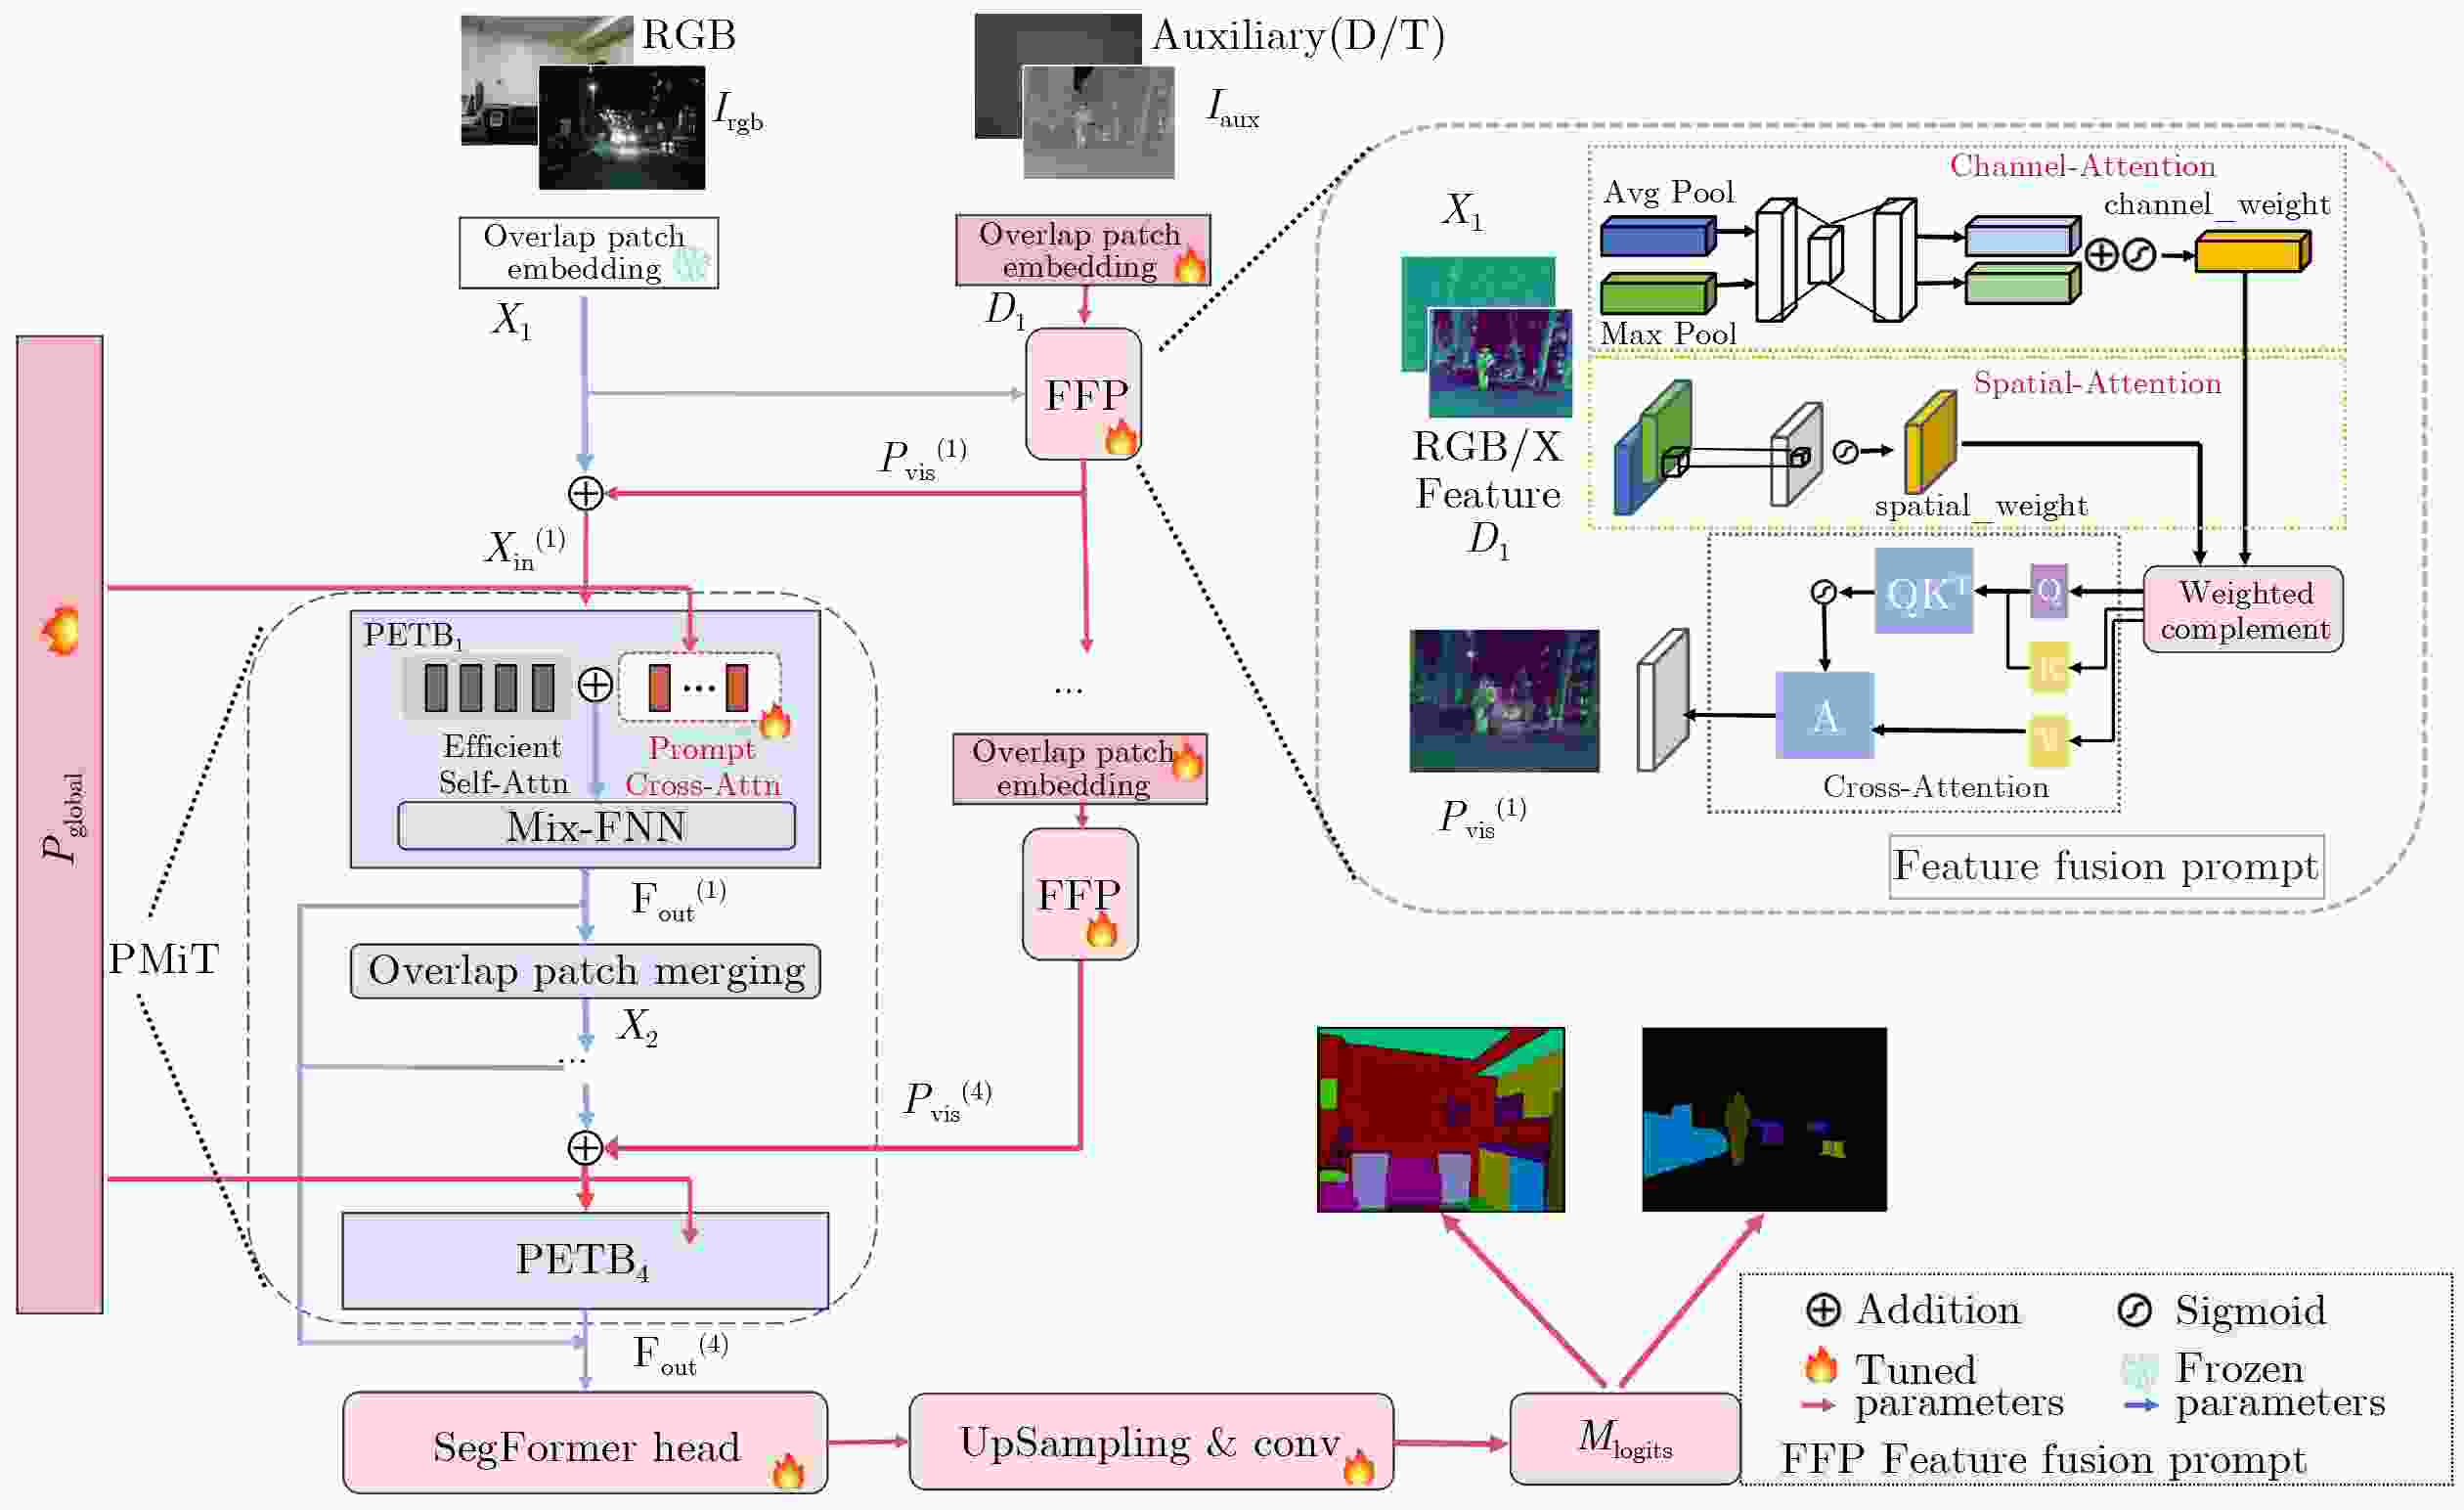
图 1 多模态特征融合的语义分割模型MFFPNet结构
图中左侧蓝色虚线框表示PMiT模块,内部依次包含4个PETB模块,右侧为FFP内部结构;红色模块代表需更新的可训练参数,蓝色模块代表冻结的预训练参数。
表 1 实验参数配置
属性名称 数据信息 运行环境 Ubuntu 22.04 CUDA版本 12.4 显存容量 48 GB GDDR6 输入分辨率 480×640 Batch size 6 优化器 SGD epoch 1000 初始学习率 0.005(SGD)  下载: 导出CSV
表 3 在NYUDv2数据集上的指标对比
Method Backbone 测试方式 mIoU (%) 总参数量(M) 训练参数量(M) TokenFusion-B3[12] MiT-B3 SS 54.2 45.9 45.9 CMX-B5[6] MiT-B5 MS 56.9 181.1 181.1 CMNeXt[20] MiT-B4 MS 56.9 119.6 119.6 DFormer-L[32] DFormer-L MS 57.2 39.0 39.0 DPLNet[9] MiT-B5 SS 58.3 88.6 7.2 DPLNet[9] MiT-B5 MS 59.3 88.6 7.2 MixPrompt[10] MiT-B5 MS 61.2 87.2 5.7 Ours MiT-B5 SS 60.6 90.4 9.4
下载: 导出CSV
表 4 核心模块有效性消融实验
模型配置 $ {P}_{\text{global}} $ $ {F}_{\text{FFP}} $ MFNet
mIoU(%)NYUDv2
mIoU(%)训练参数量(M) Baseline (Frozen MiT-B5 Backbone)[26] - - 40.5 48.4 - Baseline + Global Prompt √ - 45.1 55.0 ~0.1 Baseline + Global Prompt + Simple Add √ - 58.6 57.4 2.6 MFFPNet (Ours) √ √ 63.3 60.6 9.4
下载: 导出CSV
表 5 FFP内部融合策略消融实验
融合策略 描述 mIoU(%) Element-wise Sum 简单的逐元素相加融合 56.5 Concatenation 通道拼接后卷积降维融合 59.8 Channel + Spatial Attn Only 仅使用双路注意力加权 60.5 w/o Cross-Attention 保留互补加权,不使用交叉注意力 62.1 c/s Attn + Cross-Attn (Ours) 完整的$ {F}_{\text{FFP}} $模块 63.3
下载: 导出CSV
表 7 MFFPNet关键超参数敏感性分析(MFNet数据集)
实验编号 参数设置 mIoU(%) E0-B5 λ1=0.5,λ2=0.5(默认) 63.3 E1 λ1=0.3,λ2=0.7 62.8 E2 λ1=0.7,λ2=0.3 62.8 E0-B5 α=0.1(默认) 63.3 E3 α=0 63.2 E4 α=0.2 63.1
下载: 导出CSV
表 8 在MFNet数据集上的性能对比
方法 总参数量(M) 训练参数量
(M)FLOPs
(G)帧率/
(帧·s–1)mIoU
(%)Teacher 90.4 9.4 122.8 10.0 63.3 Student 18.1 18.1 19.6 23.9 56.2
下载: 导出CSV
表 9 NYUDv2数据集上的模型性能对比与增益分析
模型 总参数量
(M)FLOPs
(G)帧率/
(帧·s–1)mIoU
(%)Teacher(MFFPNet) 90.4 122.8 9.83 60.6 Student-B1(w/o KD) 18.05 19.6 25.06 38.6 MFFPNet-S (MiT-B1) 18.05 19.6 25.59 42.9 MFFPNet-S (MiT-B2) 29.33 29.1 20.09 48.5
下载: 导出CSV
表 10 不同蒸馏组件对模型性能的影响(MFNet数据集)
模型配置 $ {\mathcal{L}}_{\text{logit}} $ $ {\mathcal{L}}_{\text{feat}} $ $ {\mathcal{L}}_{\text{rel}} $ $ {\mathcal{L}}_{\text{pair}} $ mIoU(%) Student Baseline(MiT-B1) - - - - 38.6 + Adaptive Logit Loss √ - - - 45.2 + Feature Content Loss √ √ - - 51.6 + Channel Relation Loss √ √ √ - 53.4 MFFPNet-S(Ours) √ √ √ √ 56.2 MFFPNet(Teacher) - - - - 63.3
下载: 导出CSV
表 11 MFFPNet-S蒸馏权重敏感性分析(MFNet数据集)
实验编号 参数设置 mIoU(%) E0-B1 ρ=0.7(默认) 56.21 E5 ρ=0.5 55.60 E6 ρ=0.9 56.18
下载: 导出CSV
表 12 异构平台模型推理性能对比
模型配置 部署平台 量化精度 mIoU
(%)帧率/
(帧·s–1)MFFPNet(Teacher) Server(L40S) FP32 63.3 10.0 MFFPNet-S (PyTorch) Server(L40S) FP32 56.2 23.9 MFFPNet-S(TensorRT) Jetson Orin FP16 55.7 48.6 MFFPNet-S (CANN) Atlas 200I FP16 51.5 31.5 MFFPNet-S (RKNN) RK3588 Hybrid 49.4 28.6 MFFPNet-S (RKNN) RK3588 INT8 41.1 31.2
下载: 导出CSV
表 13 多线程流水线优化效果对比
硬件平台 运行模式 CPU利用率
(%)GPU/NPU
利用率(%)帧率/
(帧·s–1)Jetson Orin NX 串行 35 42 48.6 并行 68 95 68.5 Atlas 200I DK A2 串行 55 38 31.5 并行 92 65 41.2 RK3588 串行 20 85 28.6 并行 35 96 34.8
下载: 导出CSV
-
[1] FENG Di, HAASE-SCHÜTZ C, ROSENBAUM L, et al. Deep multi-modal object detection and semantic segmentation for autonomous driving: Datasets, methods, and challenges[J]. IEEE Transactions on Intelligent Transportation Systems, 2021, 22(3): 1341–1360. doi: 10.1109/TITS.2020.2972974. [2] WANG Li, ZHANG Xinyu, SONG Ziying, et al. Multi-modal 3D object detection in autonomous driving: A survey and taxonomy[J]. IEEE Transactions on Intelligent Vehicles, 2023, 8(7): 3781–3798. doi: 10.1109/TIV.2023.3264658. [3] 梁燕, 李俊范, 邵凯, 等. 空间信息引导扩散的遥感图像域自适应语义分割[J]. 电子与信息学报, 2026, 48(7): 2829–2842. doi: 10.11999/JEIT260031.LIANG Yan, LI Junfan, SHAO Kai, et al. Spatial information-guided diffusion for domain adaptation semantic segmentation of remote sensing images[J]. Journal of Electronics & Information Technology, 2026, 48(7): 2829–2842. doi: 10.11999/JEIT260031. [4] WANG Changshuo, WANG Chen, LI Weijun, et al. A brief survey on RGB-D semantic segmentation using deep learning[J]. Displays, 2021, 70: 102080. doi: 10.1016/j.displa.2021.102080. [5] HAZIRBAS C, MA Lingni, DOMOKOS C, et al. FuseNet: Incorporating depth into semantic segmentation via fusion-based CNN architecture[C]. 13th Asian Conference on Computer Vision, Taipei, China, 2016: 213–228. doi: 10.1007/978-3-319-54181-5_14. [6] ZHANG Jiaming, LIU Huayao, YANG Kailun, et al. CMX: Cross-modal fusion for RGB-X semantic segmentation with transformers[J]. IEEE Transactions on Intelligent Transportation Systems, 2023, 24(12): 14679–14694. doi: 10.1109/TITS.2023.3300537. [7] SUN Yuxiang, ZUO Weixun, and LIU Ming. RTFNet: RGB-thermal fusion network for semantic segmentation of urban scenes[J]. IEEE Robotics and Automation Letters, 2019, 4(3): 2576–2583. doi: 10.1109/LRA.2019.2904733. [8] CAPRA M, BUSSOLINO B, MARCHISIO A, et al. Hardware and software optimizations for accelerating deep neural networks: Survey of current trends, challenges, and the road ahead[J]. IEEE Access, 2020, 8: 225134–225180. doi: 10.1109/ACCESS.2020.3039858. [9] DONG Shaohua, FENG Yunhe, YANG Qing, et al. Efficient multimodal semantic segmentation via dual-prompt learning[C]. 2024 IEEE/RSJ International Conference on Intelligent Robots and Systems, Abu Dhabi, United Arab Emirates, 2024: 14196–14203. doi: 10.1109/IROS58592.2024.10801872. [10] HAO Zhiwei, XIAO Zhongyu, GUO Jianyuan, et al. MixPrompt: Efficient mixed prompting for multimodal semantic segmentation[C]. The Thirty-ninth Annual Conference on Neural Information Processing Systems, San Diego, USA, 2025: 39255–39282. doi: 10.52202/085713-1173. [11] 毛秀华, 张强, 阮航, 等. 多任务协同的多模态遥感目标分割算法[J]. 电子与信息学报, 2024, 46(8): 3363–3371. doi: 10.11999/JEIT231267.MAO Xiuhua, ZHANG Qiang, RUAN Hang, et al. Multitask collaborative multi-modal remote sensing target segmentation algorithm[J]. Journal of Electronics & Information Technology, 2024, 46(8): 3363–3371. doi: 10.11999/JEIT231267. [12] WANG Yikai, CHEN Xinghao, CAO Lele, et al. Multimodal token fusion for vision transformers[C]. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, USA, 2022: 12176–12185. doi: 10.1109/cvpr52688.2022.01187. [13] ZHANG Yang, XIONG Chenyun, LIU Junjie, et al. Spatial information-guided adaptive context-aware network for efficient RGB-D semantic segmentation[J]. IEEE Sensors Journal, 2023, 23(19): 23512–23521. doi: 10.1109/JSEN.2023.3304637. [14] 李晓玲, 陈后金, 李艳凤, 等. 多重关系感知的红外与可见光图像融合网络[J]. 电子与信息学报, 2024, 46(5): 2217–2227. doi: 10.11999/JEIT231062.LI Xiaoling, CHEN Houjin, LI Yanfeng, et al. Infrared and visible image fusion network with multi-relation perception[J]. Journal of Electronics & Information Technology, 2024, 46(5): 2217–2227. doi: 10.11999/JEIT231062. [15] DENG Fuqin, FENG Hua, LIANG Mingjian, et al. FEANet: Feature-enhanced attention network for RGB-thermal real-time semantic segmentation[C]. IEEE/RSJ International Conference on Intelligent Robots and Systems, Prague, Czech Republic, 2021: 4467–4473. doi: 10.1109/iros51168.2021.9636084. [16] HA Qishen, WATANABE K, KARASAWA T, et al. MFNet: Towards real-time semantic segmentation for autonomous vehicles with multi-spectral scenes[C]. 2017 IEEE/RSJ International Conference on Intelligent Robots and Systems, Vancouver, Canada, 2017: 5108–5115. doi: 10.1109/iros.2017.8206396. [17] ZHOU Wujie, LIN Xinyang, LEI Jingsheng, et al. MFFENet: Multiscale feature fusion and enhancement network for RGB–thermal urban road scene parsing[J]. IEEE Transactions on Multimedia, 2022, 24: 2526–2538. doi: 10.1109/TMM.2021.3086618. [18] LIU Jinfu, ZHOU Wujie, CUI Yueli, et al. GCNet: Grid-like context-aware network for RGB-thermal semantic segmentation[J]. Neurocomputing, 2022, 506: 60–67. doi: 10.1016/j.neucom.2022.07.041. [19] ZHOU Wujie, DONG Shaohua, XU Caie, et al. Edge-aware guidance fusion network for RGB-thermal scene parsing[C]. Proceedings of the 36th AAAI Conference on Artificial Intelligence, 2022: 3571–3579. doi: 10.1609/aaai.v36i3.20269. (查阅网上资料,未找到本条文献会议地,请确认). [20] ZHANG Jiaming, LIU Ruiping, SHI Hao, et al. Delivering arbitrary-modal semantic segmentation[C]. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, Canada, 2023: 1136–1147. doi: 10.1109/cvpr52729.2023.00116. [21] 周国宇, 张菁, 闫伊, 等. 聚焦注意力与紧致特征融合Transformer的城市遥感影像语义分割[J]. 电子与信息学报, 2025, 47(12): 4790–4800. doi: 10.11999/JEIT250812.ZHOU Guoyu, ZHANG Jing, YAN Yi, et al. A focused attention and feature compact fusion transformer for semantic segmentation of urban remote sensing images[J]. Journal of Electronics & Information Technology, 2025, 47(12): 4790–4800. doi: 10.11999/JEIT250812. [22] HAO Zhiwei, XIAO Zhongyu, LUO Yong, et al. PrimKD: Primary modality guided multimodal fusion for RGB-D semantic segmentation[C]. Proceedings of the 32nd ACM International Conference on Multimedia, Melbourne, Australia, 2024: 1943–1951. doi: 10.1145/3664647.3681253. [23] FERROD R, DANTAS C F, DI CARO L, et al. Revisiting cross-modal knowledge distillation: A disentanglement approach for RGBD semantic segmentation[C]. Joint European Conference on Machine Learning and Knowledge Discovery in Databases, Porto, Portugal, 2025: 492–508. doi: 10.1007/978-3-032-06078-5_28. [24] ZHOU Wujie, XIAO Yuxiang, LIU Yuanyuan, et al. FIMKD: Feature-implicit mapping knowledge distillation for RGB-D indoor scene semantic segmentation[J]. IEEE Transactions on Artificial Intelligence, 2024, 5(12): 6488–6499. doi: 10.1109/TAI.2024.3452052. [25] GUO Xiaodong, ZHOU Wujie, and LIU Tong. Contrastive learning-based knowledge distillation for RGB-thermal urban scene semantic segmentation[J]. Knowledge-Based Systems, 2024, 292: 111588. doi: 10.1016/j.knosys.2024.111588. [26] XIE Enze, WANG Wenhai, YU Zhiding, et al. SegFormer: Simple and efficient design for semantic segmentation with transformers[C]. Proceedings of the 35th International Conference on Neural Information Processing Systems, 2021: 924. (查阅网上资料, 未找到本条文献会议地, 请确认). [27] SZEGEDY C, VANHOUCKE V, IOFFE S, et al. Rethinking the inception architecture for computer vision[C]. Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Las Vegas, USA, 2016: 2818–2826. doi: 10.1109/cvpr.2016.308. [28] MILLETARI F, NAVAB N, and AHMADI S A. V-Net: Fully convolutional neural networks for volumetric medical image segmentation[C]. 2016 4th International Conference on 3D Vision, Stanford, USA, 2016: 565–571. doi: 10.1109/3dv.2016.79. [29] DENG Jia, DONG Wei, SOCHER R, et al. ImageNet: A large-scale hierarchical image database[C]. 2009 IEEE Conference on Computer Vision and Pattern Recognition, Miami, USA, 2009: 248–255. doi: 10.1109/cvpr.2009.5206848. [30] BOTTOU L. Large-scale machine learning with stochastic gradient descent[C]. Proceedings of 19th International Conference on Computational Statistics, Paris, France, 2010: 177–186. doi: 10.1007/978-3-7908-2604-3_16. [31] SHIN U, LEE K, KWEON I S, et al. Complementary random masking for RGB-thermal semantic segmentation[C]. 2024 IEEE International Conference on Robotics and Automation, Yokohama, Japan, 2024: 11110–11117. doi: 10.1109/icra57147.2024.10611200. [32] YIN Bowen, ZHANG Xuying, LI Zhongyu, et al. DFormer: Rethinking RGBD representation learning for semantic segmentation[C]. The 12th International Conference on Learning Representations, Vienna, Austria, 2024. -


 下载:



计量
- 文章访问数: 10
- HTML全文浏览量: 1
- PDF下载量: 0
- 被引次数: 0
