

Personalized Federated Learning with Synergistic Optimization of Hypernetwork Modulation and Reinforcement Learning
-
摘要: 联邦学习解决了传统集中式机器学习面临的隐私泄露与“数据孤岛”难题。然而联邦学习参与客户端的数据异质性会导致客户端模型漂移、泛化误差大、全局与局部知识融合低效等局限。针对以上问题,该文提出一种基于超网络参数调制与强化学习自适应融合的个性化联邦学习算法FedHR。FedHR利用超网络为联邦学习每个客户端生成专属调制参数,在保留全局通用知识的基础上嵌入本地数据分布特性,实现全局知识与个性化知识的有效融合。同时,引入深度确定性策略梯度强化学习机制,根据客户端实时训练状态动态分配调制权重,自适应地平衡全局一致性与本地个性化需求。实验结果表明,FedHR的全局与个性化模型准确率显著优于经典联邦学习基准算法,降低了总通信成本,且在异质性场景中展现出较强鲁棒性;消融实验进一步验证了强化学习动态调制的有效性。该文提出的FedHR算法为隐私保护场景下的分布式训练提供了通信高效、预测性能优异且能较好适配复杂异构环境的个性化解决方案。Abstract:
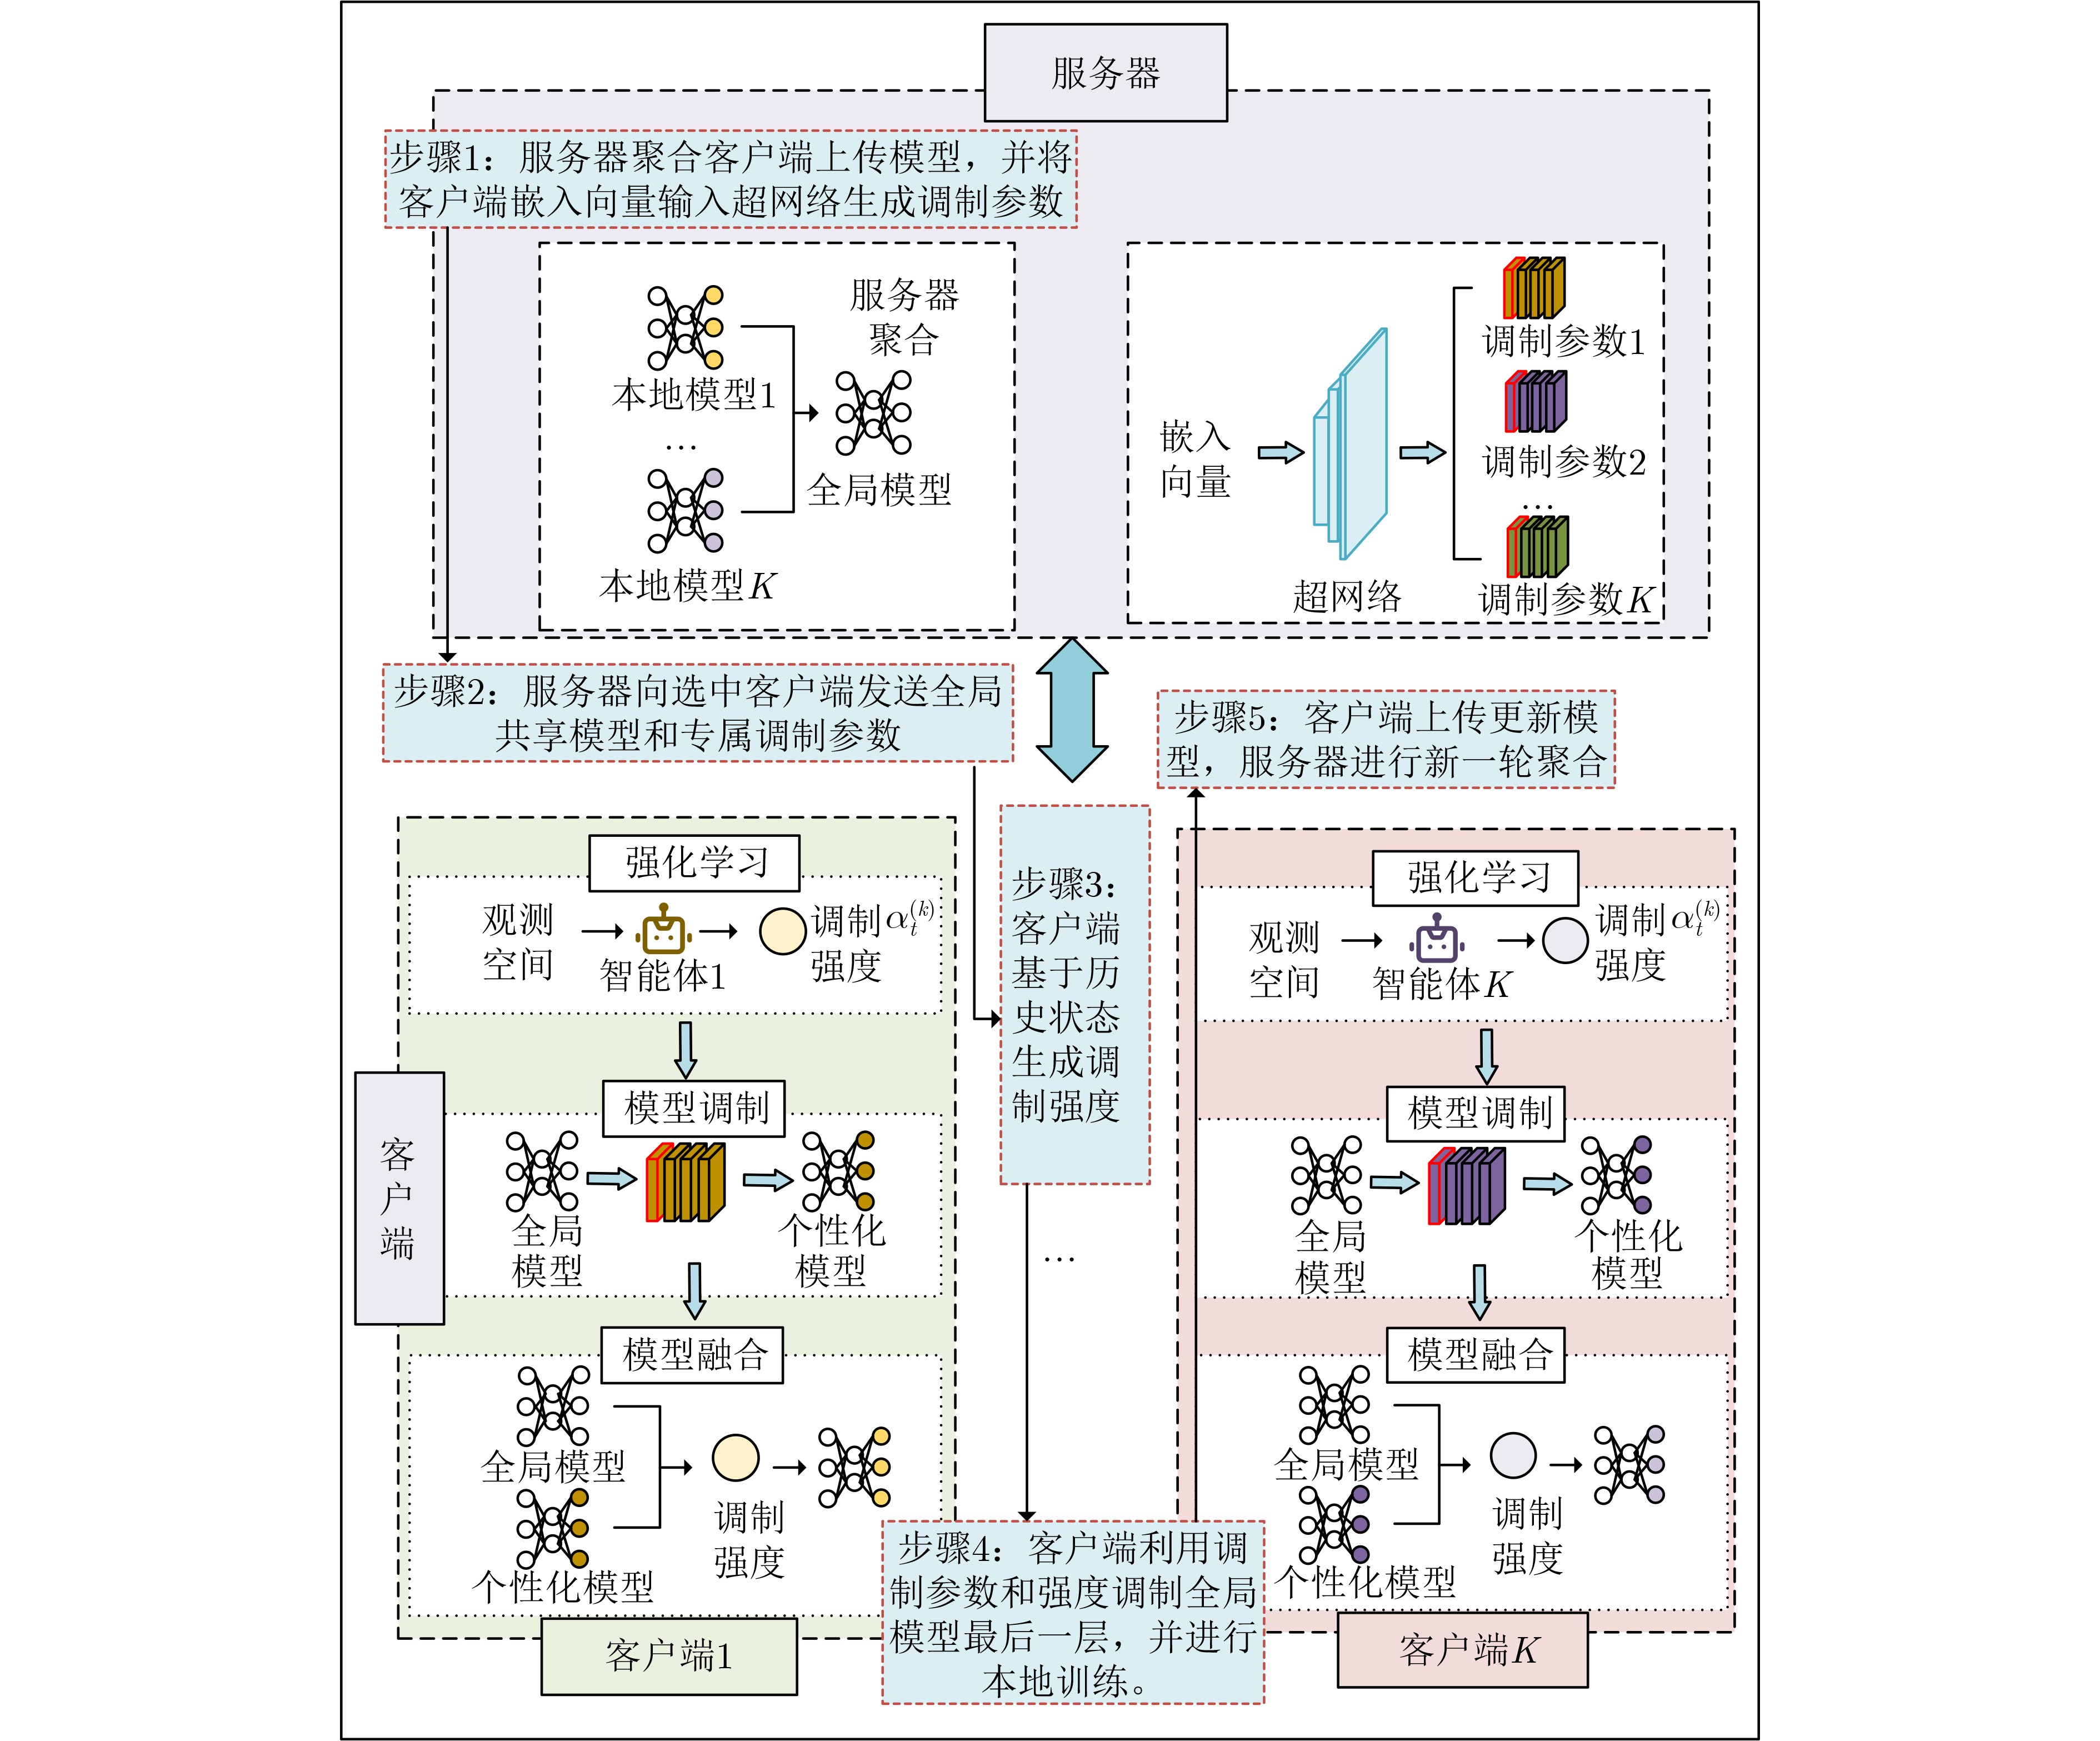
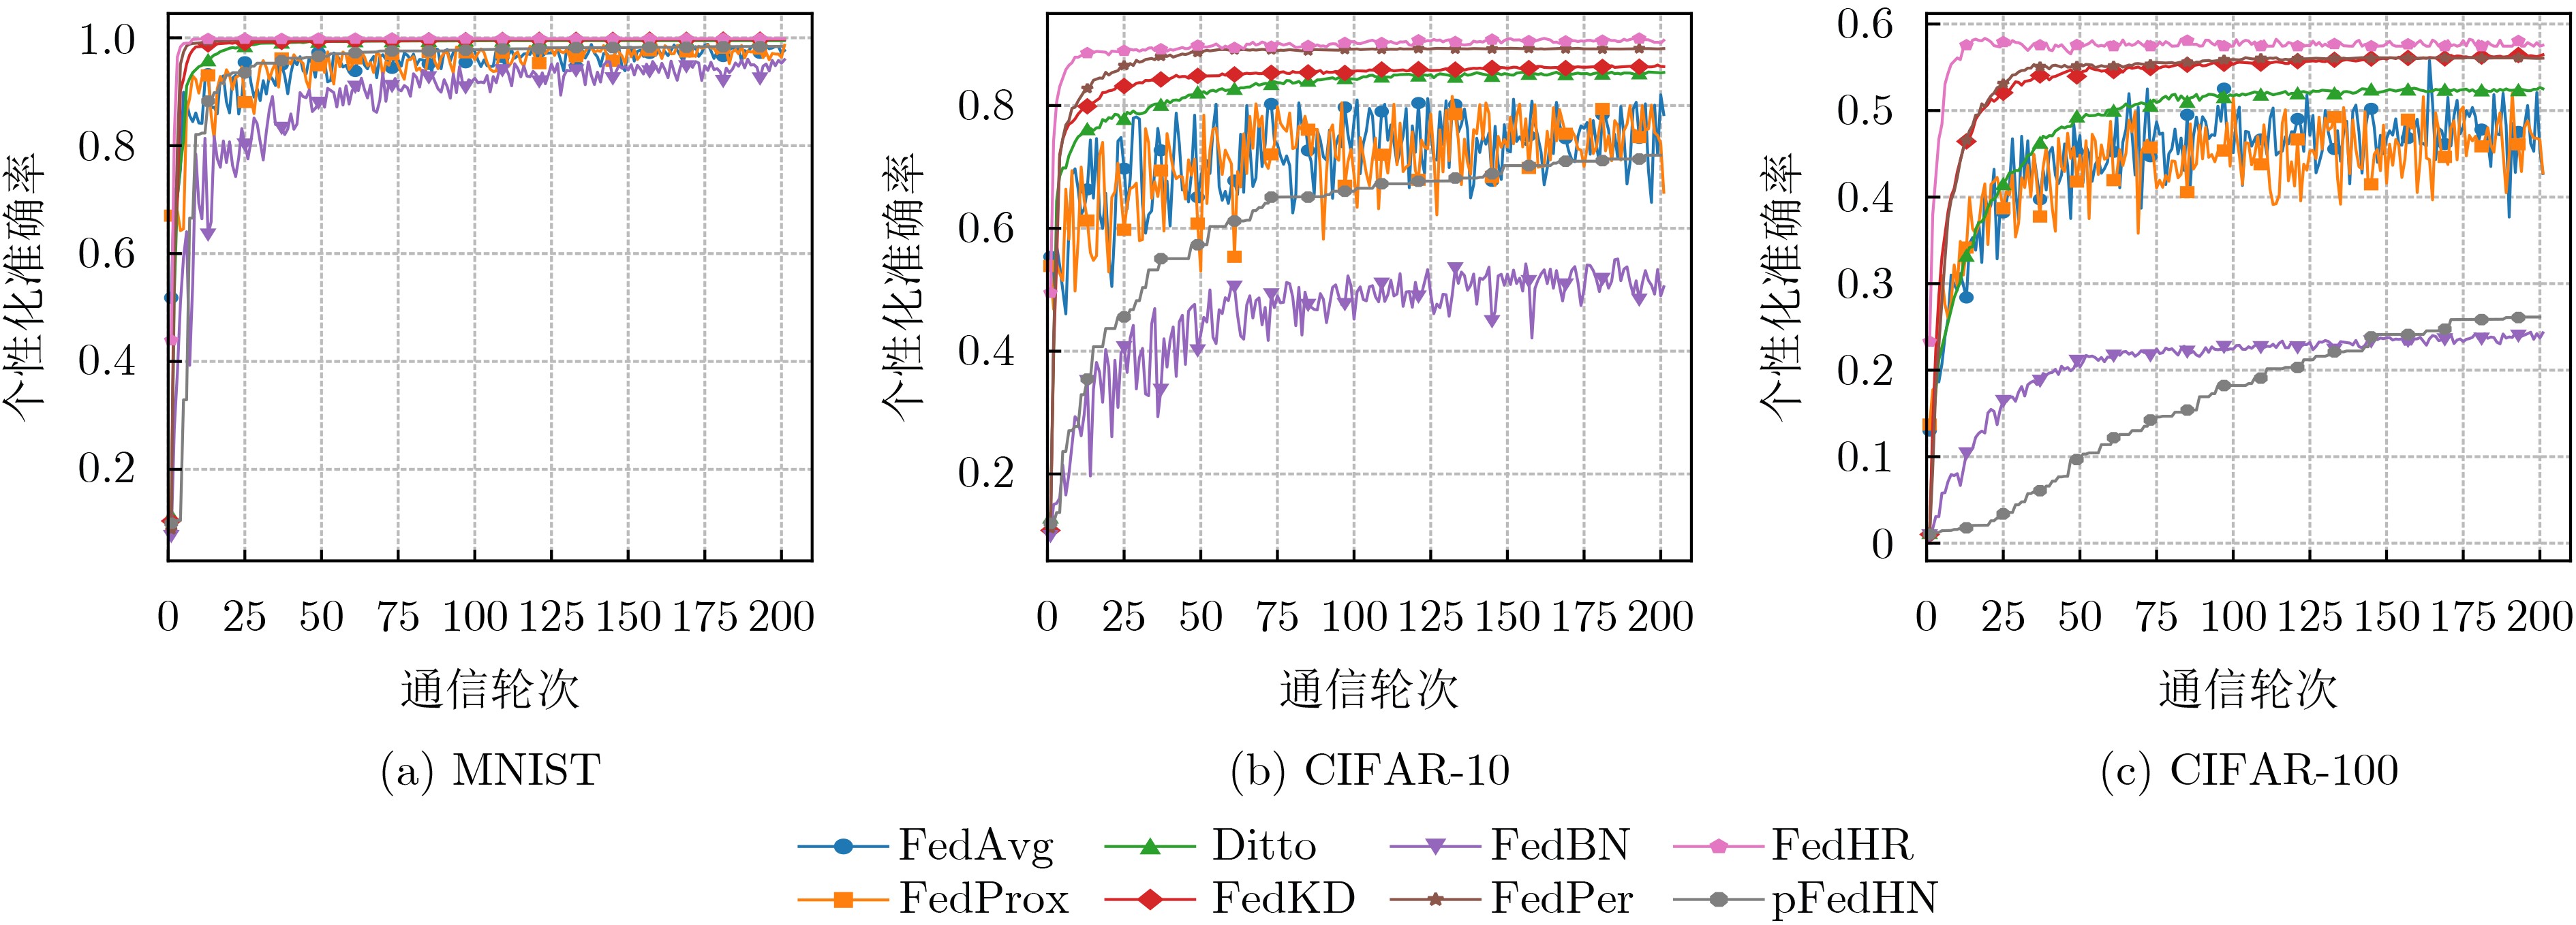
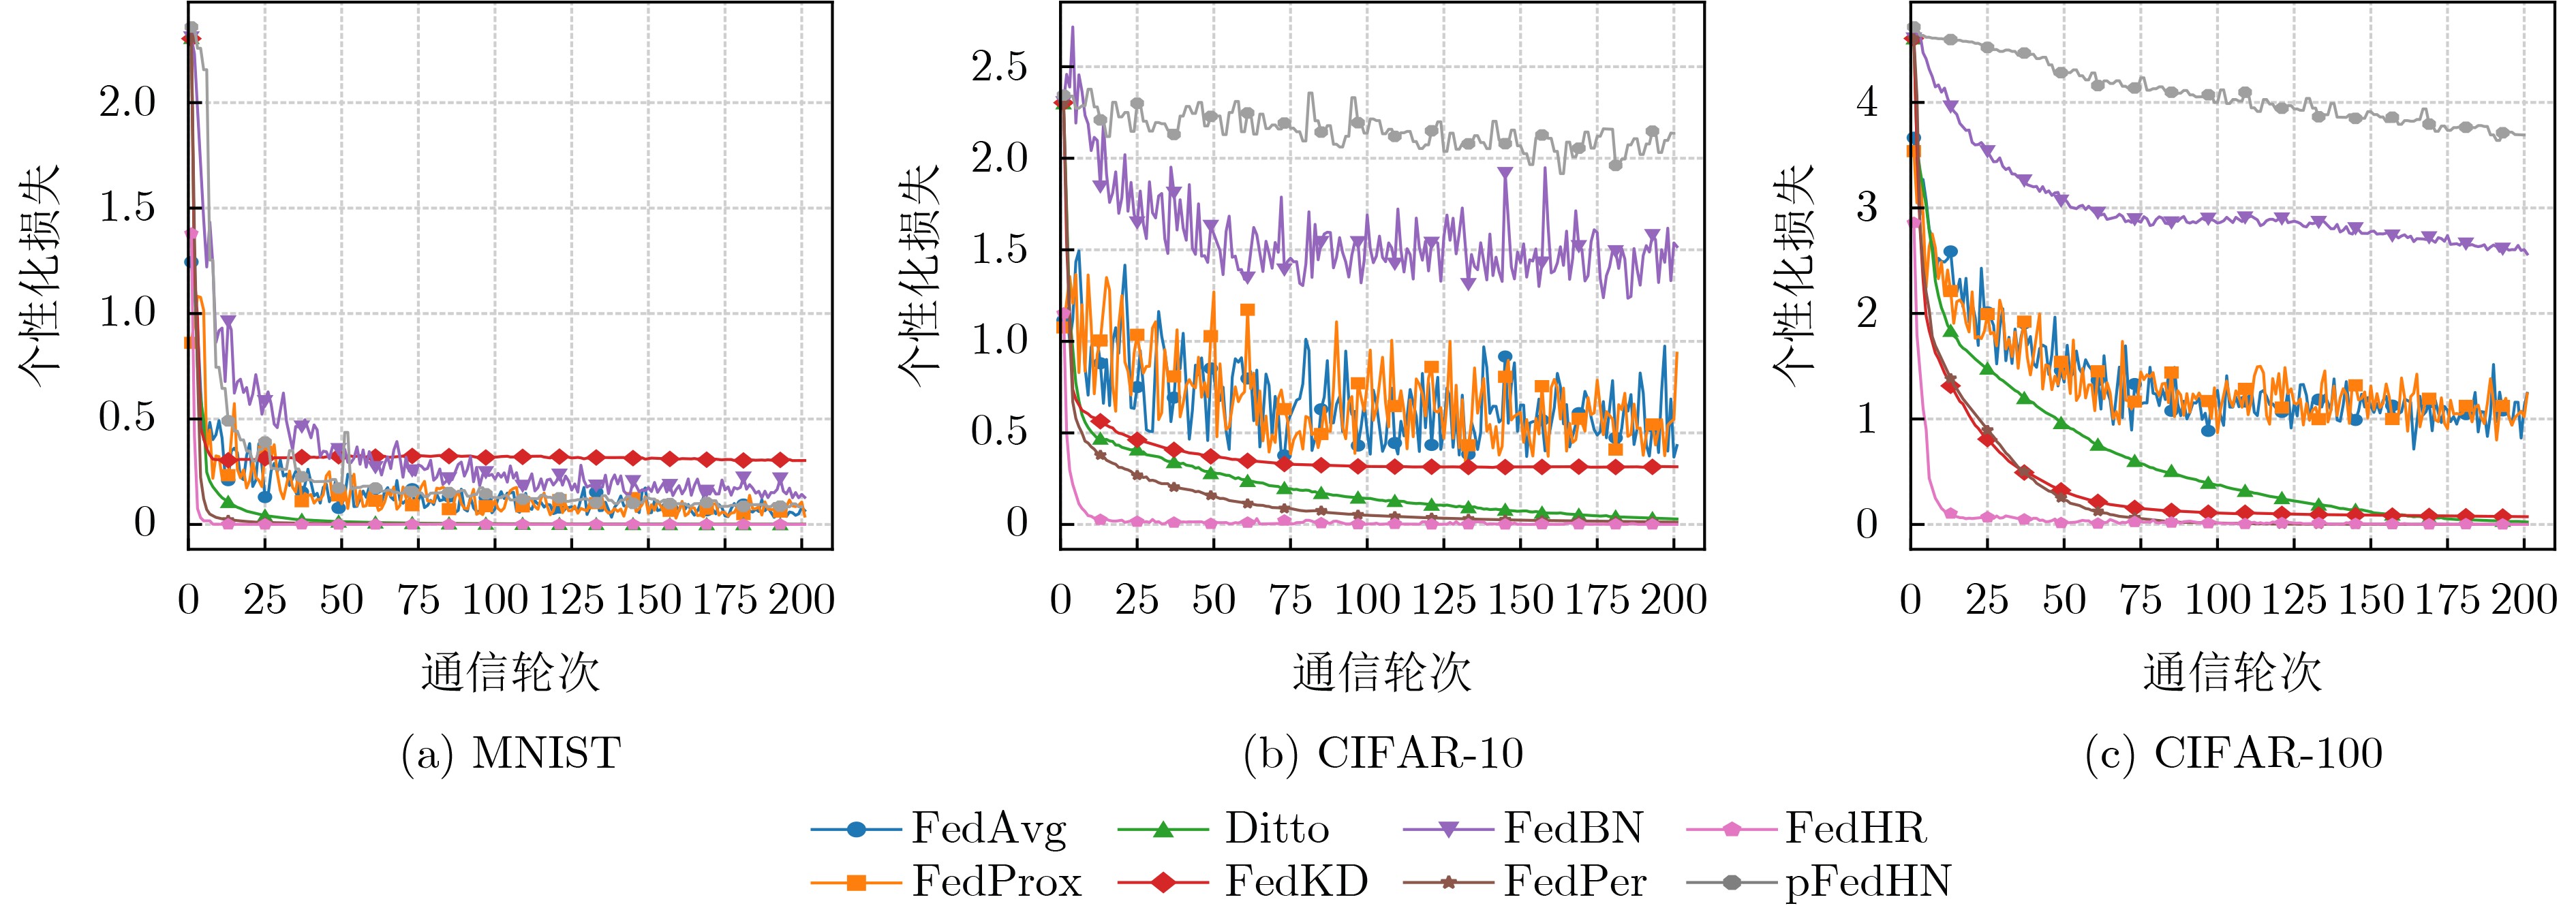
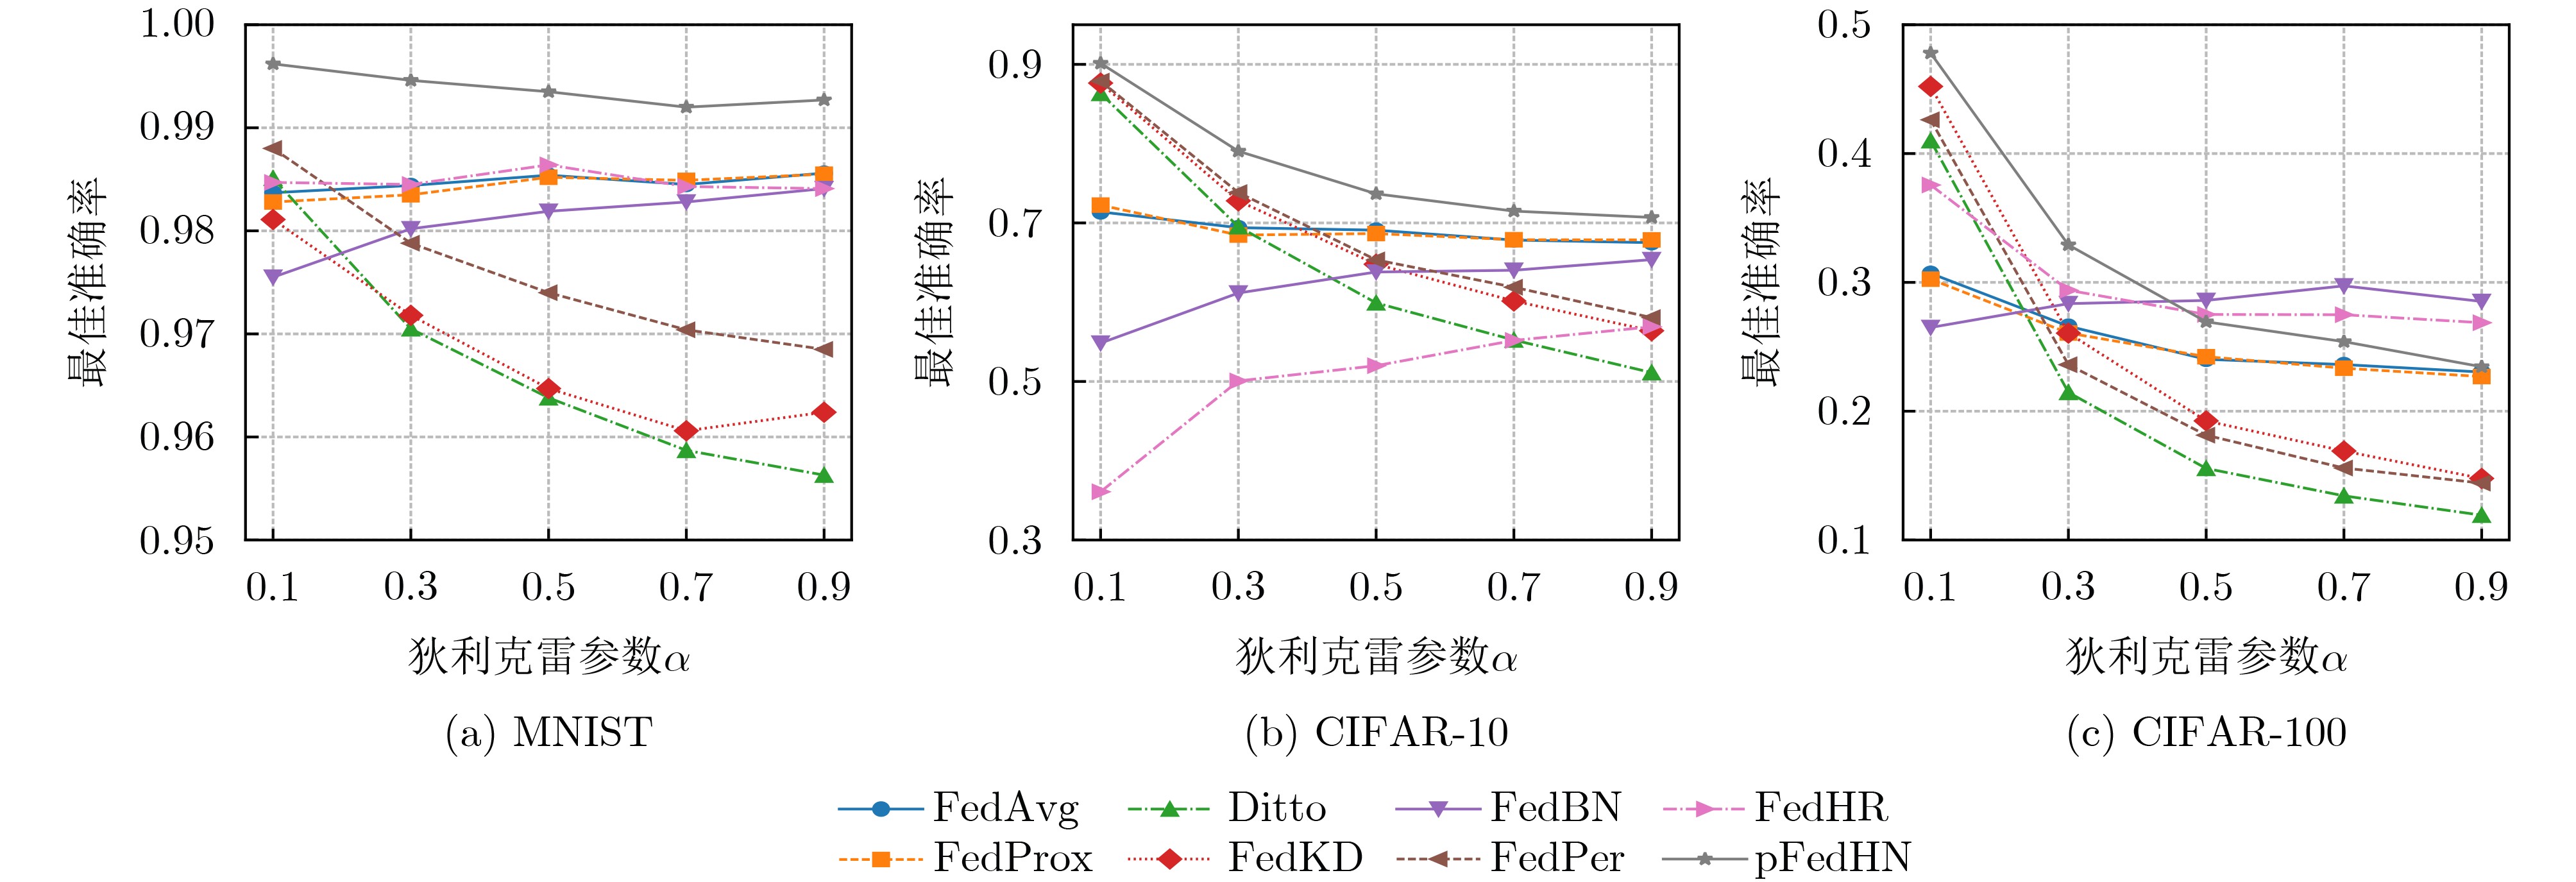
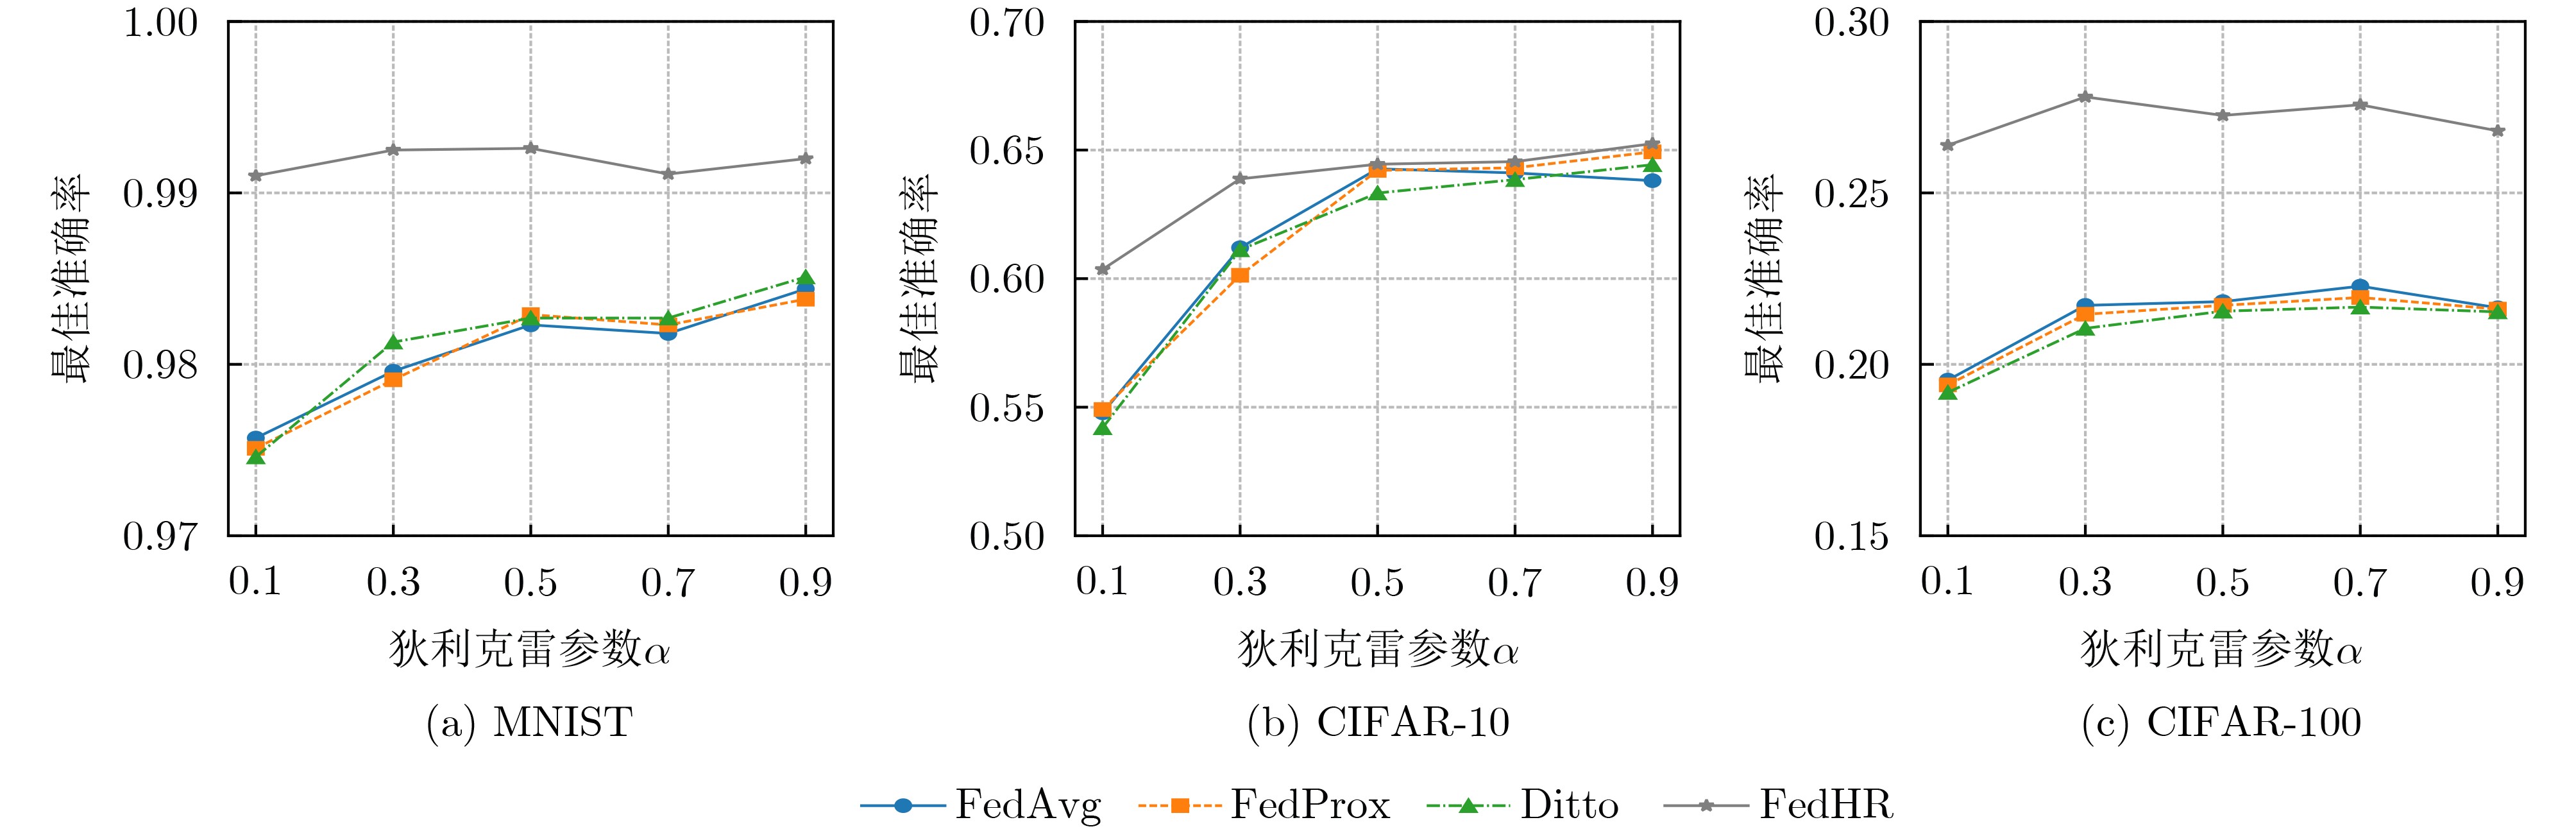
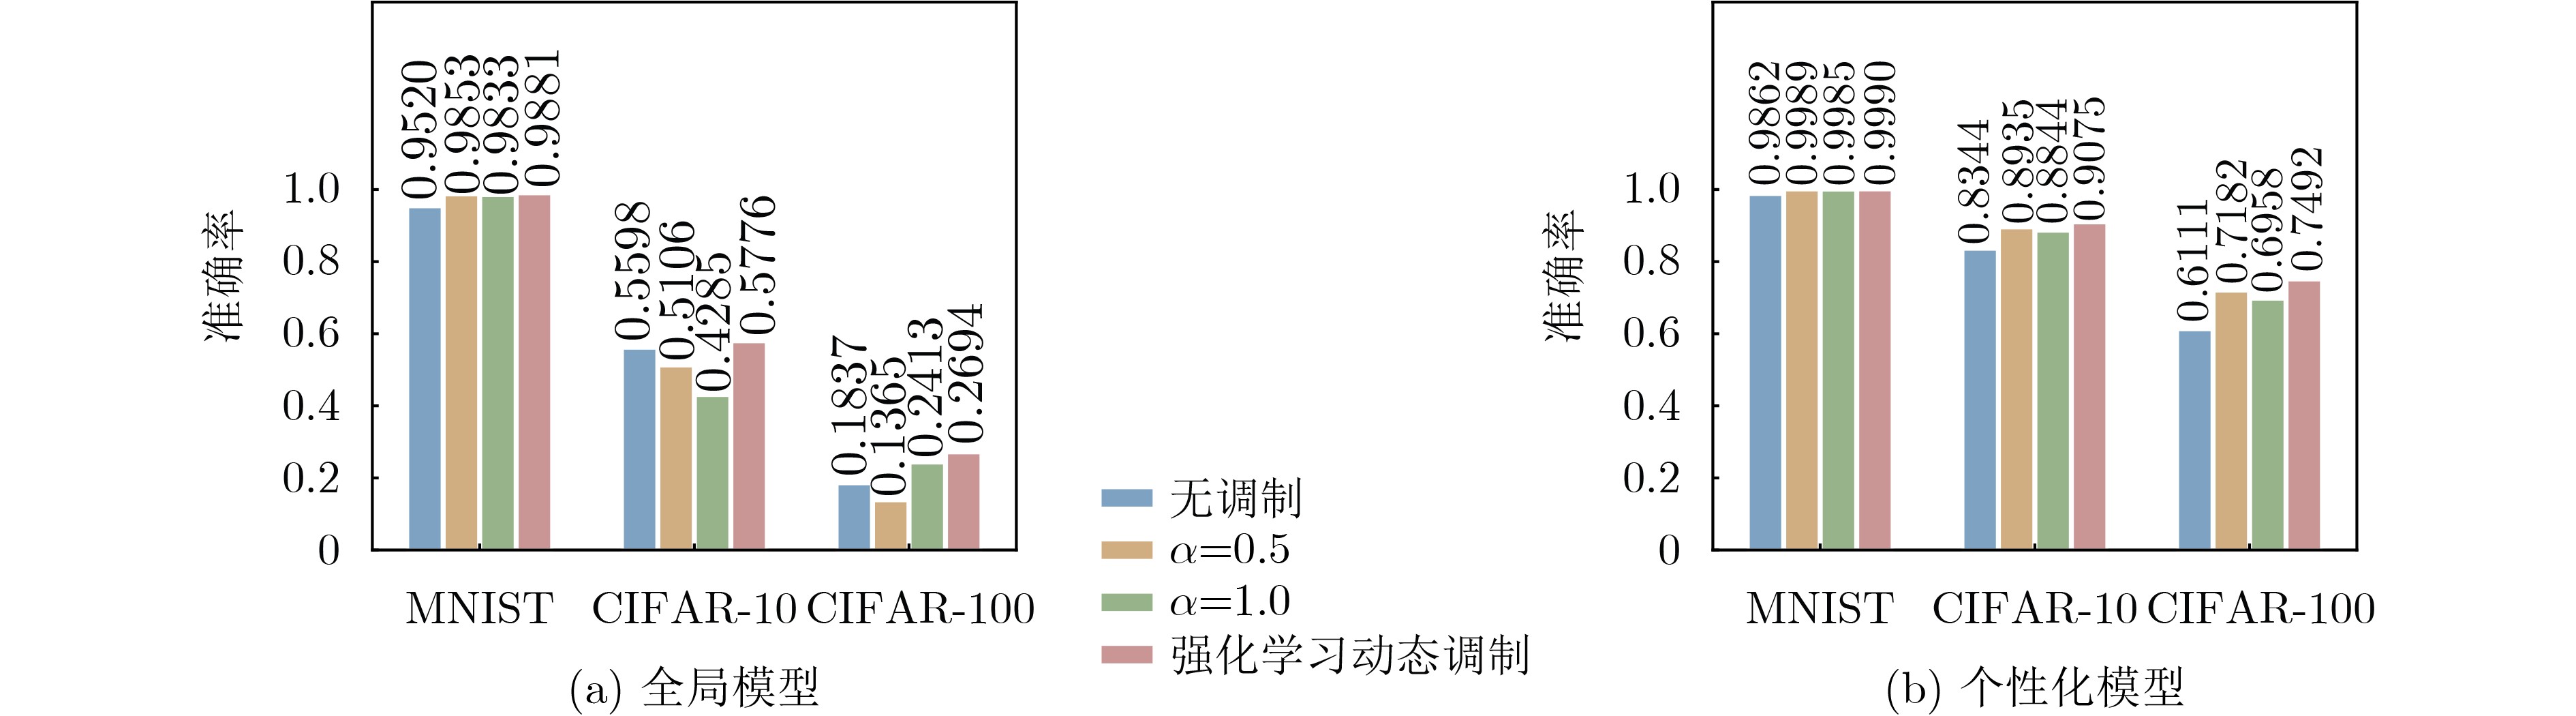
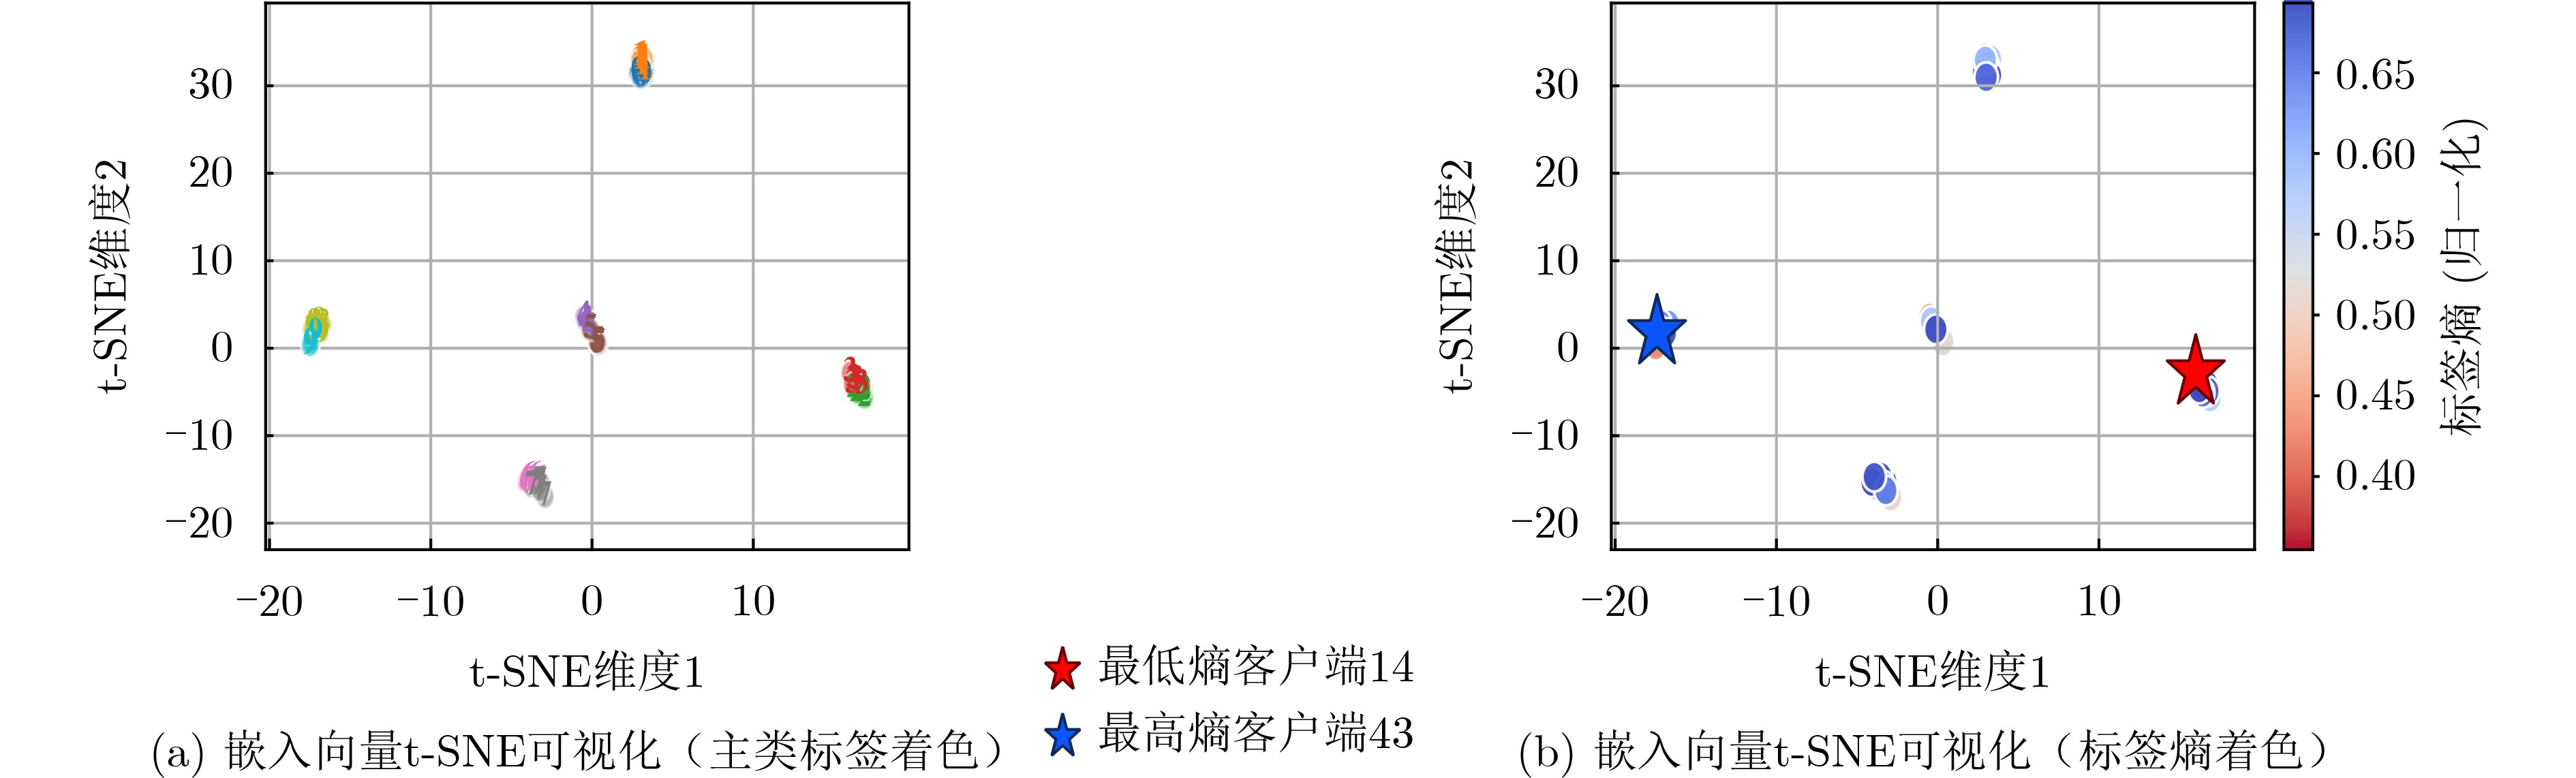
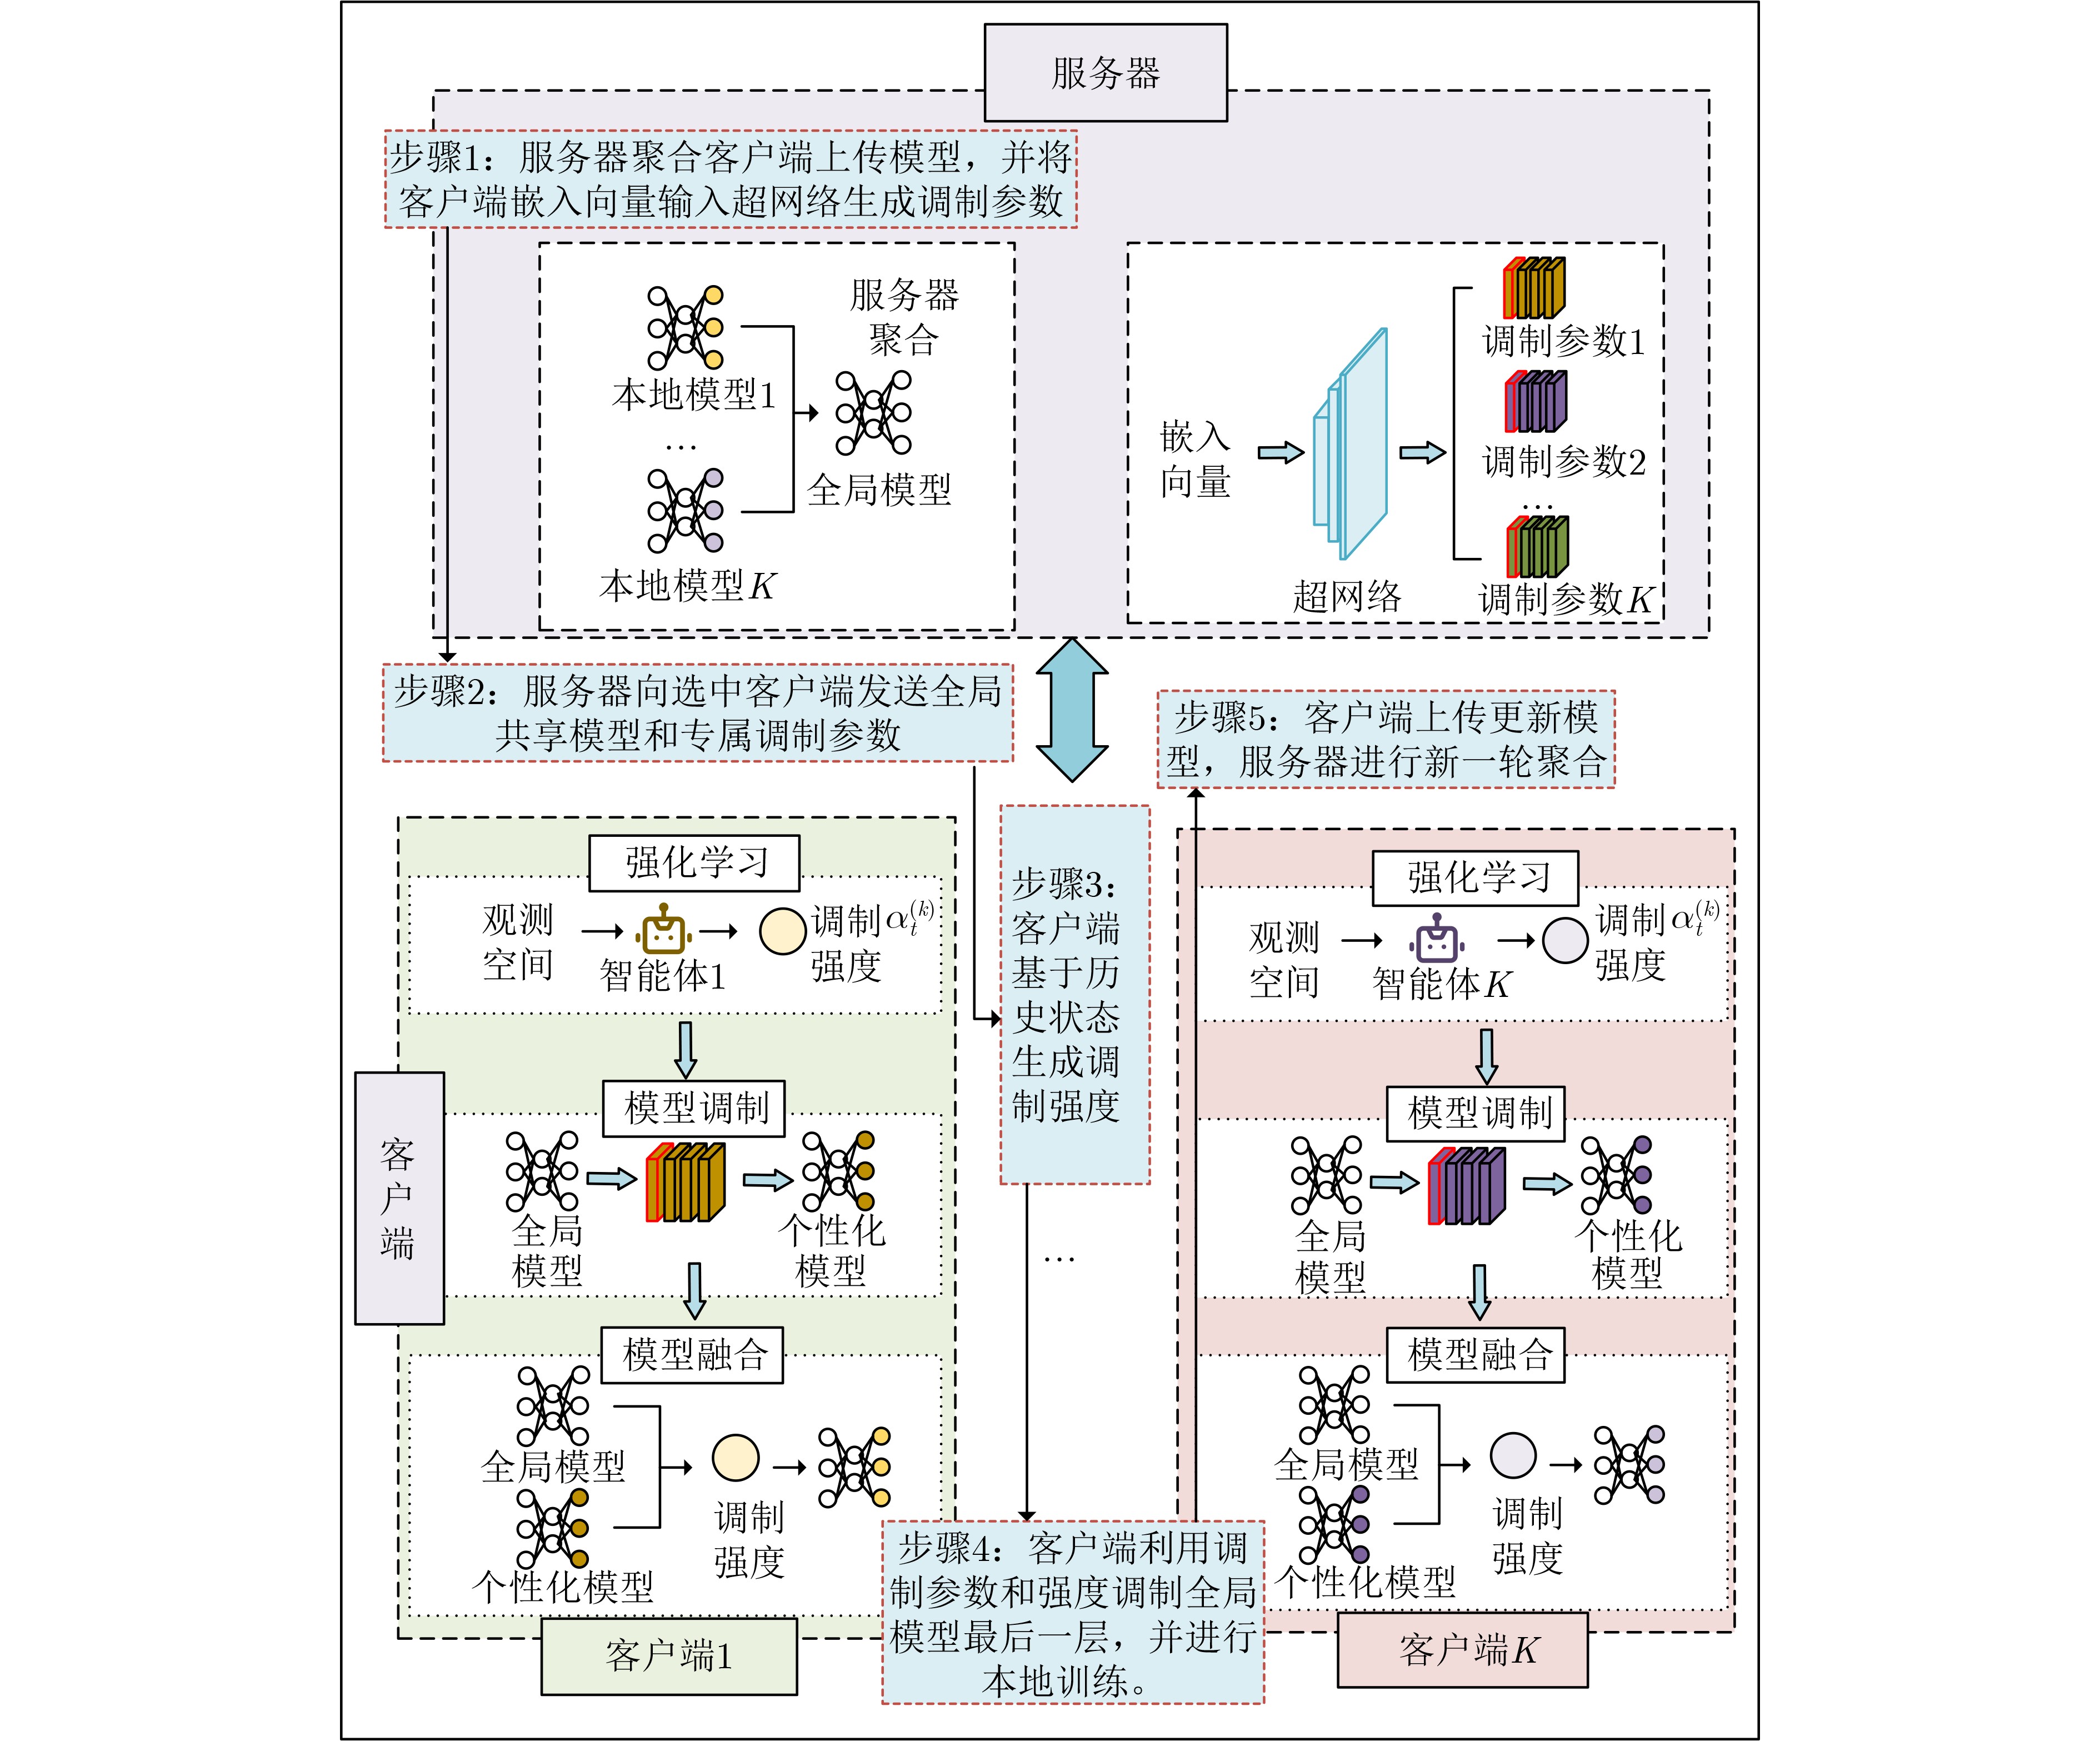
Objective Federated learning enables multiple clients to collaboratively train models without sharing raw data, but its performance often degrades when client data are Non-Independent and Identically Distributed (Non-IID). Data heterogeneity may cause client drift, weak global generalization, slow convergence, and increased communication cost. Personalized federated learning aims to preserve shared knowledge while adapting models to local distributions, yet existing methods often rely on fixed personalization strategies or generate large amounts of client-specific parameters. As a result, global knowledge sharing and local adaptation are difficult to balance, especially when client states change during training. To address these problems, a personalized federated learning method, FedHR, is proposed by combining hypernetwork-based parameter modulation with Deep Deterministic Policy Gradient (DDPG). The method is designed to achieve dynamic personalization with limited additional communication and to improve robustness under heterogeneous data. Methods FedHR retains the shared feature-extraction layers of the global model and personalizes only the final fully connected layer. A lightweight hypernetwork takes a client embedding as input and generates client-specific scaling and shifting parameters for the last layer. The client embedding is initialized from the local label distribution and is optimized together with the hypernetwork, allowing it to represent differences in client-specific parameter requirements. This partial modulation strategy preserves global feature representations while reducing the output dimension of the hypernetwork. To avoid using a fixed modulation strength, FedHR introduces a DDPG agent to determine how strongly the hypernetwork-generated parameters should affect each client. The state contains five quantities: the Kullback-Leibler divergence between local and global prediction distributions, the Euclidean and cosine distances between model parameters, local accuracy, and training progress. The action is a continuous modulation strength in the interval [0, 1]. A smaller value keeps the model closer to the global model, while a larger value strengthens local personalization. The reward combines local accuracy improvement with a penalty on excessive deviation from the global model. During each communication round, the server aggregates client models, generates client-specific modulation parameters, and sends them together with the global model ( Fig.1 , Algorithm 1). Each selected client then constructs its state, obtains the modulation strength from the DDPG agent, forms a personalized initialization, performs local training, and uploads the updated model for the next aggregation. Global Accuracy (GA), Personalized Accuracy (PA), and Total Communication Cost (TCC) are adopted as the main evaluation metrics so that predictive performance and communication efficiency can be examined together. A convergence analysis is further provided under standard smoothness, bounded stochastic-gradient, bounded modulation, and policy-approximation assumptions. The analysis shows that the modulation-induced initialization deviation and client drift remain bounded when the corresponding error terms are bounded.Results and Discussions Experiments are conducted on MNIST, CIFAR-10, CIFAR-100, UCI-HAR, and Shakespeare, covering image classification, sensor-based activity recognition, and sequence prediction. Both Dirichlet and pathological Non-IID partitions are considered for the image datasets, with 50 and 100 clients. FedAvg, FedProx, Ditto, FedKD, FedBN, FedPer, and pFedHN are used as baselines. The results show that FedHR achieves better global and personalized accuracy in most settings ( Table 1 ,Table 2 ), with clearer advantages under stronger heterogeneity and on more complex tasks. Across the reported image experiments, the global accuracy of FedHR is 0.73%–37.90% higher than that of FedAvg, and its personalized accuracy is 0.11%–11.24% higher than that of the best baseline in each setting. For example, on CIFAR-10 with 100 clients under the pathological partition, the personalized accuracy of FedHR reaches0.9094 , compared with0.8933 for FedPer and0.8739 for pFedHN (Table 2 ). The improvement mainly comes from the separation of shared representation learning and client-specific decision-layer adaptation. The shared backbone retains common knowledge across clients, whereas the hypernetwork adjusts the final decision boundary according to local distributions. DDPG further controls the modulation strength according to the current client state, reducing the risk of insufficient or excessive personalization. FedHR also performs well on UCI-HAR and Shakespeare (Table 3 ), indicating that the modulation mechanism is not restricted to image-classification tasks. On UCI-HAR, FedHR obtains a global accuracy of0.9257 and a personalized accuracy of0.9733 , and on Shakespeare the two values are0.4458 and0.4377 , respectively. The training curves show that FedHR reaches high personalized accuracy in fewer communication rounds and maintains a relatively stable loss trajectory (Fig.2 ,Fig.3 ). Although the additional client embedding and modulation parameters slightly increase the communication load of each round, the reduction in required communication rounds leads to a lower total communication cost. Specifically, the per-round parameter count of FedHR is only about 1.74% higher than that of FedAvg, whereas FedHR reaches the preset accuracy thresholds within 5, 4, and 6 rounds on MNIST, CIFAR-10, and CIFAR-100, respectively. Compared with representative baselines, the total communication cost is reduced by 27.0%–98.0% in the reported settings (Table 4 ). Experiments with different Dirichlet parameters further show that the advantage of FedHR becomes more evident when client distributions differ substantially, whereas the performance gap decreases as the data distributions approach IID (Fig.4 ,Fig.5 ). In the CIFAR-100 setting with a Dirichlet parameter larger than 0.5, the personalized accuracy of FedHR becomes lower than that of FedBN and pFedHN, whereas its global accuracy remains the highest among the compared methods (Fig.4 (c),Fig.5 (c)). This is consistent with the design of FedHR: client-specific modulation is more useful when local decision boundaries differ considerably, while weaker modulation is preferable when the global model already fits most clients. The ablation study shows that removing hypernetwork modulation leads to a clear performance decrease, and fixed-strength modulation is generally inferior to DDPG-based adaptive modulation (Fig.6 ). On CIFAR-100, fixed modulation strengths exhibit a trade-off between global and personalized accuracy, whereas DDPG-based dynamic modulation improves both, raising the global accuracy from0.1837 without modulation to0.2694 and the personalized accuracy from0.6111 to 0.7492. The learned client embeddings also exhibit distribution-related structures in the t-SNE visualization (Fig.7 ), supporting their use as conditions for generating personalized parameters.Conclusions FedHR combines hypernetwork modulation with reinforcement learning to dynamically balance global knowledge sharing and local adaptation in personalized federated learning. By modifying only the final fully connected layer, the method keeps the shared feature extractor intact and limits additional parameter overhead. DDPG adjusts the modulation strength according to the current client state instead of using a fixed personalization ratio. Experiments on five datasets show that FedHR improves global and personalized accuracy, reduces communication cost, and remains effective under different levels of data heterogeneity. The method is more suitable for medium-to-high heterogeneity scenarios, while weaker personalization is preferable when client distributions are close to IID. These results show that adaptive parameter modulation can improve personalized federated learning while maintaining communication efficiency. However, only the final fully connected layer is modulated in this study; extending the modulation to more layers and strengthening privacy protection for deployment in sensitive scenarios remain future work. -
1 FedHR
输入:全局通信轮次上限$ T $,客户端本地训练轮次$ E $,预初始化
全局模型$ \boldsymbol{\theta }_{0}^{\text{global}} $,超网络$ \mathcal{H}({\boldsymbol{\psi }}_{0}) $,强化学习智能体初始化参数。输出:最终全局模型参数$ \boldsymbol{\theta }_{T}^{\text{global}} $,各客户端个性化模型参数
$ \left\{\boldsymbol{\theta }_{T}^{(k)}\right\}_{k=1}^{K} $。(1) FOR$ t=1 $TO$ T $DO: (2) 根据目标模型最后一个线性层计算调制参数维度$ {\omega }_{\text{size}},{b}_{\text{size}} $ (3) 输入客户端嵌入$ {\boldsymbol{v}}_{k} $至超网络$ \mathcal{H},\varPhi_{t}^{\left(k\right)}=\mathcal{H}({\boldsymbol{v}}_{k}) $ (4) 随机采样客户端子集$ {S}_{t} $,向$ {S}_{t} $中每个客户端发送$ \boldsymbol{\theta }_{t}^{\text{global}} $和
$ \varPhi_{t}^{(k)} $(5) FOR每个$ k\in {S}_{t} $ DO: (6) 客户端$ k $接收$ \boldsymbol{\theta }_{t}^{\text{global}} $和$ \varPhi_{t}^{(k)} $ (7) 构建DDPG状态: $ \boldsymbol{s}_{t}^{(k)} = [{{d_{\text{KL}}^{t}}}^{(k)},{{d_{\text{eu}}^{t}}}^{(k)},{{d_{\cos }^{t}}}^{(k)}, $
$\text{acc}_{t}^{(k)},{r}_{t}] $(8) Actor网络输出动作:$ \alpha _{t}^{(k)}={\pi }_{\boldsymbol{\phi }}(\boldsymbol{s}_{t}^{(k)}) $ (9) 调制全局模型最后一层参数: $ \boldsymbol{W}\leftarrow \left(1+{{\boldsymbol{\gamma }_{\omega }^{t}}}^{(k)}\cdot \alpha _{t}^{(k)}\right)\odot \boldsymbol{W}+{{\boldsymbol{\beta }_{\omega }^{t}}}^{(k)}\cdot \alpha _{t}^{(k)} $ $ \boldsymbol{b}\leftarrow \left(1+{{\boldsymbol{\gamma }_{\text{b}}^{t}}}^{(k)}\cdot \alpha _{t}^{(k)}\right)\odot \boldsymbol{b}+{{\boldsymbol{\beta }_{\text{b}}^{t}}}^{(k)}\cdot \alpha _{t}^{(k)} $ (10) 客户端本地模型训练得到客户端个性化模型参数$ \boldsymbol{\theta }_{t}^{(k)} $ (11) 根据式(13)计算奖励$ R_{t}^{(k)} $,构建下一状态$ \boldsymbol{s}_{t+1}^{(k)} $,并更新
Critic与Actor网络(12) 服务器聚合模型并更新得到$ \boldsymbol{\theta }_{t+1}^{\text{global}} $ (13) RETURN最终全局模型参数$ \boldsymbol{\theta }_{T}^{\text{global}} $,各客户端个性化模型
参数$ \left\{\boldsymbol{\theta }_{T}^{(k)}\right\}_{k=1}^{K} $ 下载: 导出CSV
表 1 FedHR算法和对比算法的全局模型最佳准确率
对比
算法MNIST CIFAR-10 CIFAR-100 50个客户端 100个客户端 50个客户端 100个客户端 50个客户端 100个客户端 狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分FedAvg 0.9850 0.9557 0.9817 0.9597 0.6411 0.5540 0.6038 0.5558 0.2531 0.2500 0.1863 0.2361 FedProx 0.9852 0.9519 0.9824 0.9565 0.6407 0.5582 0.6049 0.5524 0.2547 0.2486 0.1775 0.2527 Ditto 0.9848 0.9551 0.9834 0.9560 0.6425 0.5564 0.6142 0.5573 0.2503 0.2534 0.1903 0.2452 FedHR 0.9922 0.9901 0.9930 0.9902 0.6482 0.6237 0.6334 0.6095 0.2725 0.2594 0.2569 0.2508
下载: 导出CSV
表 2 FedHR算法和对比算法的个性化模型最佳准确率
对比
算法MNIST CIFAR-10 CIFAR-100 50个客户端 100个客户端 50个客户端 100个客户端 50个客户端 100个客户端 狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分狄利
克雷病态
划分FedAvg 0.9908 0.9872 0.9885 0.9879 0.7724 0.8257 0.7260 0.8175 0.3199 0.5572 0.2445 0.5579 FedProx 0.9914 0.9873 0.9885 0.9889 0.7764 0.8367 0.7290 0.8149 0.3191 0.5450 0.2493 0.5201 Ditto 0.9751 0.9953 0.9639 0.9952 0.7357 0.8754 0.7026 0.8546 0.2571 0.5707 0.2216 0.5266 FedKD 0.9882 0.9978 0.9784 0.9969 0.7715 0.8879 0.7316 0.8659 0.3168 0.5969 0.2664 0.5645 FedBN 0.9846 0.9531 0.9824 0.9604 0.6359 0.5568 0.6012 0.5502 0.2987 0.2532 0.2759 0.2438 FedPer 0.9876 0.9977 0.9795 0.9978 0.7810 0.8999 0.7344 0.8933 0.2857 0.5948 0.2315 0.5613 pFedHN 0.9836 0.9952 0.9865 0.9941 0.4973 0.8791 0.5007 0.8739 0.2285 0.5815 0.2226 0.4973 FedHR 0.9951 0.9990 0.9951 0.9989 0.8056 0.9178 0.7851 0.9094 0.3309 0.6070 0.3069 0.5834
下载: 导出CSV
表 3 跨任务模型最佳准确率对比
对比
算法全局模型 个性化模型 HAR Shakespeare HAR Shakespeare FedAvg 0.8618 0.2746 0.9300 0.2680 FedProx 0.8673 0.2670 0.9408 0.2703 Ditto 0.8704 0.2737 0.9257 0.1903 FedKD - - 0.9543 0.1739 FedBN - - 0.8611 0.2684 FedPer - - 0.9632 0.2068 pFedHN - - 0.9447 0.2351 FedHR 0.9257 0.4458 0.9733 0.4377
下载: 导出CSV
表 4 通信成本对比
对比算法 单轮参数量(个) MNIST CIFAR-10 CIFAR-100 达到阈值轮次 总通信成本(MB) 达到阈值轮次 总通信成本(MB) 达到阈值轮次 总通信成本(MB) FedAvg 35,503,586 138 18,690.38 200 27,047.06 72 9,736.94 FedProx 35,503,586 156 21,124.41 - - 191 25,876.58 Ditto 35,503,586 27 3,650.83 47 6,359.40 106 14,320.70 FedKD 33,749,716 13 1,669.73 18 2,311.04 25 3,209.72 FedBN 35,503,586 - - - - - - FedPer 35,190,656 7 939.58 12 1,609.83 222 29,828.13 pFedHN 35,503,586 - - - - - - FedHR 36,121,026 5 686.03 4 548.82 6 823.24
下载: 导出CSV
-
[1] 刘淼, 夏雨虹, 赵海涛, 等. 面向6G工业物联网的联邦学习: 从需求、愿景到挑战、机遇[J]. 电子与信息学报, 2024, 46(12): 4335–4353. doi: 10.11999/JEIT240574.LIU Miao, XIA Yuhong, ZHAO Haitao, et al. Federated learning technologies for 6G industrial internet of things: From requirements, vision to challenges, opportunities[J]. Journal of Electronics & Information Technology, 2024, 46(12): 4335–4353. doi: 10.11999/JEIT240574. [2] 杨志刚, 王卓彤, 吴大鹏, 等. 物联网中带有隐私保护的鲁棒联邦学习研究[J]. 电子与信息学报, 2023, 45(12): 4235–4244. doi: 10.11999/JEIT221193.YANG Zhigang, WANG Zhuotong, WU Dapeng, et al. Research on data heterogeneous robust federated learning with privacy protection in internet of things[J]. Journal of Electronics & Information Technology, 2023, 45(12): 4235–4244. doi: 10.11999/JEIT221193. [3] 温泽诚, 陈磊. 联邦学习综述[J]. 计算机科学与应用, 2025, 15(3): 102–107. doi: 10.12677/csa.2025.153062.WEN Zecheng and CHEN Lei. A review of federated learning[J]. Computer Science and Application, 2025, 15(3): 102–107. doi: 10.12677/csa.2025.153062. [4] TEO Z L, JIN Liyuan, LIIU Nan, et al. Federated machine learning in healthcare: A systematic review on clinical applications and technical architecture[J]. Cell Reports Medicine, 2024, 5(2): 101419. doi: 10.1016/j.xcrm.2024.101419. [5] 温木奇, 温武少. 边缘计算的安全挑战与解决方法综述[J]. 计算机系统应用, 2024, 33(11): 38–47. doi: 10.15888/j.cnki.csa.009702.WEN Muqi and WEN Wushao. Review on security challenges and solutions to edge computing[J]. Computer Systems and Applications, 2024, 33(11): 38–47. doi: 10.15888/j.cnki.csa.009702. [6] 杨睿哲, 谢欣儒, 滕颖蕾, 等. 工业物联网中基于信息熵的联邦增量学习算法与优化[J]. 电子与信息学报, 2024, 46(8): 3146–3154. doi: 10.11999/JEIT231240.YANG Ruizhe, XIE Xinru, TENG Yinglei, et al. Entropy-based federated incremental learning and optimization in industrial internet of things[J]. Journal of Electronics & Information Technology, 2024, 46(8): 3146–3154. doi: 10.11999/JEIT231240. [7] MCMAHAN B, MOORE E, RAMAGE D, et al. Communication-efficient learning of deep networks from decentralized data[C]. Proceedings of the 20th International Conference on Artificial Intelligence and Statistics, Fort Lauderdale, USA, 2017: 1273–1282. [8] 何帆, 王勇, 杨静, 等. 面向边缘计算场景的个性化联邦学习综述[J]. 通信学报, 2025, 46(7): 206–225. doi: 10.11959/j.issn.1000-436x.2025131.HE Fan, WANG Yong, YANG Jing, et al. Survey of personalized federated learning for edge computing scenarios[J]. Journal on Communications, 2025, 46(7): 206–225. doi: 10.11959/j.issn.1000-436x.2025131. [9] FALLAH A, MOKHTARI A, and OZDAGLAR A E. Personalized federated learning with theoretical guarantees: A model-agnostic meta-learning approach[C]. Proceedings of the 34th International Conference on Neural Information Processing Systems, Vancouver, Canada, 2020: 300. [10] LI Tian, HU Shengyuan, BEIRAMI A, et al. Ditto: Fair and robust federated learning through personalization[C]. The 38th International Conference on Machine Learning (ICML), 2021: 6357–6368. (查阅网上资料, 未找到对应的出版地信息, 请确认补充). [11] LI Xiaoxiao, JIANG Meirui, ZHANG Xiaofei, et al. FedBN: Federated learning on non-IID features via local batch normalization[C]. The 9th International Conference on Learning Representations (ICLR), Virtual Event, Austria, 2021. (查阅网上资料, 出版地信息不确定, 请确认). [12] COLLINS L, HASSANI H, MOKHTARI A, et al. Exploiting shared representations for personalized federated learning[C]. The 38th International Conference on Machine Learning (ICML), 2021: 2089–2099. (查阅网上资料, 未找到对应的出版地信息, 请确认补充). [13] LI Qinbin, HE Bingsheng, and SONG D. Model-contrastive federated learning[C]. 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, USA, 2021: 10708–10717. doi: 10.1109/CVPR46437.2021.01057. [14] LI Daliang and WANG Junpu. FedMD: Heterogenous federated learning via model distillation[C]. Proceedings of the NeurIPS 2019 Workshop on Federated Learning for Data Privacy and Confidentiality, Vancouver, Canada, 2019. (查阅网上资料, 出版地信息不确定, 请确认). [15] VENKATESWARAN P, ISAHAGIAN V, MUTHUSAMY V, et al. FedGen: Generalizable federated learning for sequential data[C]. 2023 IEEE 16th International Conference on Cloud Computing (CLOUD), Chicago, USA, 2023: 308–318. [16] HA D, DAI A M, and LE Q V. HyperNetworks[C]. The 5th International Conference on Learning Representations (ICLR), Toulon, France, 2017. [17] SHAMSIAN A, NAVON A, FETAYA E, et al. Personalized federated learning using hypernetworks[C]. The 38th International Conference on Machine Learning (ICML), 2021: 9489–9502. (查阅网上资料, 未找到对应的出版地信息, 请确认补充). [18] MA Xiaosong, ZHANG Jie, GUO Song, et al. Layer-wised model aggregation for personalized federated learning[C]. 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, USA, 2022: 10082–10091. doi: 10.1109/CVPR52688.2022.00985. [19] LI Hongxia, CAI Zhongyi, WANG Jingya, et al. FedTP: Federated learning by transformer personalization[J]. IEEE Transactions on Neural Networks and Learning Systems, 2024, 35(10): 13426–13440. doi: 10.1109/TNNLS.2023.3269062. [20] 李阳, 姜毅, 陈帅, 等. 多层超网络聚合的个性化联邦学习算法[J]. 计算机工程, 2026, 52(9): 133–142. doi: 10.19678/j.issn.1000-3428.0070679.LI Yang, JIANG Yi, CHEN Shuai, et al. Personalized federated learning algorithm based on multi-layer hypernetwork aggregation[J]. Computer Engineering, 2026, 52(9): 133–142. doi: 10.19678/j.issn.1000-3428.0070679. [21] YANG Ziyuan, XIA Wenjun, LU Zexin, et al. Hypernetwork-based physics-driven personalized federated learning for CT imaging[J]. IEEE Transactions on Neural Networks and Learning Systems, 2025, 36(2): 3136–3150. doi: 10.1109/TNNLS.2023.3338867. [22] CHEN Leiming, ZHANG Weishan, DONG Cihao, et al. FedDRL: Trustworthy federated learning model fusion method based on staged reinforcement learning[J]. Computing and Informatics, 2024, 43(1): 1–37. doi: 10.31577/cai_2024_1_1. [23] BANG J, WOO S, and LEE J. DRL-empowered joint batch size and weighted aggregation adjustment mechanism for federated learning on non-IID data[J]. ICT Express, 2024, 10(4): 863–870. doi: 10.1016/j.icte.2024.04.011. [24] LILLICRAP T P, HUNT J J, PRITZEL A, et al. Continuous control with deep reinforcement learning[C]. Proceedings of the 4th International Conference on Learning Representations (ICLR), San Juan, Puerto Rico, 2016. [25] BOTTOU L, CURTIS F E, and NOCEDAL J. Optimization methods for large-scale machine learning[J]. SIAM Review, 2018, 60(2): 223–311. doi: 10.1137/16M1080173. [26] VIRMAUX A and SCAMAN K. Lipschitz regularity of deep neural networks: Analysis and efficient estimation[C]. Proceedings of the 32nd International Conference on Neural Information Processing Systems, Montréal, Canada, 2018: 3839–3848. [27] FUJIMOTO S, VAN HOOF H, and MEGER D. Addressing function approximation error in actor-critic methods[C]. The 35th International Conference on Machine Learning (ICML), Stockholm, Sweden, 2018: 1582–1591. [28] LECUN Y, BOTTOU L, BENGIO Y, et al. Gradient-based learning applied to document recognition[J]. Proceedings of the IEEE, 1998, 86(11): 2278–2324. doi: 10.1109/5.726791. [29] KRIZHEVSKY A. Learning multiple layers of features from tiny images[R]. Toronto, Canada: University of Toronto, 2009. [30] ANGUITA D, GHIO A, ONETO L, et al. A public domain dataset for human activity recognition using smartphones[C]. The 21st European Symposium on Artificial Neural Networks, Computational Intelligence and Machine Learning (ESANN), Bruges, Belgium, 2013: 437–442. [31] CALDAS S, DUDDU S M K, WU P, et al. LEAF: A benchmark for federated settings[C]. Workshop on Federated Learning for Data Privacy and Confidentiality at NeurIPS 2019, Vancouver, Canada, 2019. (查阅网上资料, 未找到本条文献信息, 请确认). [32] LI Tian, SAHU A K, ZAHEER M, et al. Federated optimization in heterogeneous networks[C]. The 3rd Conference on Machine Learning and Systems (MLSys), Austin, USA, 2020: 429–450. (查阅网上资料, 页码信息不确定, 请确认). [33] WU Chuhan, WU Fangzhao, LYU Lingjuan, et al. Communication-efficient federated learning via knowledge distillation[J]. Nature Communications, 2022, 13: 2032. doi: 10.1038/s41467-022-29763-x. [34] ARIVAZHAGAN M G, AGGARWAL V, SINGH A K, et al. Federated learning with personalization layers[EB/OL]. https://arxiv.org/abs/1912.00818, 2019. -

 下载:

图(7) / 表(5)
计量
- 文章访问数: 17
- HTML全文浏览量: 3
- PDF下载量: 0
- 被引次数: 0
