Advanced Search
Turn off MathJax
Article Contents
ZHAO Ya, JIANG Liuyang, JIA Di, YAO Wenda. Cross-Frequency Collaborative Low-Light Face Enhancement Guided by Structural Priors[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260843
Citation: ZHAO Ya, JIANG Liuyang, JIA Di, YAO Wenda. Cross-Frequency Collaborative Low-Light Face Enhancement Guided by Structural Priors[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260843

Cross-Frequency Collaborative Low-Light Face Enhancement Guided by Structural Priors

doi: 10.11999/JEIT260843 cstr: 32379.14.JEIT260843
Funds:  National Natural Science Foundation of China (Grant No. 62471124); Natural Science Foundation of Heilongjiang Province (Grant No. LH2022F006); Key Project of Heilongjiang Provincial Education Science Planning (Grant No. GJB1421114)
  • Accepted Date: 2026-09-17
  • Rev Recd Date: 2026-09-17
  • Available Online: 2026-09-27
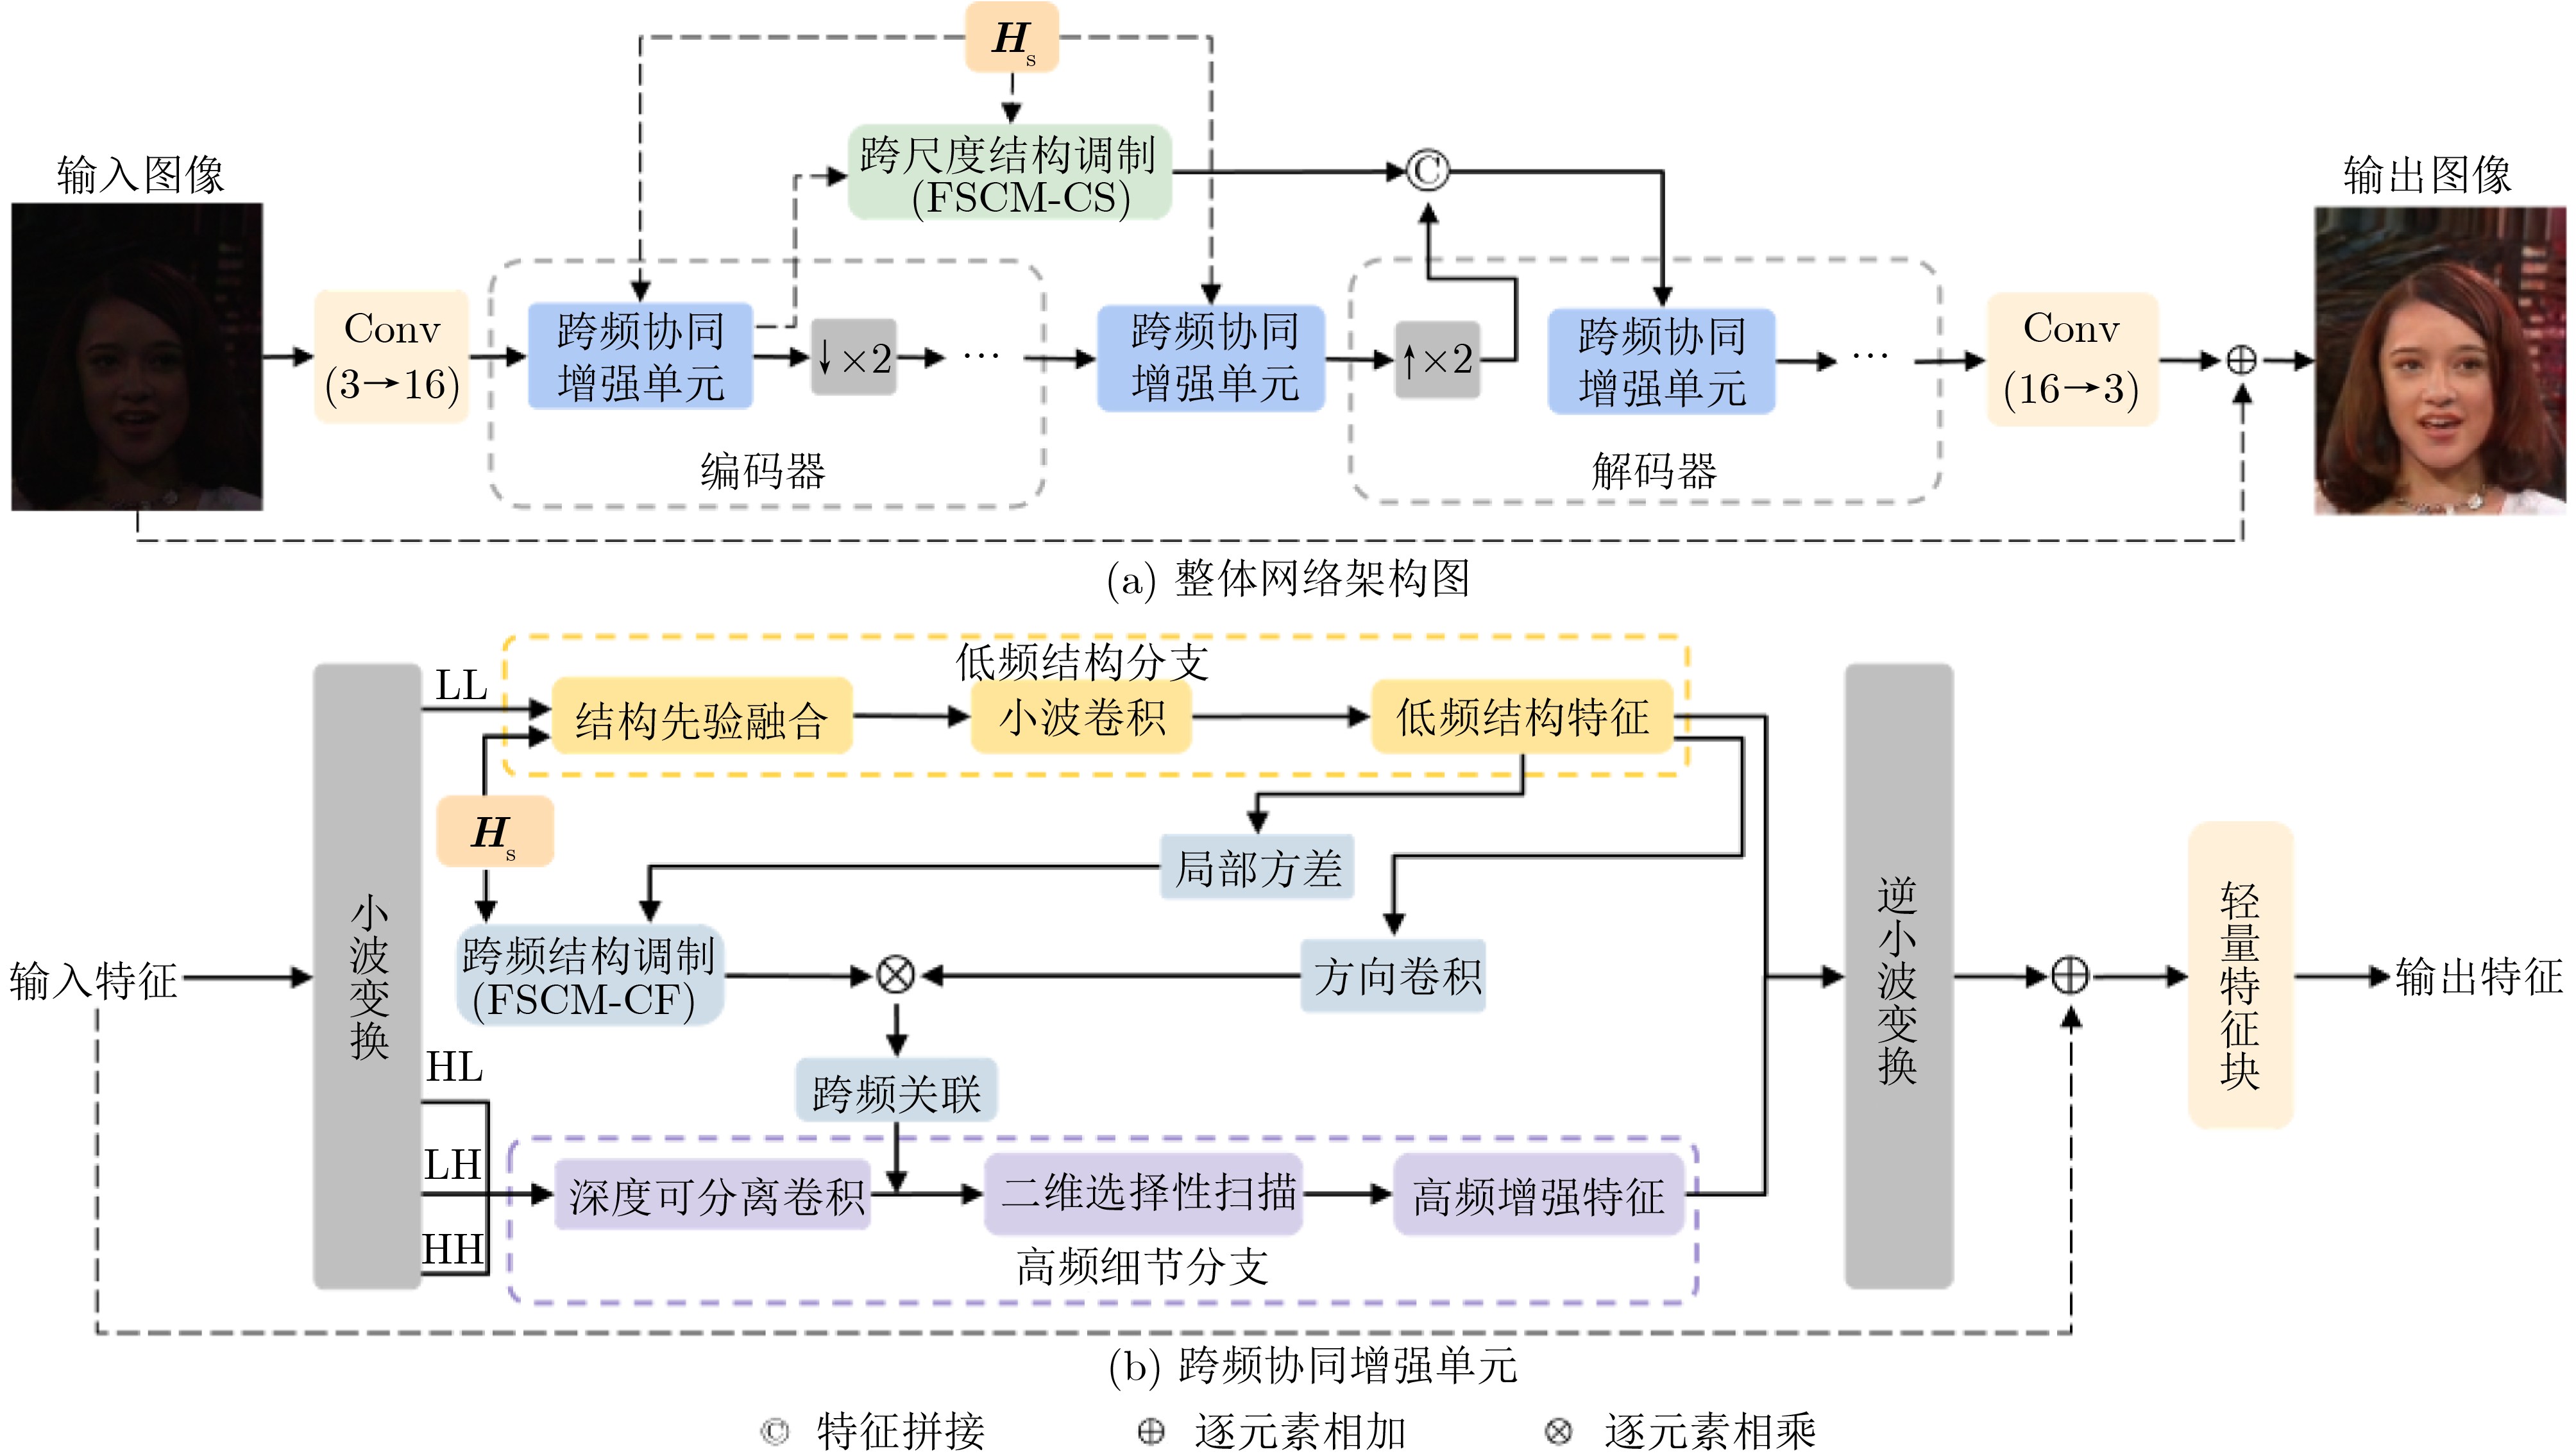
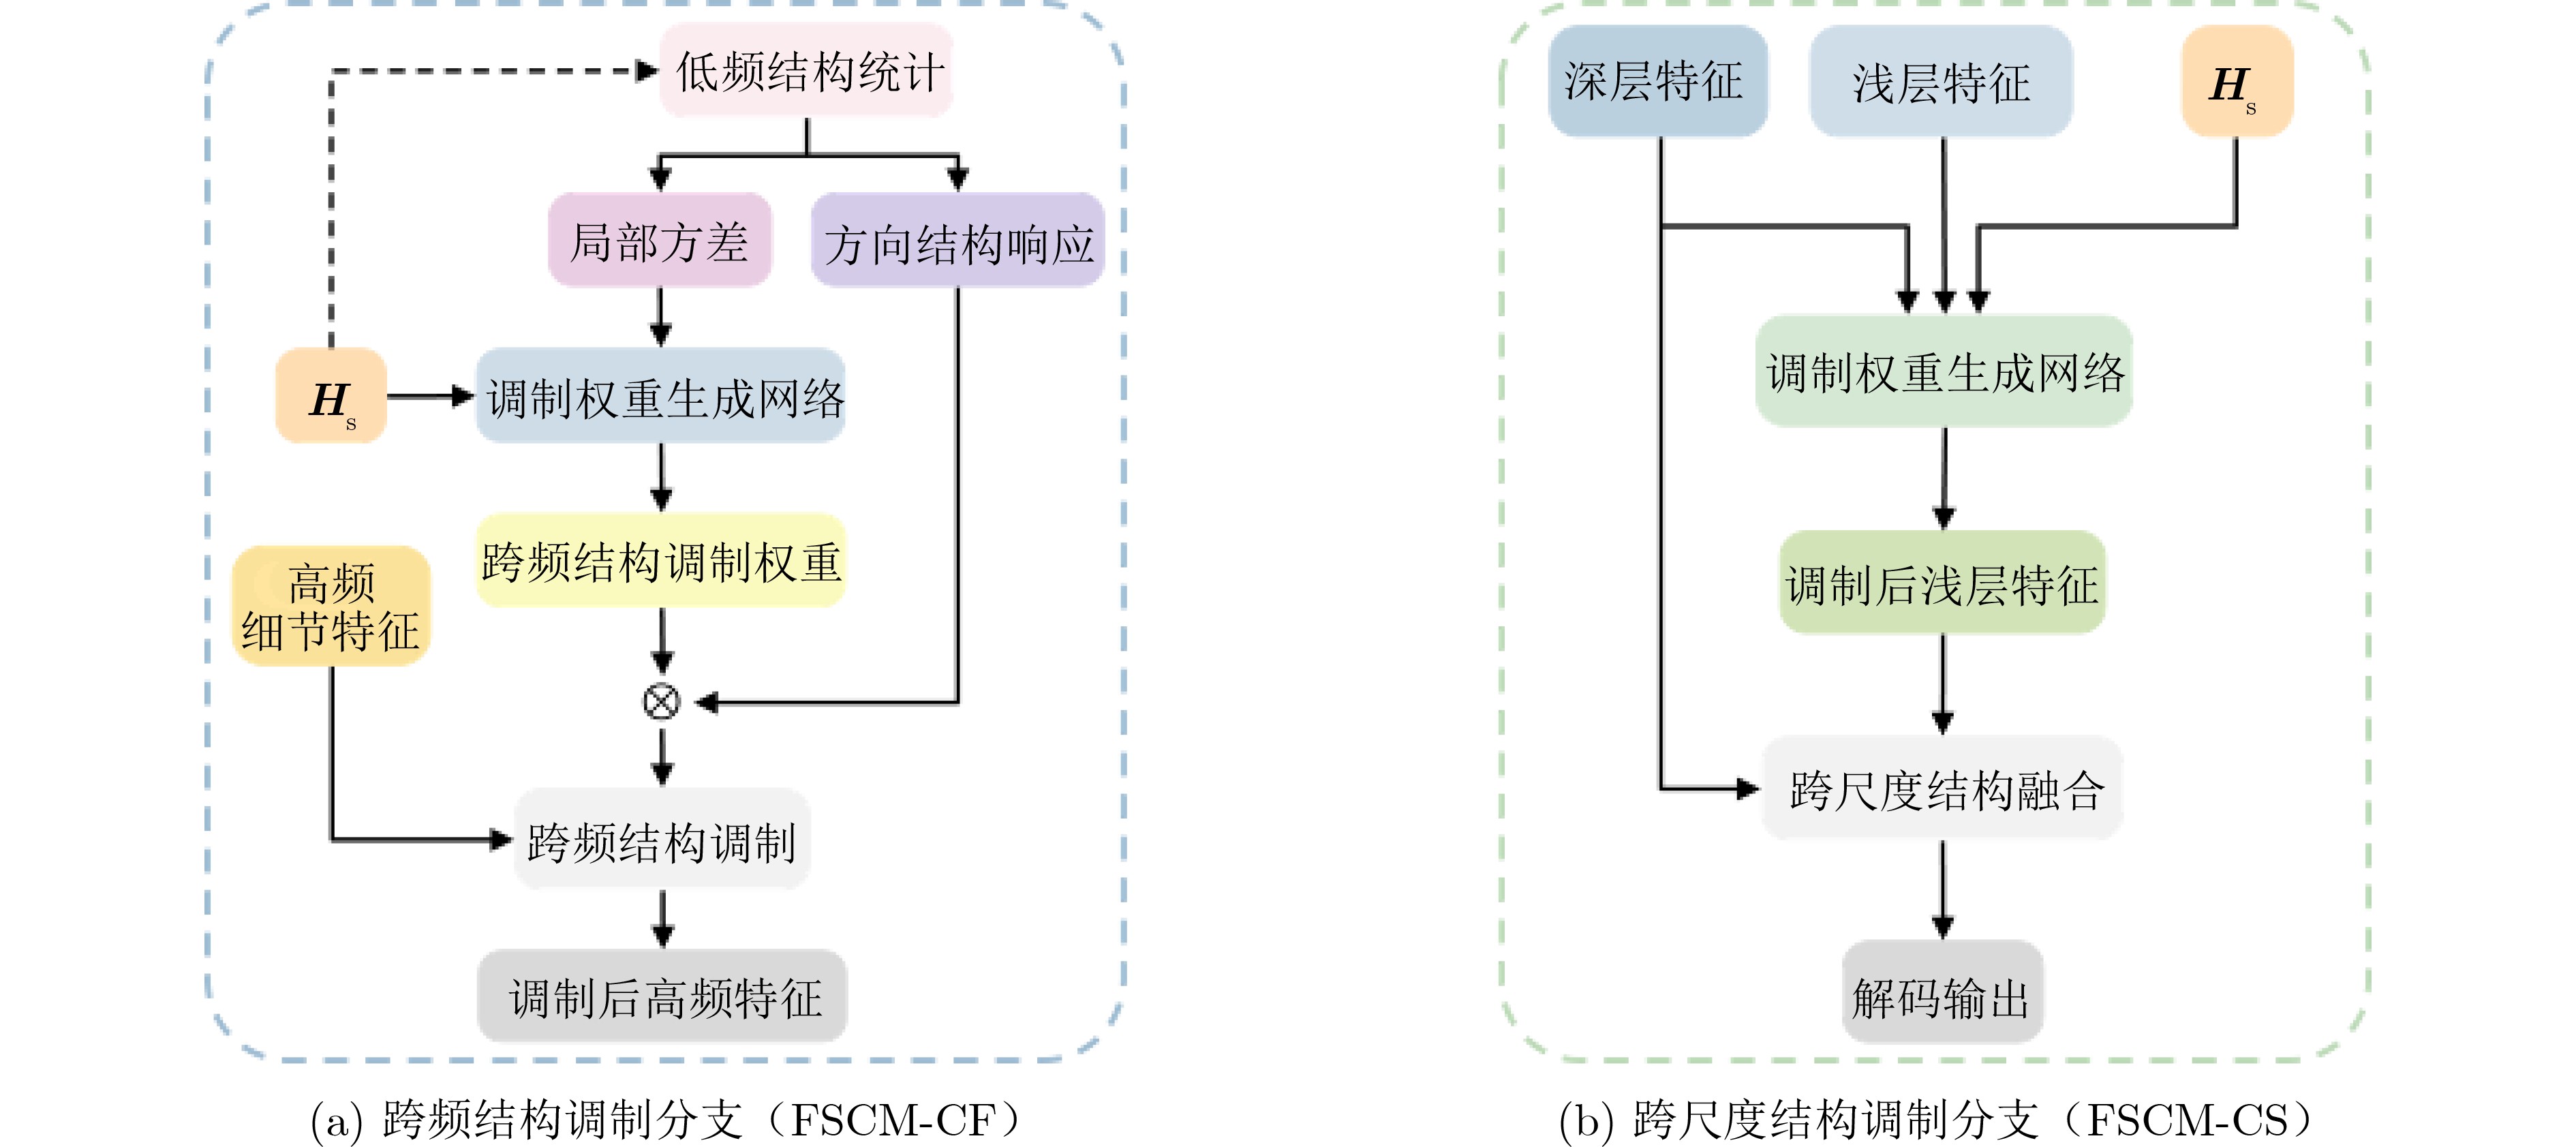
  •   Objective  Low-light face images commonly suffer from insufficient illumination, reduced contrast, amplified noise, and loss of local details. These degradations reduce visual quality and destabilize identity recognition, fatigue analysis, and face behavior understanding. Structural and discriminative information around the eyes and mouth is especially vulnerable to edge blurring, texture loss, and local structural shifts. Existing low-light image enhancement methods mainly focus on illumination recovery or general image reconstruction, while preservation of key face structures and identity-related representations remains limited. From a frequency-domain perspective, low-light degradation weakens low-frequency structural responses while disturbing high-frequency edges and textures, and directly enhancing high-frequency components without structural guidance may amplify noise or introduce false textures. Therefore, low-frequency face structures should guide spatially corresponding high-frequency detail restoration while maintaining structural stability during cross-frequency interaction and multi-scale reconstruction. To address these problems, a structural-prior-guided cross-frequency collaborative method is proposed for low-light face image enhancement.  Methods  An encoder-decoder enhancement network is constructed with structural-prior-guided cross-frequency association (CFA), high-frequency modeling (HFM), and face structural consistency modulation (FSCM) (Fig. 1). In CFA, input features are decomposed into low-frequency and directional high-frequency subbands using a discrete wavelet transform. Key-region heatmaps generated from facial landmarks are combined with directional structural responses and local statistical information to construct a spatial structural prior, which guides the restoration of spatially corresponding high-frequency details according to key-region locations, structural directions, and local significance, thereby reducing excessive enhancement of weak-structure or noise-dominated regions. HFM combines depthwise separable convolution with two-dimensional selective scanning. Local convolution is used to extract edge and texture details, whereas multi-directional selective scanning models long-range spatial dependencies. FSCM further regulates structurally relevant features during cross-frequency interaction and cross-scale feature fusion (Fig. 2). Its cross-frequency branch selectively modulates high-frequency responses using low-frequency structural statistics and key-region priors, while its cross-scale branch controls the transfer of shallow structural features through encoder-decoder skip connections. The network is jointly optimized using basic enhancement, identity consistency, key-region structure, and cross-frequency feature consistency constraints. CelebA is used for main training, and LaPa is used for pose adaptation and evaluation. Identity-level partitioning is adopted to avoid identity leakage, with 90%, 5%, and 5% of identities used for training, validation, and testing, respectively. Synthetic low-light images are generated by brightness attenuation, Gamma mapping, illumination-related noise, chromatic noise, color shifts, and black-level offsets. Dark Face is used only for real low-light evaluation.  Results and Discussions  The proposed model contains 1.47 M parameters and requires 11.74 G floating-point operations for a 256 × 256 input, with an average inference time of 70.48 ms and a speed of approximately 14.19 FPS. On CelebA-Test, the proposed method achieves 25.36 dB PSNR, 0.88 SSIM, 0.8934 ArcFace similarity, 0.0566 Eye-LPIPS, and 0.0753 Mouth-LPIPS, obtaining the best results among the compared methods on all five metrics (Table 1). On LaPa-Test, ΔEAR, Eye-LPIPS, ΔMAR, and Mouth-LPIPS reach 0.0065, 0.0512, 0.1219, and 0.0714, respectively, achieving the best results for all four key-region metrics (Table 2). The ArcFace similarity is 0.9398, lower than those of Low-FaceNet and SCI. Sample-wise analysis shows that this gap is weakly related to pose magnitude and remains in many samples with improved local metrics, indicating partial decoupling between key-region structural fidelity and whole-face identity embedding fidelity. Visual comparisons show improved illumination and better preservation of eye contours, mouth boundaries, and facial textures without obvious local over-enhancement (Fig. 3). On Dark Face, the proposed method obtains a NIQE of 10.92±1.12 and improves face-region visibility in representative samples, while challenging cases reveal limitations under nonuniform illumination, occlusion, and extremely low signal-to-noise ratios (Table 3, Fig. 4). Ablation experiments confirm the complementary effects of the three additional constraints and the joint contribution of CFA, HFM, and FSCM, with the complete model achieving the best overall results (Table 4). Landmark perturbation experiments further show that the continuous Gaussian heatmaps and structural modulation remain stable under spatial deviations of up to ±6 pixels (Table 5).  Conclusions  A structural-prior-guided cross-frequency collaborative method is proposed for low-light face image enhancement. Low-frequency face structures guide high-frequency detail restoration, while local convolution and two-dimensional selective scanning model fine details and long-range dependencies. FSCM further regulates structural feature transfer across frequencies and scales. Experiments on CelebA and LaPa demonstrate advantages in reconstruction quality, key-region structure preservation, and local perceptual consistency. LaPa results also show that local structural improvements do not always yield equivalent gains in whole-face identity embeddings, indicating room for further optimization of global identity consistency. Real low-light and landmark perturbation experiments indicate a certain degree of scene adaptability and robustness to small spatial deviations. However, performance remains limited under severe occlusion, small-scale faces, extreme low-light conditions, and mixed real degradations. Future work will investigate real low-light face data, denser and confidence-aware regional priors, adaptive constraints for different face regions, joint optimization of local structures and global identity representations, and collaborative optimization with downstream facial analysis tasks.
  • loading
  • [1]
    彭大鑫, 甄彤, 李智慧. 低光照图像增强研究方法综述[J]. 计算机工程与应用, 2023, 59(18): 14–27. doi: 10.3778/j.issn.1002-8331.2210-0143.

    PENG Daxin, ZHEN Tong, and LI Zhihui. Survey of research methods for low light image enhancement[J]. Computer Engineering and Applications, 2023, 59(18): 14–27. doi: 10.3778/j.issn.1002-8331.2210-0143.
    [2]
    ZHANG Yonghua, ZHANG Jiawan, and GUO Xiaojie. Kindling the darkness: A practical low-light image enhancer[C]. Proceedings of the 27th ACM International Conference on Multimedia, Nice, France, 2019: 1632–1640. doi: 10.1145/3343031.3350926.
    [3]
    CAI Yuanhao, BIAN Hao, LIN Jing, et al. Retinexformer: One-stage Retinex-based Transformer for low-light image enhancement[C]. Proceedings of 2023 IEEE/CVF International Conference on Computer Vision, Paris, France, 2023: 12470–12479. doi: 10.1109/ICCV51070.2023.01149.
    [4]
    陈勇, 陈东, 刘焕淋, 等. 基于深度卷积神经网络的无参考低照度图像增强[J]. 电子与信息学报, 2022, 44(6): 2166–2174. doi: 10.11999/JEIT210386.

    CHEN Yong, CHEN Dong, LIU Huanlin, et al. Unreferenced low-lighting image enhancement based on deep convolutional neural network[J]. Journal of Electronics & Information Technology, 2022, 44(6): 2166–2174. doi: 10.11999/JEIT210386.
    [5]
    孙帮勇, 赵兴运, 吴思远, 等. 基于移位窗口多头自注意力U型网络的低照度图像增强方法[J]. 电子与信息学报, 2022, 44(10): 3399–3408. doi: 10.11999/JEIT211131.

    SUN Bangyong, ZHAO Xingyun, WU Siyuan, et al. Low-light image enhancement method based on shifted window multi-head self-attention U-shaped network[J]. Journal of Electronics & Information Technology, 2022, 44(10): 3399–3408. doi: 10.11999/JEIT211131.
    [6]
    刘波, 田广粮, 肖斌, 等. 利用自适应光照初始化的弱光图像增强方法[J]. 电子与信息学报, 2024, 46(2): 643–651. doi: 10.11999/JEIT230056.

    LIU Bo, TIAN Guangliang, XIAO Bin, et al. Low light image enhancement with adaptive light initialization[J]. Journal of Electronics & Information Technology, 2024, 46(2): 643–651. doi: 10.11999/JEIT230056.
    [7]
    JIANG Yifan, GONG Xinyu, LIU Ding, et al. EnlightenGAN: Deep light enhancement without paired supervision[J]. IEEE Transactions on Image Processing, 2021, 30: 2340–2349. doi: 10.1109/TIP.2021.3051462.
    [8]
    MA Long, MA Tengyu, LIU Risheng, et al. Toward fast, flexible, and robust low-light image enhancement[C]. Proceedings of 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, USA, 2022: 5627–5636. doi: 10.1109/CVPR52688.2022.00555.
    [9]
    GUO Chunle, LI Chongyi, GUO Jichang, et al. Zero-reference deep curve estimation for low-light image enhancement[C]. Proceedings of 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, USA, 2020: 1777–1786. doi: 10.1109/CVPR42600.2020.00185.
    [10]
    向森, 王应锋, 邓慧萍, 等. 基于双重迭代的零样本低照度图像增强[J]. 电子与信息学报, 2022, 44(10): 3379–3388. doi: 10.11999/JEIT211593.

    XIANG Sen, WANG Yingfeng, DENG Huiping, et al. Zero-shot learning for low-light image enhancement based on dual iteration[J]. Journal of Electronics & Information Technology, 2022, 44(10): 3379–3388. doi: 10.11999/JEIT211593.
    [11]
    乔成平, 金佳堃, 张俊超, 等. 图像增强与特征自适应联合学习的低光图像目标检测方法[J]. 电子与信息学报, 2025, 47(10): 3929–3940. doi: 10.11999/JEIT250302.

    QIAO Chengping, JIN Jiakun, ZHANG Junchao, et al. Low-light object detection via joint image enhancement and feature adaptation[J]. Journal of Electronics & Information Technology, 2025, 47(10): 3929–3940. doi: 10.11999/JEIT250302.
    [12]
    XIANG Yangjun, HU Gengsheng, CHEN Mei, et al. WMANet: Wavelet-based multi-scale attention network for low-light image enhancement[J]. IEEE Access, 2024, 12: 105674–105685. doi: 10.1109/ACCESS.2024.3434531.
    [13]
    ZHANG Jianming, JIANG Jia, FENG Zhijian, et al. Learning spatial-channel feature refiners via wavelet-based linear mixed basis for low-light image enhancement[J]. Knowledge-Based Systems, 2025, 330: 114567. doi: 10.1016/j.knosys.2025.114567.
    [14]
    ZHANG Tongshun, LIU Pingping, LU Yubing, et al. CWNet: Causal wavelet network for low-light image enhancement[C]. Proceedings of 2025 IEEE/CVF International Conference on Computer Vision, Honolulu, USA, 2025: 8789–8799. doi: 10.1109/ICCV51701.2025.00822.
    [15]
    PEI Xiao, HUANG Yongdong, SU Weijian, et al. FFTFormer: A spatial-frequency noise aware CNN-Transformer for low light image enhancement[J]. Knowledge-Based Systems, 2025, 314: 113055. doi: 10.1016/j.knosys.2025.113055.
    [16]
    SHANG Xiaoke, LI Gehui, JIANG Zhiying, et al. Holistic dynamic frequency transformer for image fusion and exposure correction[J]. Information Fusion, 2024, 102: 102073. doi: 10.1016/j.inffus.2023.102073.
    [17]
    李秀梅, 丁林琳, 孙军梅, 等. SR-FDN: 面向图像细节恢复的频域扩散超分辨率重建网络[J]. 电子与信息学报, 2025, 47(10): 3941–3950. doi: 10.11999/JEIT250224.

    LI Xiumei, DING Linlin, SUN Junmei, et al. SR-FDN: A frequency-domain diffusion network for image detail restoration in super-resolution[J]. Journal of Electronics & Information Technology, 2025, 47(10): 3941–3950. doi: 10.11999/JEIT250224.
    [18]
    GUO Hang, GUO Yong, ZHA Yaohua, et al. MambaIRv2: Attentive state space restoration[C]. Proceedings of 2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, USA, 2025: 28124–28133. doi: 10.1109/CVPR52734.2025.02619.
    [19]
    LUAN Xin, FAN Huijie, WANG Qiang, et al. FMambaIR: A hybrid state-space model and frequency domain for image restoration[J]. IEEE Transactions on Geoscience and Remote Sensing, 2025, 63: 4201614. doi: 10.1109/TGRS.2025.3526927.
    [20]
    FAN Yihua, WANG Yongzhen, LIANG Dong, et al. Low-FaceNet: Face recognition-driven low-light image enhancement[J]. IEEE Transactions on Instrumentation and Measurement, 2024, 73: 5019413. doi: 10.1109/TIM.2024.3372230.
    [21]
    ZHOU Shangchen, CHAN K C K, LI Chongyi, et al. Towards robust blind face restoration with codebook lookup transformer[C]. Proceedings of the 36th Conference on Neural Information Processing Systems, New Orleans, USA, 2022: 2218.
    [22]
    WANG Zhouxia, ZHANG Jiawei, CHEN Runjian, et al. RestoreFormer: High-quality blind face restoration from undegraded key-value pairs[C]. Proceedings of 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, USA, 2022: 17491–17500. doi: 10.1109/CVPR52688.2022.01699.
    [23]
    LIU Ziwei, LUO Ping, WANG Xiaogang, et al. Deep learning face attributes in the wild[C]. Proceedings of 2015 IEEE International Conference on Computer Vision, Santiago, Chile, 2015: 3730–3738. doi: 10.1109/ICCV.2015.425.
    [24]
    LIU Yinglu, SHI Hailin, SHEN Hao, et al. A new dataset and boundary-attention semantic segmentation for face parsing[C]. Proceedings of the 34th AAAI Conference on Artificial Intelligence, New York, USA, 2020: 11637–11644. doi: 10.1609/aaai.v34i07.6832.
    [25]
    YANG Wenhan, YUAN Ye, REN Wenqi, et al. Advancing image understanding in poor visibility environments: A collective benchmark study[J]. IEEE Transactions on Image Processing, 2020, 29: 5737–5752. doi: 10.1109/TIP.2020.2981922.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(4)  / Tables(5)

    Article Metrics

    Article views (33) PDF downloads(2) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return