Advanced Search
Turn off MathJax
Article Contents
LIN Jiaqi①②, WANG Yong③, LIN Xin④, YAN Shi①②, XU Xin④, GU Jiangchun④, ZHANG Senbai⑤. A Multi-Agent Active-Inference Collaborative Decision-Making Method for Space-Air-Ground Integrated Networks[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260727
Citation: LIN Jiaqi①②, WANG Yong③, LIN Xin④, YAN Shi①②, XU Xin④, GU Jiangchun④, ZHANG Senbai⑤. A Multi-Agent Active-Inference Collaborative Decision-Making Method for Space-Air-Ground Integrated Networks[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260727

A Multi-Agent Active-Inference Collaborative Decision-Making Method for Space-Air-Ground Integrated Networks

doi: 10.11999/JEIT260727 cstr: 32379.14.JEIT260727
Funds:  Jiangsu Provincial Key Basic Research Project, SBK20251000101. National Science and Technology Major Project of China, GXB-2-2025-5. National Natural Science Foundation of China, 62371067. Beijing Natural Science Foundation, Grant L223007
  • Received Date: 2026-06-01
  • Accepted Date: 2026-08-17
  • Rev Recd Date: 2026-08-17
  • Available Online: 2026-09-18
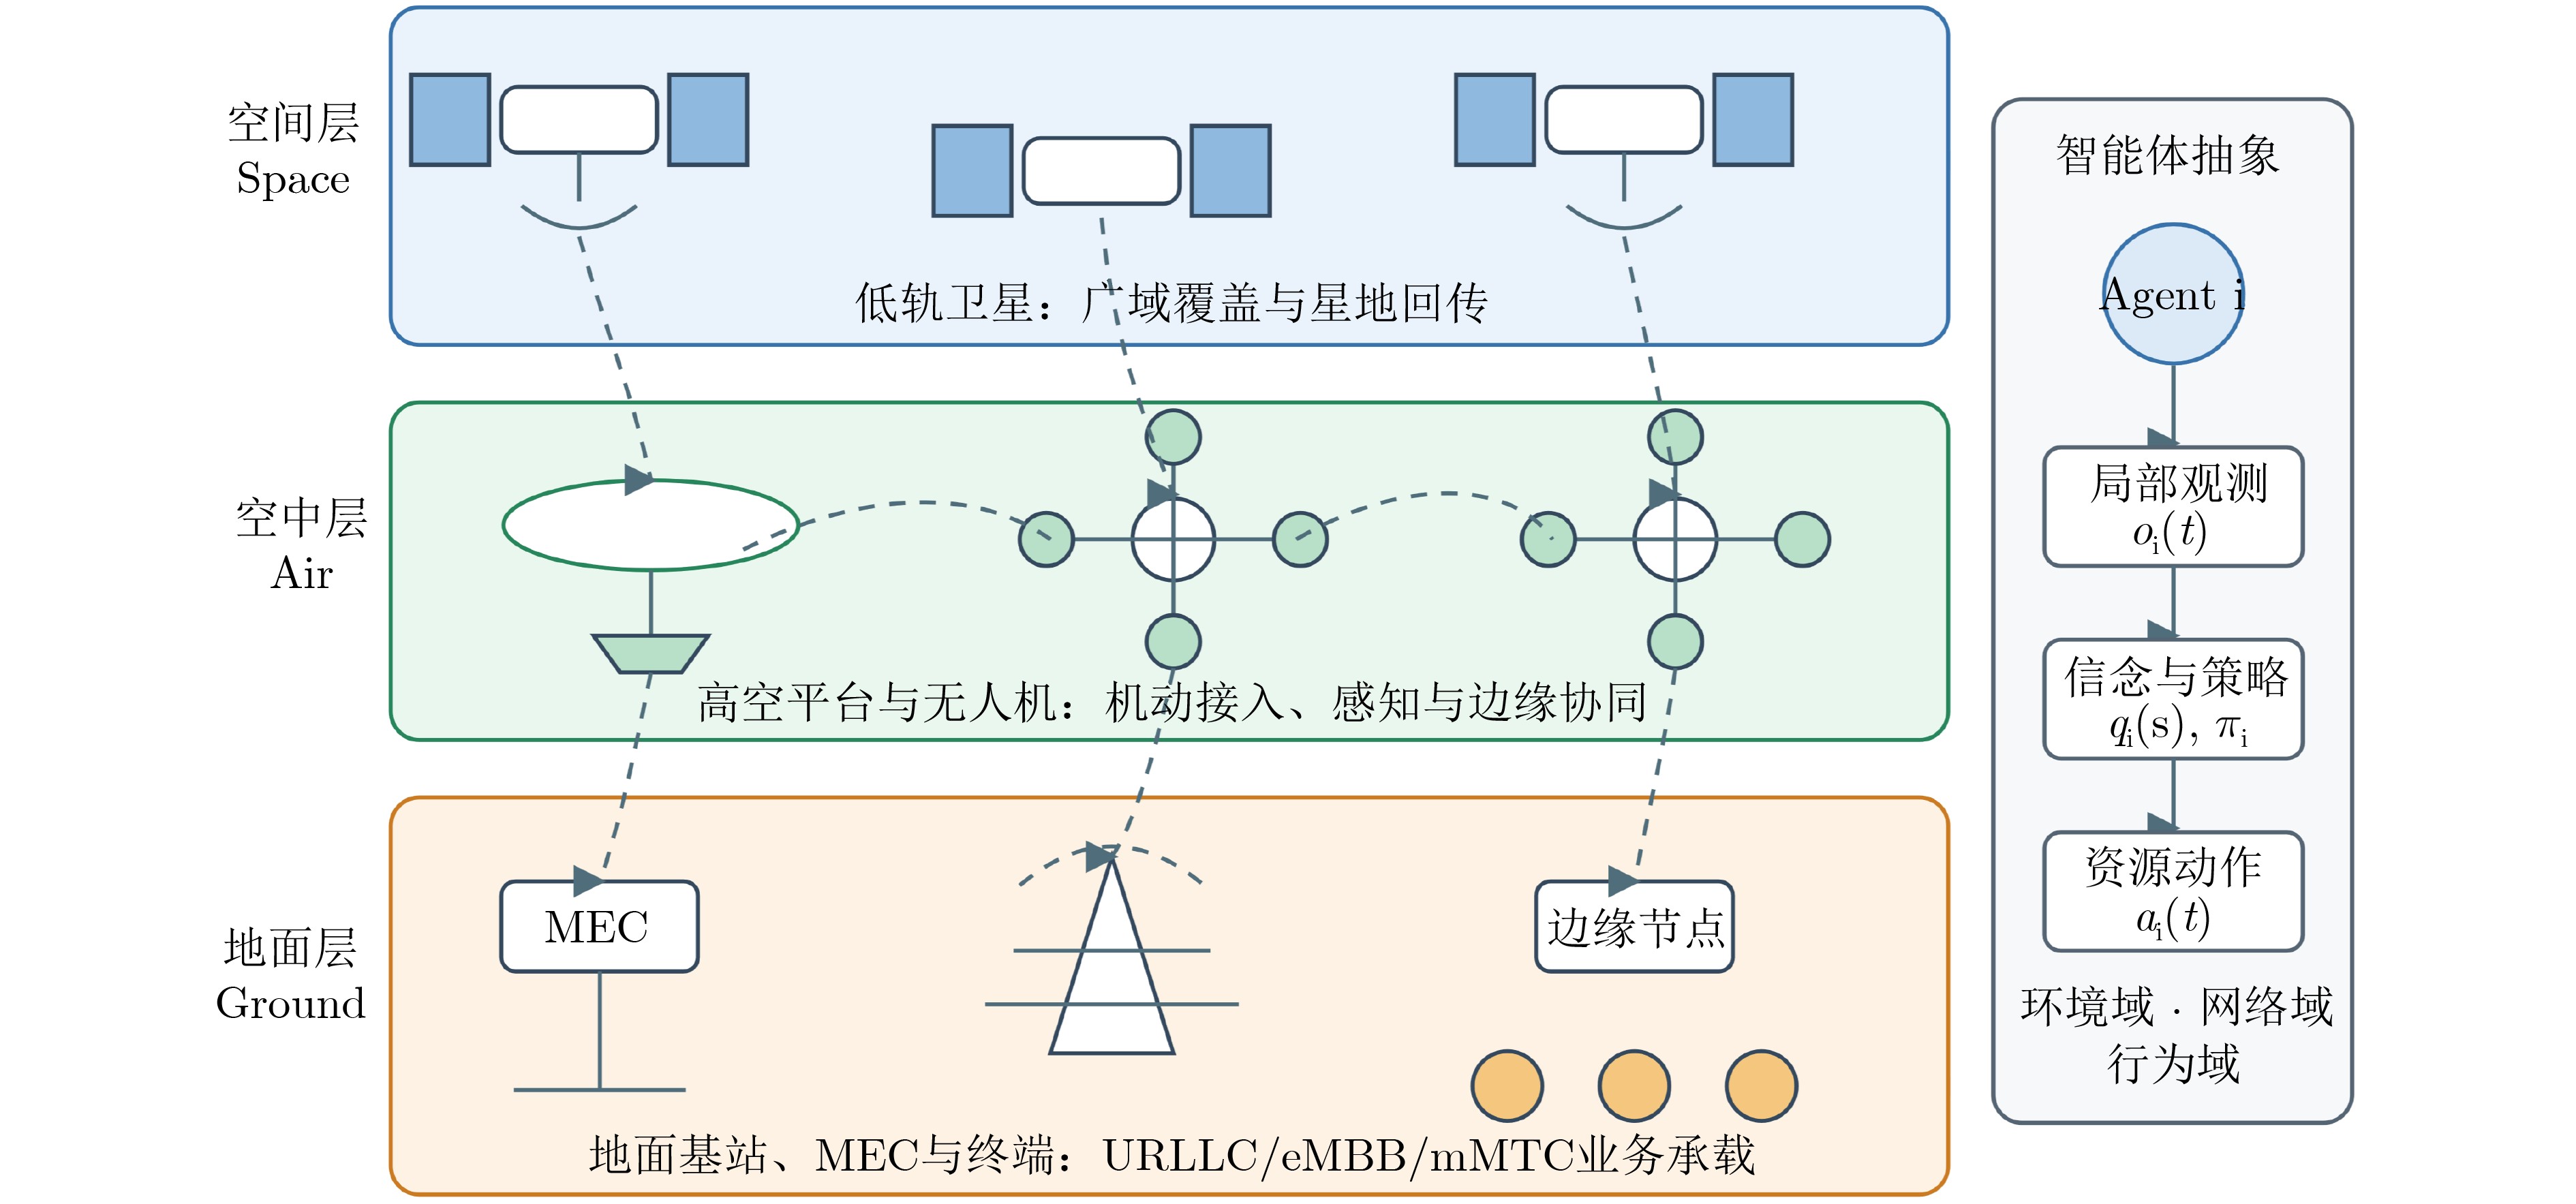
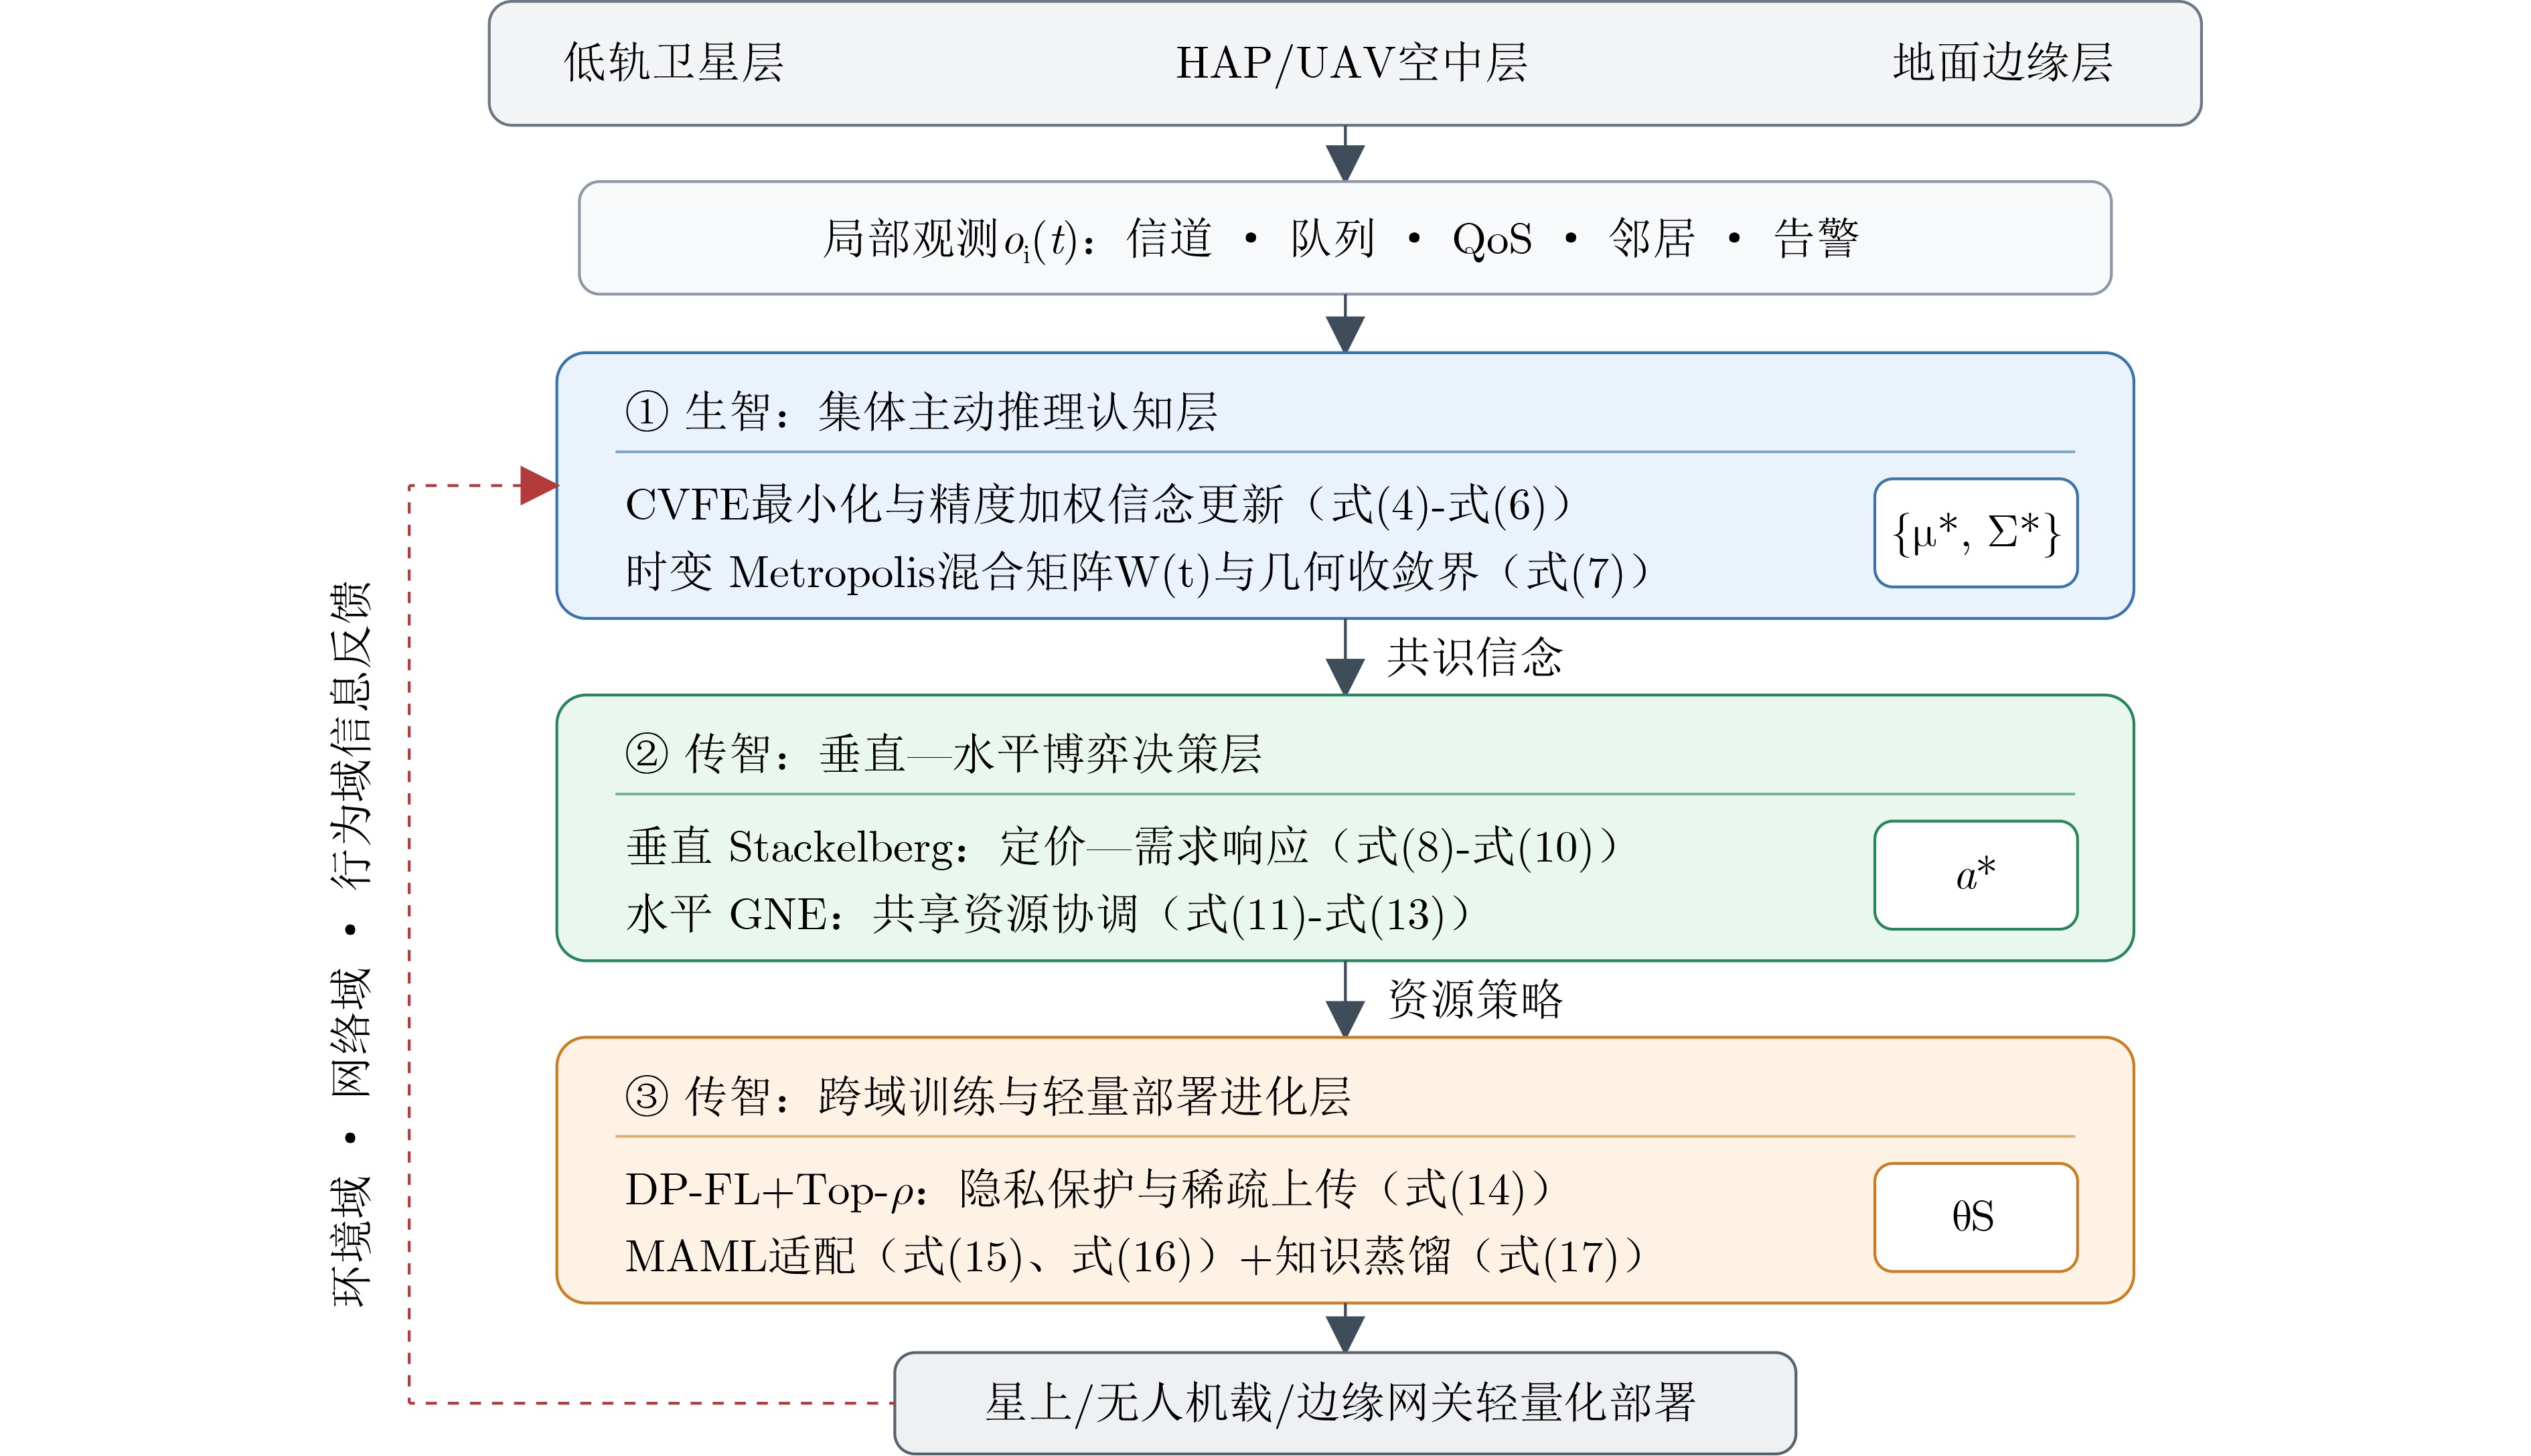
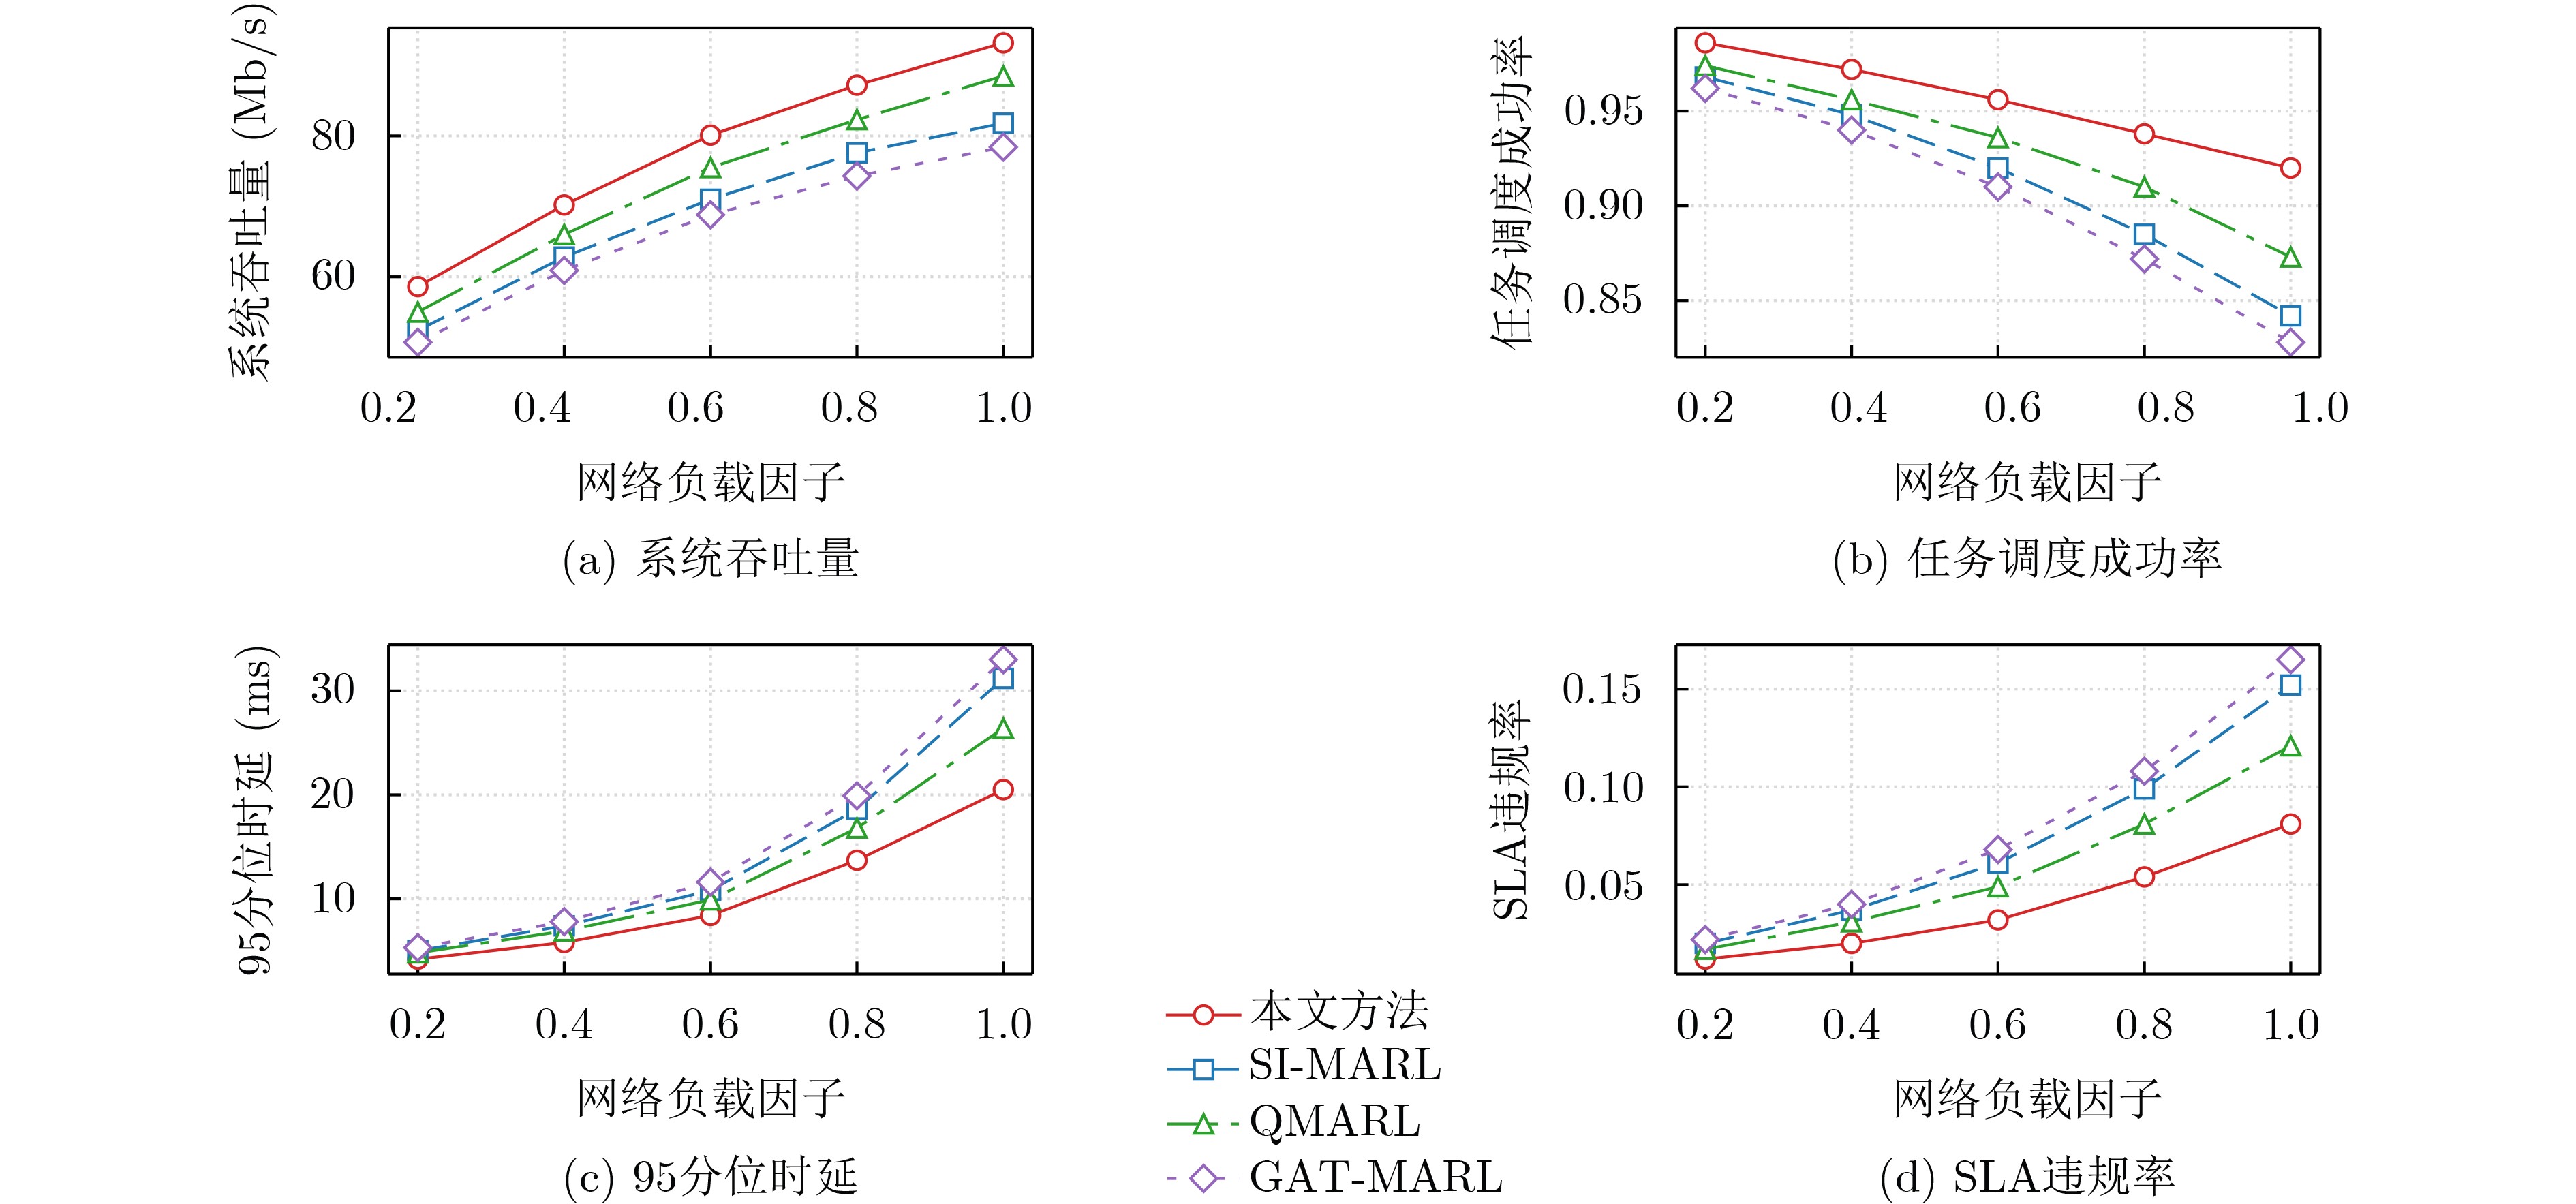
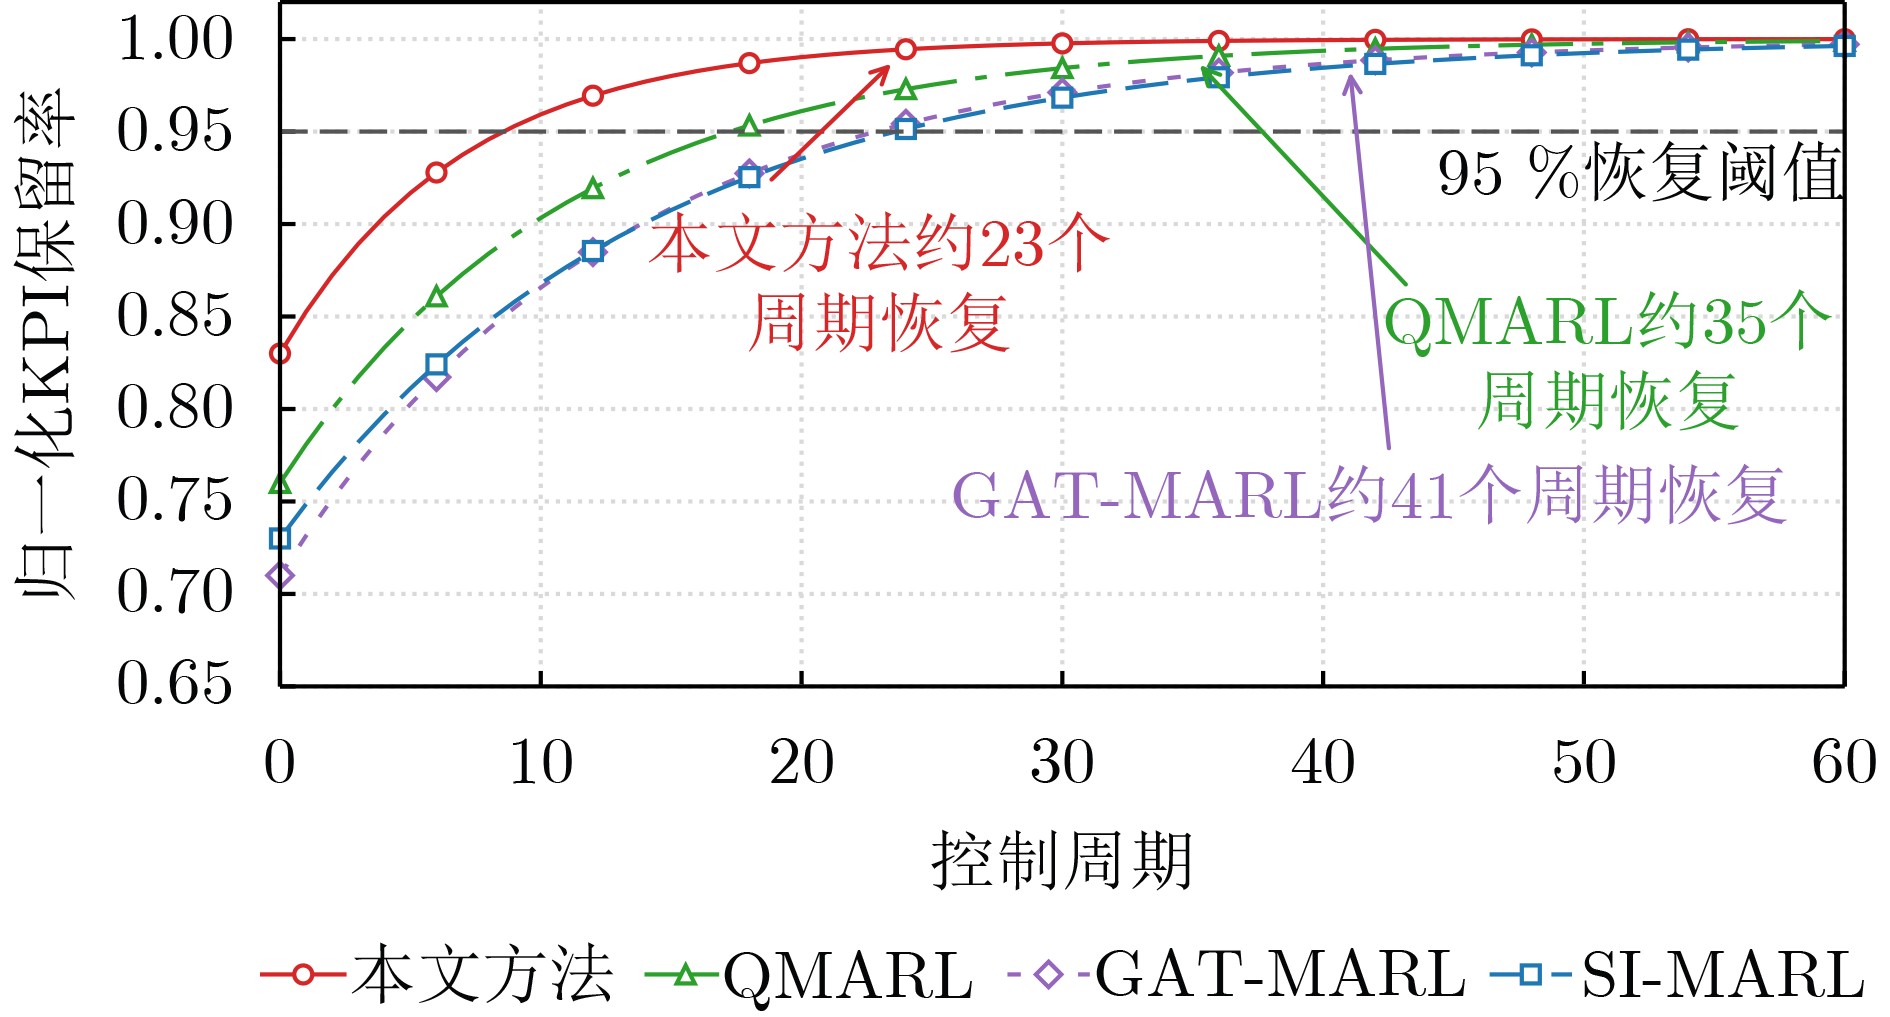
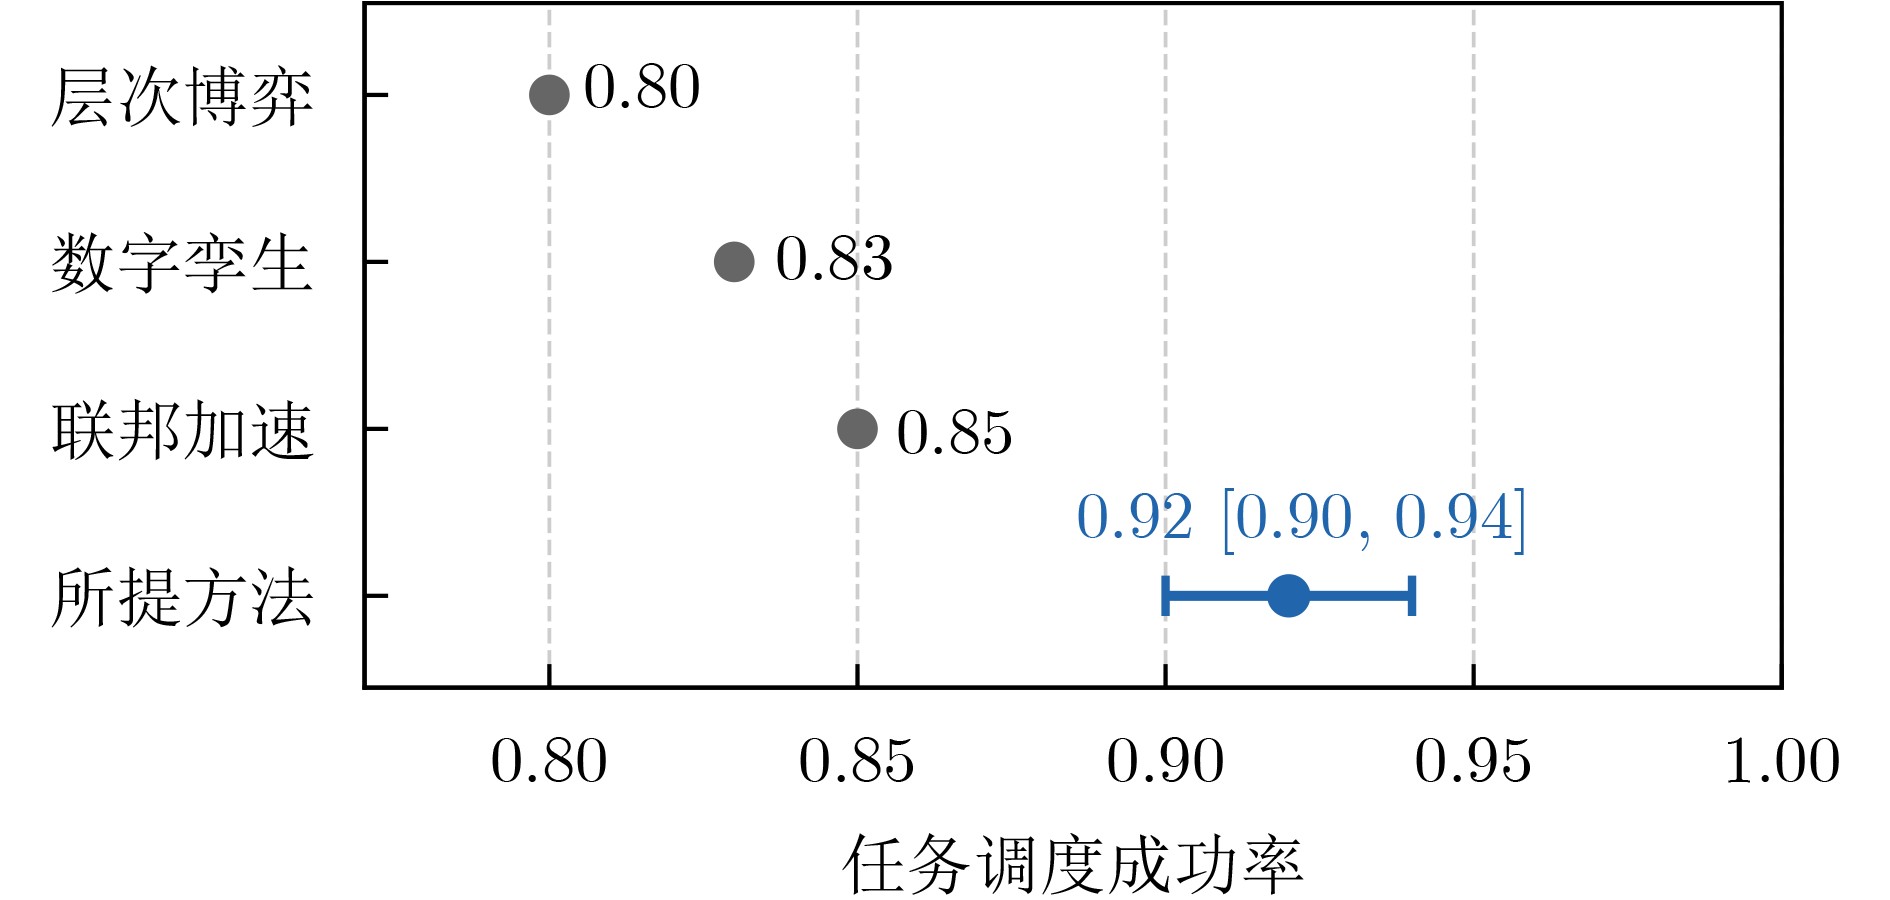
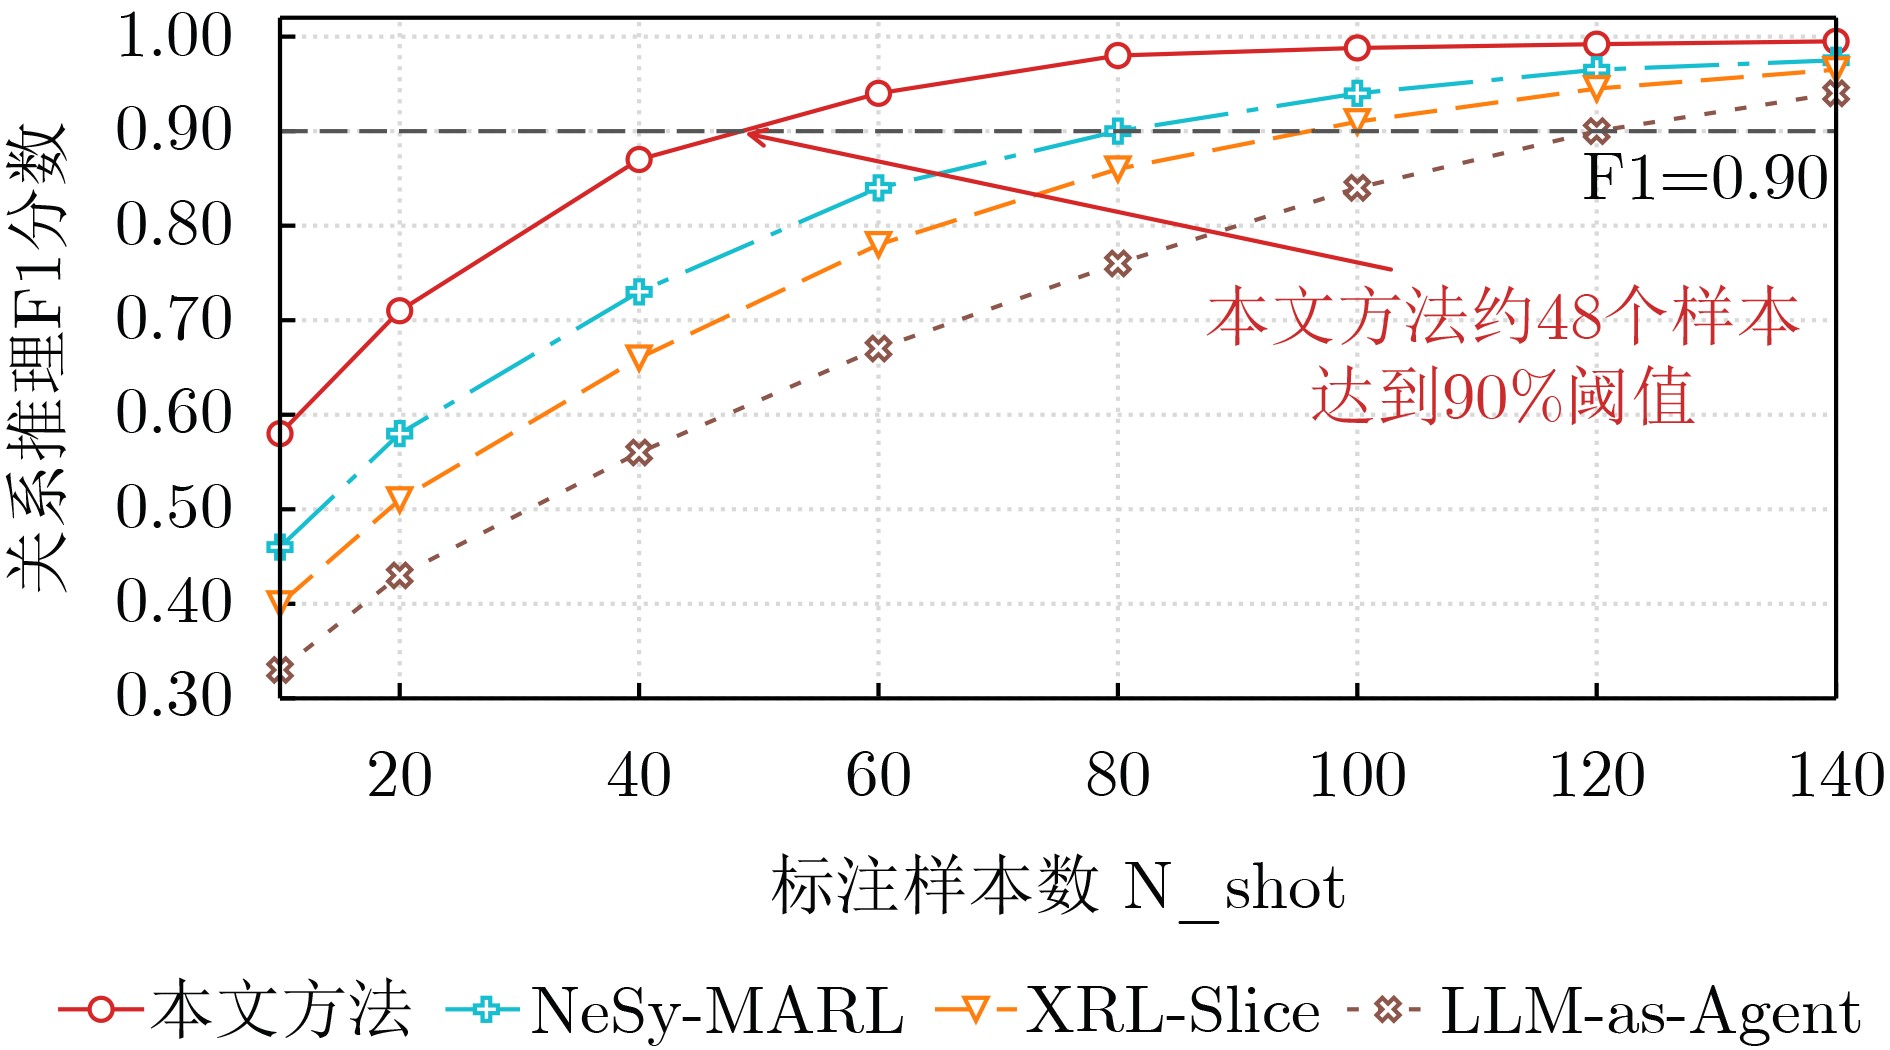
  •   Objective  Space-Air-Ground Integrated Networks (SAGINs) combine satellites, aerial platforms, terrestrial access points, and edge nodes to support heterogeneous services in highly dynamic domains. Collaboration is difficult under local, delayed observations, time-varying topology, restricted raw-data exchange, and coupled spectrum, power, and computing resources. Existing multi-agent reinforcement learning (MARL) and game methods do not jointly address uncertainty-aware semantic consensus, hierarchical resource allocation, cross-domain adaptation, and lightweight deployment. This study develops a Collective Active Inference (CAI)-based intelligence-generation/transmission loop in which agents exchange inferred beliefs rather than raw observations, consensus beliefs drive resource decisions, and learned models are adapted and compressed for constrained satellite and edge nodes. The scope is a time-varying, partially observable SAGIN evaluated in an Open Radio Access Network (O-RAN) system-level simulation, not an operational deployment.  Methods  The problem is formulated as a time-varying decentralized partially observable Markov decision process over channel, queue, congestion, interference, and node states. The formulation explicitly captures decentralized decisions under incomplete information and intermittent connectivity. Multi-agent cognition is modeled by minimizing Collective Variational Free Energy (CVFE): a likelihood term preserves local observation fidelity, while a Kullback-Leibler term penalizes disagreement between neighboring beliefs. A Gaussian precision-weighted update favors reliable beliefs. Symmetric Metropolis weights yield a doubly stochastic mixing matrix; consensus error decreases geometrically with the second-largest eigenvalue modulus and extends to intermittent links under B-joint connectivity. Agents exchange only belief means/covariances and act on the converged belief (Algorithm 1). A vertical-horizontal game maps consensus to resources. An operator serves as the Stackelberg leader, while service slices respond to prices; horizontally, slices form a generalized Nash game under shared spectrum, power, and service-level constraints. Cross-domain evolution combines differentially private federated learning, Top-10% update sparsification, Model-Agnostic Meta-Learning, and knowledge distillation. The distillation temperature is 4, with supervised and distillation weights of 0.3 and 0.7. Evaluation uses an OMNeT++ O-RAN simulator with 12 coverage nodes, 19 underlay nodes, 72 links, a 28 GHz carrier, and 100 MHz bandwidth. Concurrent Ultra-Reliable and Low-Latency Communications, enhanced Mobile Broadband, and massive Machine-Type Communications traffic is simulated for 10 000 control periods. The network-load factor rises from 0.2 to 1.0, while frequency-sweeping interference and traffic bursts test out-of-distribution recovery. Baselines use the same observations, action space, constraints, training budget, and random-seed set; values are averaged over at least 10 independent runs with 95% confidence intervals.  Results and Discussions  At full load, the method reaches 93.2 Mb/s throughput, versus 81.8, 88.5, and 78.4 Mb/s for symmetry-informed MARL (SI-MARL), quantum MARL (QMARL), and graph-attention-network-based MARL (GAT-MARL). Its task-scheduling success rate is 0.92, its 95th-percentile latency is 20.5 ms rather than 31.2, 26.4, and 33.0 ms, and its service-level-agreement violation rate is approximately 0.081 (Fig. 3). After an out-of-distribution disturbance, the retained key-performance-indicator level is about 0.83 and recovery to the 95% threshold requires 23 control periods, compared with 35 and 41 for QMARL and GAT-MARL (Fig. 4). In resource competition, the mean scheduling success rate is 0.92 with a 95% confidence interval of [0.90, 0.94], exceeding three hierarchical-game or federated-game baselines ranging from 0.80 to 0.85 (Fig. 5). With 50 agents and an update dimension of 80, Top-10% sparsification reduces transmitted updates from 321.79×10³ to 34.58×10³ scalars, an 89.3% reduction, while convergence rounds rise from 58.84 to 71.26, or 21.1% (Table 1). For few-shot relation inference, F1 scores are 0.71 with 20 labels and 0.98 with 80 labels; about 48 labels reach 0.90, compared with 75, 90, and 120 for the baselines (Fig. 6). Distillation reduces model size from 1 050 KB to 160 KB and inference latency from 21 ms to 15 ms. The student retains 91% task success and 93% path efficiency, while the teacher achieves 95% and 97%; removing environmental-domain information causes the largest path-efficiency loss (Table 2).  Conclusions  The proposed CAI method connects precision-weighted semantic consensus, hierarchical resource coordination, privacy-preserving model evolution, few-shot adaptation, and lightweight deployment in one closed loop. Theory relates consensus speed to graph connectivity, while the O-RAN simulation shows improvements in throughput, tail latency, reliability, disturbance recovery, communication efficiency, and deployment cost under the stated settings. Limitations include simulated channels, idealized observation quality, synchronous updates, and modeled prior distributions that may differ from operational conditions. These findings are not performance guarantees for arbitrary operational networks; validation with measured channels, hardware-in-the-loop tests, and field experiments remains necessary.
  • loading
  • [1]
    GUO Hongzhi, LI Jingyi, LIU Jiajia, et al. A survey on space-air-ground-sea integrated network security in 6G[J]. IEEE Communications Surveys & Tutorials, 2022, 24(1): 53–87. doi: 10.1109/COMST.2021.3131332.
    [2]
    王雪, 孟姝宇, 钱志鸿. 面向6G全域融合的智能接入关键技术综述[J]. 电子与信息学报, 2024, 46(5): 1613–1631. doi: 10.11999/JEIT231224.

    WANG Xue, MENG Shuyu, and QIAN Zhihong. An overview of key technologies for intelligent access toward 6G full-domain convergence[J]. Journal of Electronics & Information Technology, 2024, 46(5): 1613–1631. doi: 10.11999/JEIT231224.
    [3]
    林佳琦, 钱琪杰, 钟旭东, 等. 面向6G的知识驱动“自智”网络架构[J]. 通信学报, 2025, 46(10): 40–62. doi: 10.11959/j.issn.1000-436x.2025159.

    LIN Jiaqi, QIAN Qijie, ZHONG Xudong, et al. Knowledge-driven “self-intelligent” network architecture for 6G[J]. Journal on Communications, 2025, 46(10): 40–62. doi: 10.11959/j.issn.1000-436x.2025159.
    [4]
    SHI Rongye, YU Xin, WANG Yandong, et al. Symmetry-Informed MARL: A decentralized and cooperative UAV swarm control approach for communication coverage[J]. IEEE Transactions on Mobile Computing, 2025, 24(9): 8039–8056. doi: 10.1109/TMC.2025.3553285.
    [5]
    KIM G S, CHO Y, CHUNG J, et al. Quantum multi-agent reinforcement learning for cooperative mobile access in space-air-ground integrated networks[J]. IEEE Transactions on Mobile Computing, 2026, 25(1): 1200–1218. doi: 10.1109/TMC.2025.3599683.
    [6]
    AO Tianyong, LI Haoqiang, ZHANG Kaixin, et al. Heterogeneous UAVs trajectory optimization for post-disaster target search based on MARL with graph attention network[J]. IEEE Transactions on Vehicular Technology, 2026, 75(1): 1412–1426. doi: 10.1109/TVT.2025.3594534.
    [7]
    ZHANG Jianshu and WU Xiaofu. Cooperative jamming over DRL-based frequency hopping wireless communications: A one-leader multi-follower Stackelberg game approach[J]. IEEE Transactions on Information Forensics and Security, 2025, 20: 9220–9234. doi: 10.1109/TIFS.2025.3604229.
    [8]
    LIN Xin, LIU Aijun, HAN Chen, et al. Intelligent adaptive MIMO transmission for nonstationary communication environment: A deep reinforcement learning approach[J]. IEEE Transactions on Communications, 2025, 73(8): 5965–5979. doi: 10.1109/TCOMM.2025.3529263.
    [9]
    LI Peixuan, WANG Yichen, WANG Zhangnan, et al. Joint task offloading and resource allocation strategy for hybrid MEC-enabled LEO satellite networks: A hierarchical game approach[J]. IEEE Transactions on Communications, 2025, 73(5): 3150–3166. doi: 10.1109/TCOMM.2024.3478111.
    [10]
    CHEN Tianjiao, WANG Xiaoyun, HUA Meihui, et al. Incentive-based task offloading for digital twins in 6G native artificial intelligence networks: A learning approach[J]. Frontiers of Information Technology & Electronic Engineering, 2025, 26(2): 214–229. doi: 10.1631/FITEE.2400240.
    [11]
    WANG Kaidi, MA Yi, MASHHADI M B, et al. Convergence acceleration in wireless federated learning: A Stackelberg game approach[J]. IEEE Transactions on Vehicular Technology, 2025, 74(1): 714–729. doi: 10.1109/TVT.2024.3452933.
    [12]
    张鸿, 廖彧歆, 王汝言, 等. 面向密集场景的空天地网络资源分配算法[J]. 电子与信息学报, 2024, 46(5): 1968–1976. doi: 10.11999/JEIT231086.

    ZHANG Hong, LIAO Yuxin, WANG Ruyan, et al. Resource allocation algorithm of space-air-ground integrated network for dense scenarios[J]. Journal of Electronics & Information Technology, 2024, 46(5): 1968–1976. doi: 10.11999/JEIT231086.
    [13]
    林艳, 夏开元, 张一晋. 基于生成对抗网络辅助多智能体强化学习的边缘计算网络联邦切片资源管理[J]. 电子与信息学报, 2025, 47(3): 666–677. doi: 10.11999/JEIT240773.

    LIN Yan, XIA Kaiyuan, and ZHANG Yijin. Federated slicing resource management in edge computing networks based on GAN-assisted multi-agent reinforcement learning[J]. Journal of Electronics & Information Technology, 2025, 47(3): 666–677. doi: 10.11999/JEIT240773.
    [14]
    REZAZADEH F, CHERGUI H, and MANGUES-BAFALLUY J. Explanation-guided deep reinforcement learning for trustworthy 6G RAN slicing[C]. 2023 IEEE International Conference on Communications Workshops (ICC Workshops), Rome, Italy, 2023: 1026–1031. doi: 10.1109/ICCWorkshops57953.2023.10283684.
    [15]
    HONG J, VAN TU N, and HONG J W K. A comprehensive survey on LLM-based network management and operations[J]. International Journal of Network Management, 2025, 35(6): e70029. doi: 10.1002/nem.70029.
    [16]
    SUBRAMANIAN A, BHATTACHARJEE A, GUPTA S K, et al. A neuro-symbolic approach to multi-agent RL for interpretability and probabilistic decision making[C]. AAAI Spring Symposium on User-Aligned Assessment of Adaptive AI Systems, Stanford, USA, 2024. (查阅网上资料, 未找到本条文献信息, 请确认).
    [17]
    FRISTON K, FITZGERALD T, RIGOLI F, et al. Active inference: A process theory[J]. Neural Computation, 2017, 29(1): 1–49. doi: 10.1162/NECO_a_00912.
    [18]
    NEDIC A and OZDAGLAR A. Distributed subgradient methods for multi-agent optimization[J]. IEEE Transactions on Automatic Control, 2009, 54(1): 48–61. doi: 10.1109/TAC.2008.2009515.
    [19]
    FINN C, ABBEEL P, and LEVINE S. Model-agnostic meta-learning for fast adaptation of deep networks[C]. Proceedings of the 34th International Conference on Machine Learning, Sydney, Australia, 2017: 1126–1135.
    [20]
    HINTON G, VINYALS O, and DEAN J. Distilling the knowledge in a neural network[EB/OL]. https://arxiv.org/abs/1503.02531, 2015. doi: 10.48550/arXiv.1503.02531.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(6)  / Tables(3)

    Article Metrics

    Article views (35) PDF downloads(3) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return