Advanced Search
Turn off MathJax
Article Contents
LI Ke, LIN Huairong, TONG Junyang, ZHANG Yang, WANG Dongliang, ZHOU Kai, WU Songtao. FD-Mamba:A Frequency-Decoupled State Space Model for Visible-Infrared Person Re-Identification[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260661
Citation: LI Ke, LIN Huairong, TONG Junyang, ZHANG Yang, WANG Dongliang, ZHOU Kai, WU Songtao. FD-Mamba:A Frequency-Decoupled State Space Model for Visible-Infrared Person Re-Identification[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260661

FD-Mamba:A Frequency-Decoupled State Space Model for Visible-Infrared Person Re-Identification

doi: 10.11999/JEIT260661 cstr: 32379.14.JEIT260661
  • Received Date: 2026-05-20
  • Accepted Date: 2026-09-28
  • Rev Recd Date: 2026-09-18
  • Available Online: 2026-10-13
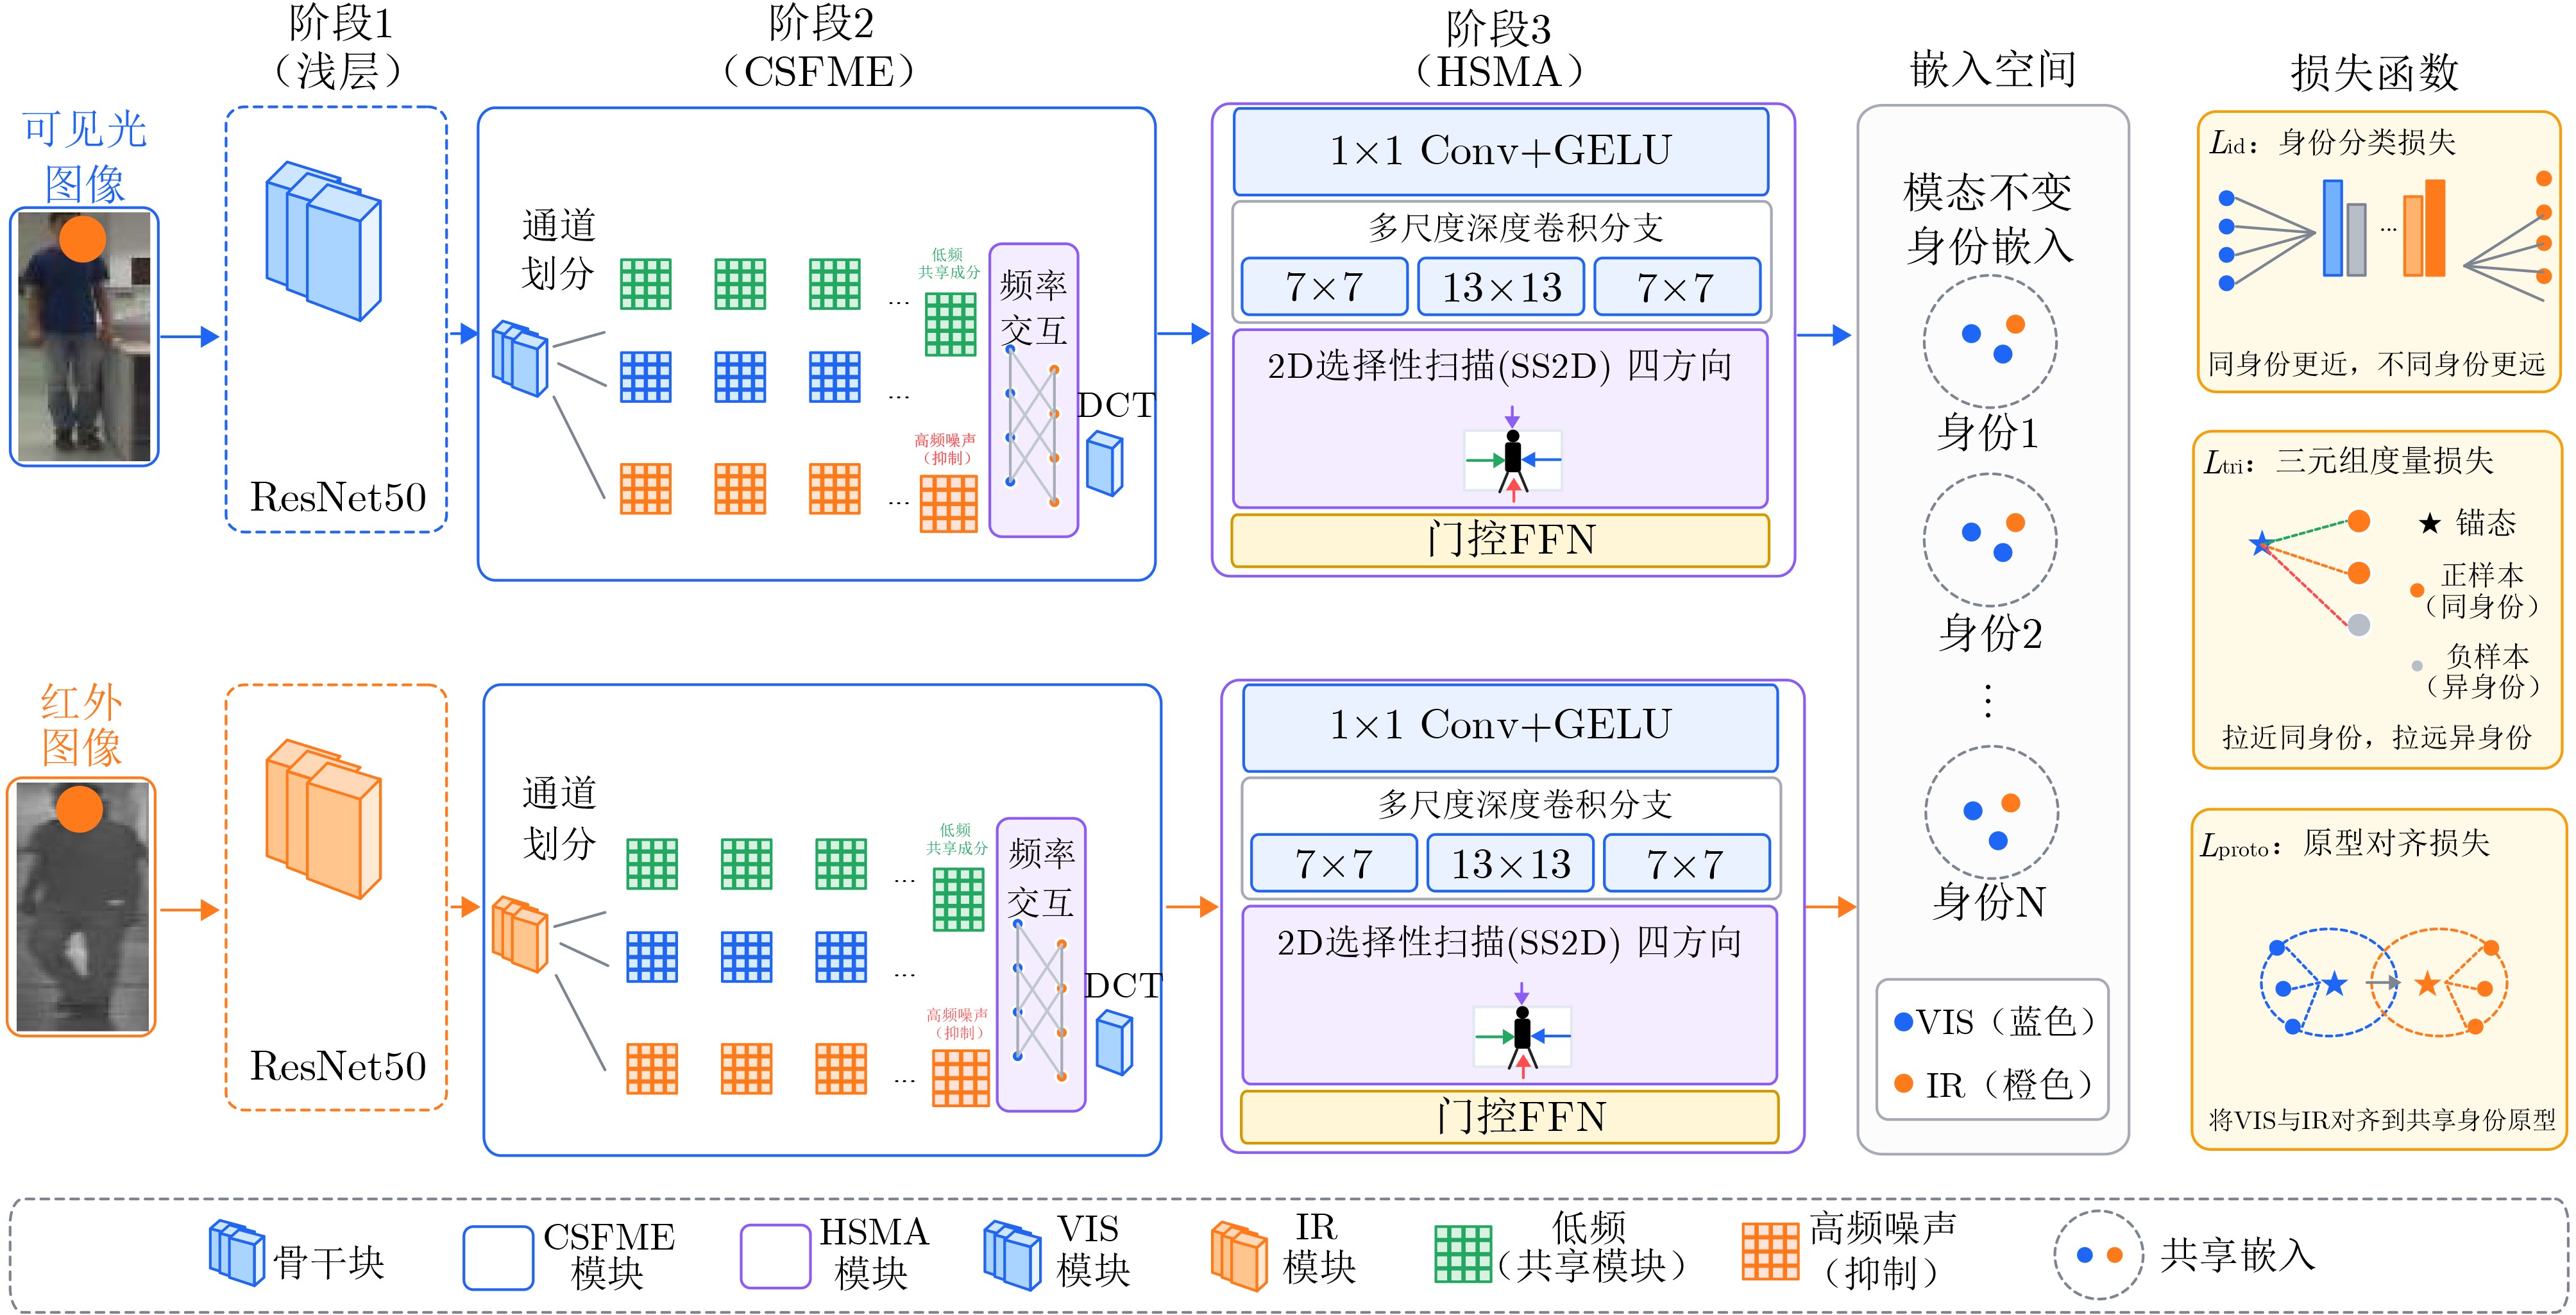
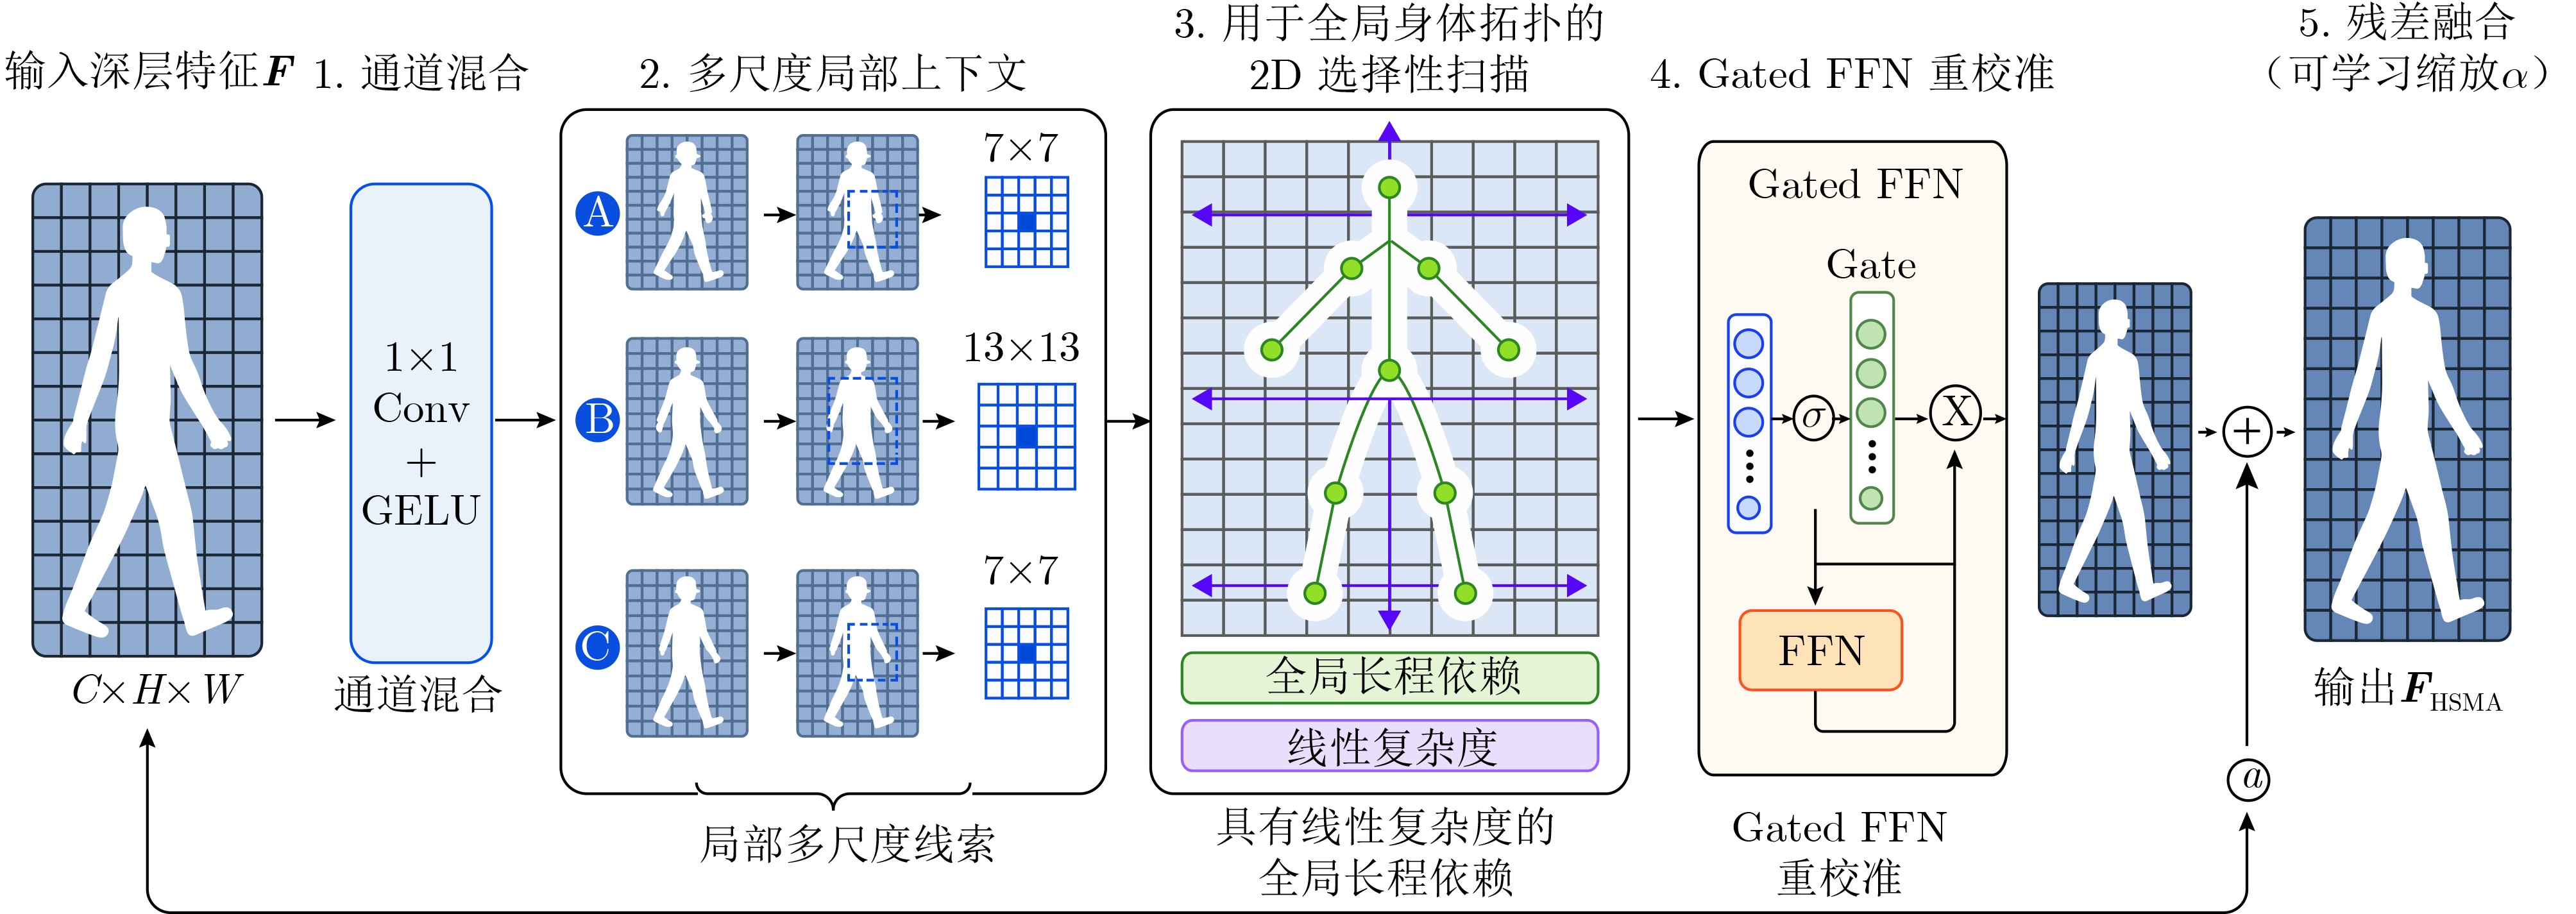
  •   Objective  Visible-infrared person re-identification (VI-ReID) aims to retrieve the same pedestrian identity across heterogeneous visible and infrared cameras, and is a key technique for all-day intelligent surveillance and cross-modal retrieval. The task remains challenging because visible images are formed by reflected light and carry rich color and texture, whereas infrared images are formed by thermal radiation and mainly describe body contours and thermal responses, which causes a large spectral gap and inconsistent local appearance. Viewpoint changes, pose variations, occlusion, and detection misalignment further weaken the spatial correspondence between body parts. Convolutional methods extract local cues effectively but describe global body topology poorly, while Transformer-based methods model long-range dependencies at a quadratic cost that limits practical deployment. More importantly, most existing methods align features only in the spatial domain and ignore the different roles of frequency components: low-frequency components preserve the body shape and structural layout shared by both modalities, whereas high-frequency components mainly carry visible texture, illumination edges, infrared thermal noise, and other modality-specific disturbances. To address these limitations, this paper proposes a frequency-decoupled state space model, termed FD-Mamba, that jointly enhances spatial structural modeling and frequency-domain cross-modal alignment. The proposed design is further motivated by the observation that cross-modal discrepancy does not affect all frequency components equally. Separating shared structural information from modality-specific responses therefore provides a more targeted way to improve modality invariance than treating all spectral components uniformly.  Methods  As illustrated in Fig. 1, FD-Mamba is built upon a dual-stream ResNet-50 backbone. Shallow stages use modality-specific branches to preserve modality-dependent low-level cues, while deeper stages share weights to project both modalities into a common semantic space. Two modules are introduced. First, a Hybrid Spatial Mamba Attention (HSMA) module is designed for deep semantic features, as shown in Fig. 3. HSMA combines multi-scale convolution with two-dimensional selective scanning: the convolution branch extracts local body-part patterns under different receptive fields, while the scanning branch propagates contextual information along multiple spatial directions, following the selective scan of Fig. 2, so that long-range interactions among the head, torso, legs, and carried objects are captured and more complete identity-related representations are obtained without relying only on isolated local textures. Second, a Cross-Scale Frequency Mamba Enhancement (CSFME) module is constructed for shallow and intermediate features, as shown in Fig. 4. CSFME divides feature channels into groups and projects them into the frequency domain through multi-scale two-dimensional Discrete Cosine Transform. The DCT coefficients of each group are partitioned into zigzag-ordered frequency bands and reweighted by a learnable band-gating mechanism, so that high-frequency modality noise is suppressed softly rather than truncated. The reweighted bands are then coupled by a frequency-aware state-space process, transformed back to the spatial domain by inverse DCT, and recalibrated by pixel and channel attention. Modality-specific noise is thus suppressed and low-frequency shared structural cues enhanced, providing more robust features for subsequent spatial alignment. The whole network is trained end-to-end with the identity, metric, and prototype-related constraints inherited from the baseline protocol. Both modules are inserted into the original backbone in a residual manner, so the enhanced representations retain the original identity information while introducing complementary spatial and frequency cues. This design also limits the additional computational cost and preserves the overall training protocol of the baseline.  Results and Discussions  Experiments are conducted on three representative VI-ReID benchmarks, SYSU-MM01, RegDB, and LLCM, which cover large-scale cross-camera retrieval, bidirectional visible-infrared matching, and low-light cross-modal scenarios, respectively. As reported in Table 1, FD-Mamba achieves 79.71% Rank-1 and 77.52% mAP on SYSU-MM01 under the all-search mode, improving the strong PDM baseline by 2.76 and 3.27 percentage points and indicating that the spatial-frequency collaborative design benefits both top-ranked accuracy and overall ranking quality. Competitive performance is also obtained under indoor-search. On RegDB, FD-Mamba achieves 95.2% Rank-1 and 89.3% mAP in the VIS to IR direction, and 94.7% Rank-1 and 87.5% mAP in the IR to VIS direction. The close results in both directions suggest that the model learns a relatively symmetric cross-modal representation rather than relying on a fixed query modality. The retrieval examples in Fig.5(b) further show that FD-Mamba reduces incorrect top-ranked matches compared with the baseline model. As shown in Table 2, FD-Mamba remains stable on the more challenging LLCM dataset, obtaining 65.3% Rank-1 and 67.8% mAP for Visible-to-Infrared retrieval and 57.5% Rank-1 and 63.9% mAP for Infrared-to-Visible retrieval, indicating robustness under low illumination, background clutter, and local texture degradation. Ablation studies in Tables 4 and 5 show that HSMA improves Rank-1 and mAP by 1.15 and 2.50 percentage points and CSFME by 0.90 and 1.25 percentage points, while their combination performs best, demonstrating the complementarity between global spatial topology modeling and frequency-domain noise suppression. Spectral statistics and band-limited recognition experiments quantitatively support the frequency-decoupling assumption. Additional analyses show that the gains are not produced by a single component. The frequency-domain experiments indicate that low-frequency information is more stable across modalities, whereas high-frequency responses contain stronger modality-specific variations, which is consistent with the improvements brought by learnable frequency-band reweighting. FD-Mamba contains 42.6M parameters and 8.51G FLOPs, only 1.83% and 2.90% more than the baseline, with comparable throughput and latency on an RTX 4090 GPU. The attention maps in Fig. 5(a) show more continuous pedestrian foreground responses than the baseline, and the feature distance distributions and t-SNE visualization in Fig. 6 further reveal smaller intra-class cross-modal distances and clearer inter-class margins, indicating improved identity discrimination and modality consistency.  Conclusions  This paper presents FD-Mamba, a frequency-decoupled state space model for visible-infrared person re-identification. The HSMA module improves global body-structure modeling through hybrid spatial scanning, and the CSFME module introduces explicit frequency decomposition to suppress modality-specific disturbances while preserving shared structural information. Quantitative comparisons, ablation studies, and visual analyses consistently show that the proposed spatial-frequency collaborative framework improves both identity discrimination and cross-modal consistency, making it suitable for all-day cross-modal pedestrian retrieval and suggesting that frequency-aware state-space modeling is a promising direction for heterogeneous visual representation learning.The current framework is still evaluated mainly under supervised benchmark protocols. Future work will investigate unsupervised cross-modal settings and more lightweight state-space designs to further improve generalization and deployment efficiency in practical surveillance scenarios.
  • loading
  • [1]
    YE Mang, SHEN Jianbing, LIN Gaojie, et al. Deep learning for person re-identification: A survey and outlook[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2022, 44(6): 2872–2893. doi: 10.1109/TPAMI.2021.3054775.
    [2]
    YE Mang, SHEN Jianbing, CRANDALL D J, et al. Dynamic dual-attentive aggregation learning for visible-infrared person re-identification[C]. Proceedings of the 16th European Conference on Computer Vision-ECCV 2020, Glasgow, UK, 2020: 229–247. doi: 10.1007/978-3-030-58520-4_14.
    [3]
    HE Shuting, LUO Hao, WANG Pichao, et al. TransReID: Transformer-based object re-identification[C]. Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, Canada, 2021: 14993–15002. doi: 10.1109/ICCV48922.2021.01474.
    [4]
    YU Hao, CHENG Xu, PENG Wei, et al. Modality unifying network for visible-infrared person re-identification[C]. Proceedings of the 2023 IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 2023: 11151–11161. doi: 10.1109/ICCV51070.2023.01027.
    [5]
    张红颖, 樊世钰, 罗谦, 等. 结合视觉文本匹配和图嵌入的可见光-红外行人重识别[J]. 电子与信息学报, 2024, 46(9): 3662–3671. doi: 10.11999/JEIT240318.

    ZHANG Hongying, FAN Shiyu, LUO Qian, et al. Visible-infrared person re-identification combining visual-textual matching and graph embedding[J]. Journal of Electronics & Information Technology, 2024, 46(9): 3662–3671. doi: 10.11999/JEIT240318.
    [6]
    ZHANG Yukang and WANG Hanzi. Diverse embedding expansion network and low-light cross-modality benchmark for visible-infrared person re-identification[C]. Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, Canada, 2023: 2153–2162. doi: 10.1109/CVPR52729.2023.00214.
    [7]
    LI Jiarui, QIU Zhen, YANG Yilin, et al. Prototype-driven multi-feature generation for visible-infrared person re-identification[C]. Proceedings of the ICASSP 2025-2025 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Hyderabad, India, 2025: 1–5. doi: 10.1109/ICASSP49660.2025.10889917.
    [8]
    GU A and DAO T. Mamba: Linear-time sequence modeling with selective state spaces[C]. Proceedings of the 1th Conference on Language Modeling, Philadelphia, US, 2024.
    [9]
    LIU Yue, TIAN Yunjie, ZHAO Yuzhong, et al. VMamba: Visual state space model[C]. Proceedings of the 38th International Conference on Neural Information Processing Systems, Vancouver, Canada, 2024: 3273.
    [10]
    ZHU Lianghui, LIAO Bencheng, ZHANG Qian, et al. Vision mamba: Efficient visual representation learning with bidirectional state space model[C]. Proceedings of the 41st International Conference on Machine Learning, Vienna, Austria, 2024: 2584.
    [11]
    WANG Zeyu, LI Chen, XU Huiying, et al. Mamba YOLO: A simple baseline for object detection with state space model[C]. Proceedings of the 39th Annual AAAI Conference on Artificial Intelligence, Philadelphia, USA, 2025: 8205–8213. doi: 10.1609/aaai.v39i8.32885.
    [12]
    ZHOU Mingliang, LENG Hongyue, FANG Bin, et al. Low-light image enhancement via a frequency-based model with structure and texture decomposition[J]. ACM Transactions on Multimedia Computing, Communications, and Applications, 2023, 19(6): 187. doi: 10.1145/3590965.
    [13]
    QIN Zequn, ZHANG Pengyi, WU Fei, et al. FcaNet: Frequency channel attention networks[C]. Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, Canada, 2021: 763–772. doi: 10.1109/ICCV48922.2021.00082.
    [14]
    NAM J, SYAZWANY N S, KIM S J, et al. Modality-agnostic domain generalizable medical image segmentation by multi-frequency in multi-scale attention[C]. Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, USA, 2024: 11480–11491. doi: 10.1109/CVPR52733.2024.01091.
    [15]
    HE Kaiming, ZHANG Xiangyu, REN Shaoqing, et al. Deep residual learning for image recognition[C]. Proceedings of the 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, USA, 2016: 770–778. doi: 10.1109/CVPR.2016.90.
    [16]
    AHMED N, NATARAJAN T, and RAO K R. Discrete cosine transform[J]. IEEE Transactions on Computers, 1974, C-23(1): 90–93. doi: 10.1109/T-C.1974.223784.
    [17]
    王粉花, 赵波, 黄超, 等. 基于多尺度和注意力融合学习的行人重识别[J]. 电子与信息学报, 2020, 42(12): 3045–3052. doi: 10.11999/JEIT190998.

    WANG Fenhua, ZHAO Bo, HUANG Chao, et al. Person re-identification based on multi-scale network attention fusion[J]. Journal of Electronics & Information Technology, 2020, 42(12): 3045–3052. doi: 10.11999/JEIT190998.
    [18]
    庄建军, 庄宇辰. 一种结构化双注意力混合通道增强的跨模态行人重识别方法[J]. 电子与信息学报, 2024, 46(2): 518–526. doi: 10.11999/JEIT230614.

    ZHUANG Jianjun and ZHUANG Yuchen. A cross-modal person re-identification method based on hybrid channel augmentation with structured dual attention[J]. Journal of Electronics & Information Technology, 2024, 46(2): 518–526. doi: 10.11999/JEIT230614.
    [19]
    WU Ancong, ZHENG Weishi, YU Hongxing, et al. RGB-infrared cross-modality person re-identification[C]. Proceedings of the 2017 IEEE International Conference on Computer Vision (ICCV), Venice, Italy, 2017: 5390–5399. doi: 10.1109/ICCV.2017.575.
    [20]
    ZHENG Weishi, GONG Shaogang, and XIANG Tao. Person re-identification by probabilistic relative distance comparison[C]. Proceedings of the 2011 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Colorado Springs, USA, 2011: 649–656. doi: 10.1109/CVPR.2011.5995598.
    [21]
    PASZKE A, GROSS S, MASSA F, et al. PyTorch: An imperative style, high-performance deep learning library[C]. Proceedings of the 33rd International Conference on Neural Information Processing Systems, Vancouver, Canada, 2019: 721.
    [22]
    WU Ruiqi, JIAO Bingliang, WANG Wenxuan, et al. Enhancing visible-infrared person re-identification with modality- and instance-aware visual prompt learning[C]. Proceedings of the 2024 International Conference on Multimedia Retrieval, Phuket, Thailand, 2024: 579–588. doi: 10.1145/3652583.3658109.
    [23]
    REN Kaijie and ZHANG Lei. Implicit discriminative knowledge learning for visible-infrared person re-identification[C]. Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, USA, 2024: 393–402. doi: 10.1109/CVPR52733.2024.00045.
    [24]
    PAN Honghu, PEI Wenjie, LI Xin, et al. Unified conditional image generation for visible-infrared person re-identification[J]. IEEE Transactions on Information Forensics and Security, 2024, 19: 9026–9038. doi: 10.1109/TIFS.2024.3426335.
    [25]
    YU Xiaoyan, DONG Neng, ZHU Liehuang, et al. CLIP-driven semantic discovery network for visible-infrared person re-identification[J]. IEEE Transactions on Multimedia, 2025, 27: 4137–4150. doi: 10.1109/TMM.2025.3535353.
    [26]
    ZHANG Hongde and MA Bingpeng. Visible-infrared person re-identification via mutual reinforcement of prompts and image encoders[C]. Proceedings of the 2025 International Conference on Multimedia Retrieval, Chicago, USA, 2025: 2118–2122. doi: 10.1145/3731715.3733496.
    [27]
    QI Mengzan, CHAN Sixian, HANG Chen, et al. Auxiliary representation guided network for visible-infrared person re-identification[J]. IEEE Transactions on Multimedia, 2025, 27: 340–355. doi: 10.1109/TMM.2024.3521773.
    [28]
    ZHANG Yukang, YAN Yan, LU Yang, et al. Adaptive middle modality alignment learning for visible-infrared person re-identification[J]. International Journal of Computer Vision, 2025, 133(4): 2176–2196. doi: 10.1007/s11263-024-02276-4.
    [29]
    VAN DER MAATEN L and HINTON G. Visualizing data using t-SNE[J]. Journal of Machine Learning Research, 2008, 9: 2579–2605.
    [30]
    崔学英, 王宇航, 刘斌, 等. Wave-MambaCT: 基于小波Mamba的低剂量CT伪影抑制方法[J]. 电子与信息学报, 2026, 48(3): 982–993. doi: 10.11999/JEIT250489.

    CUI Xueying, WANG Yuhang, LIU Bin, et al. Wave-MambaCT: Low-dose CT artifact suppression method based on wavelet Mamba[J]. Journal of Electronics & Information Technology, 2026, 48(3): 982–993. doi: 10.11999/JEIT250489.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(6)  / Tables(6)

    Article Metrics

    Article views (69) PDF downloads(7) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return