Advanced Search
Turn off MathJax
Article Contents
SUN Jin, XU Tianyile, ZHAO Haitao. Dynamic Visual SLAM Integrating Depth-Consistency Segmentation and Progressive Distillation Network[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260266
Citation: SUN Jin, XU Tianyile, ZHAO Haitao. Dynamic Visual SLAM Integrating Depth-Consistency Segmentation and Progressive Distillation Network[J]. Journal of Electronics & Information Technology. doi: 10.11999/JEIT260266

Dynamic Visual SLAM Integrating Depth-Consistency Segmentation and Progressive Distillation Network

doi: 10.11999/JEIT260266 cstr: 32379.14.JEIT260266
Funds:  National Natural Science Foundation of China under Grant 62203231, the Open Fund of State Key Laboratory of Ocean Engineering under Grant GKZD010084, the Postgraduate Research & Practice Innovation Program of Jiangsu Province under Grant SJCX25_0374.
  • Received Date: 2026-03-11
  • Accepted Date: 2026-09-28
  • Rev Recd Date: 2026-09-28
  • Available Online: 2026-10-10
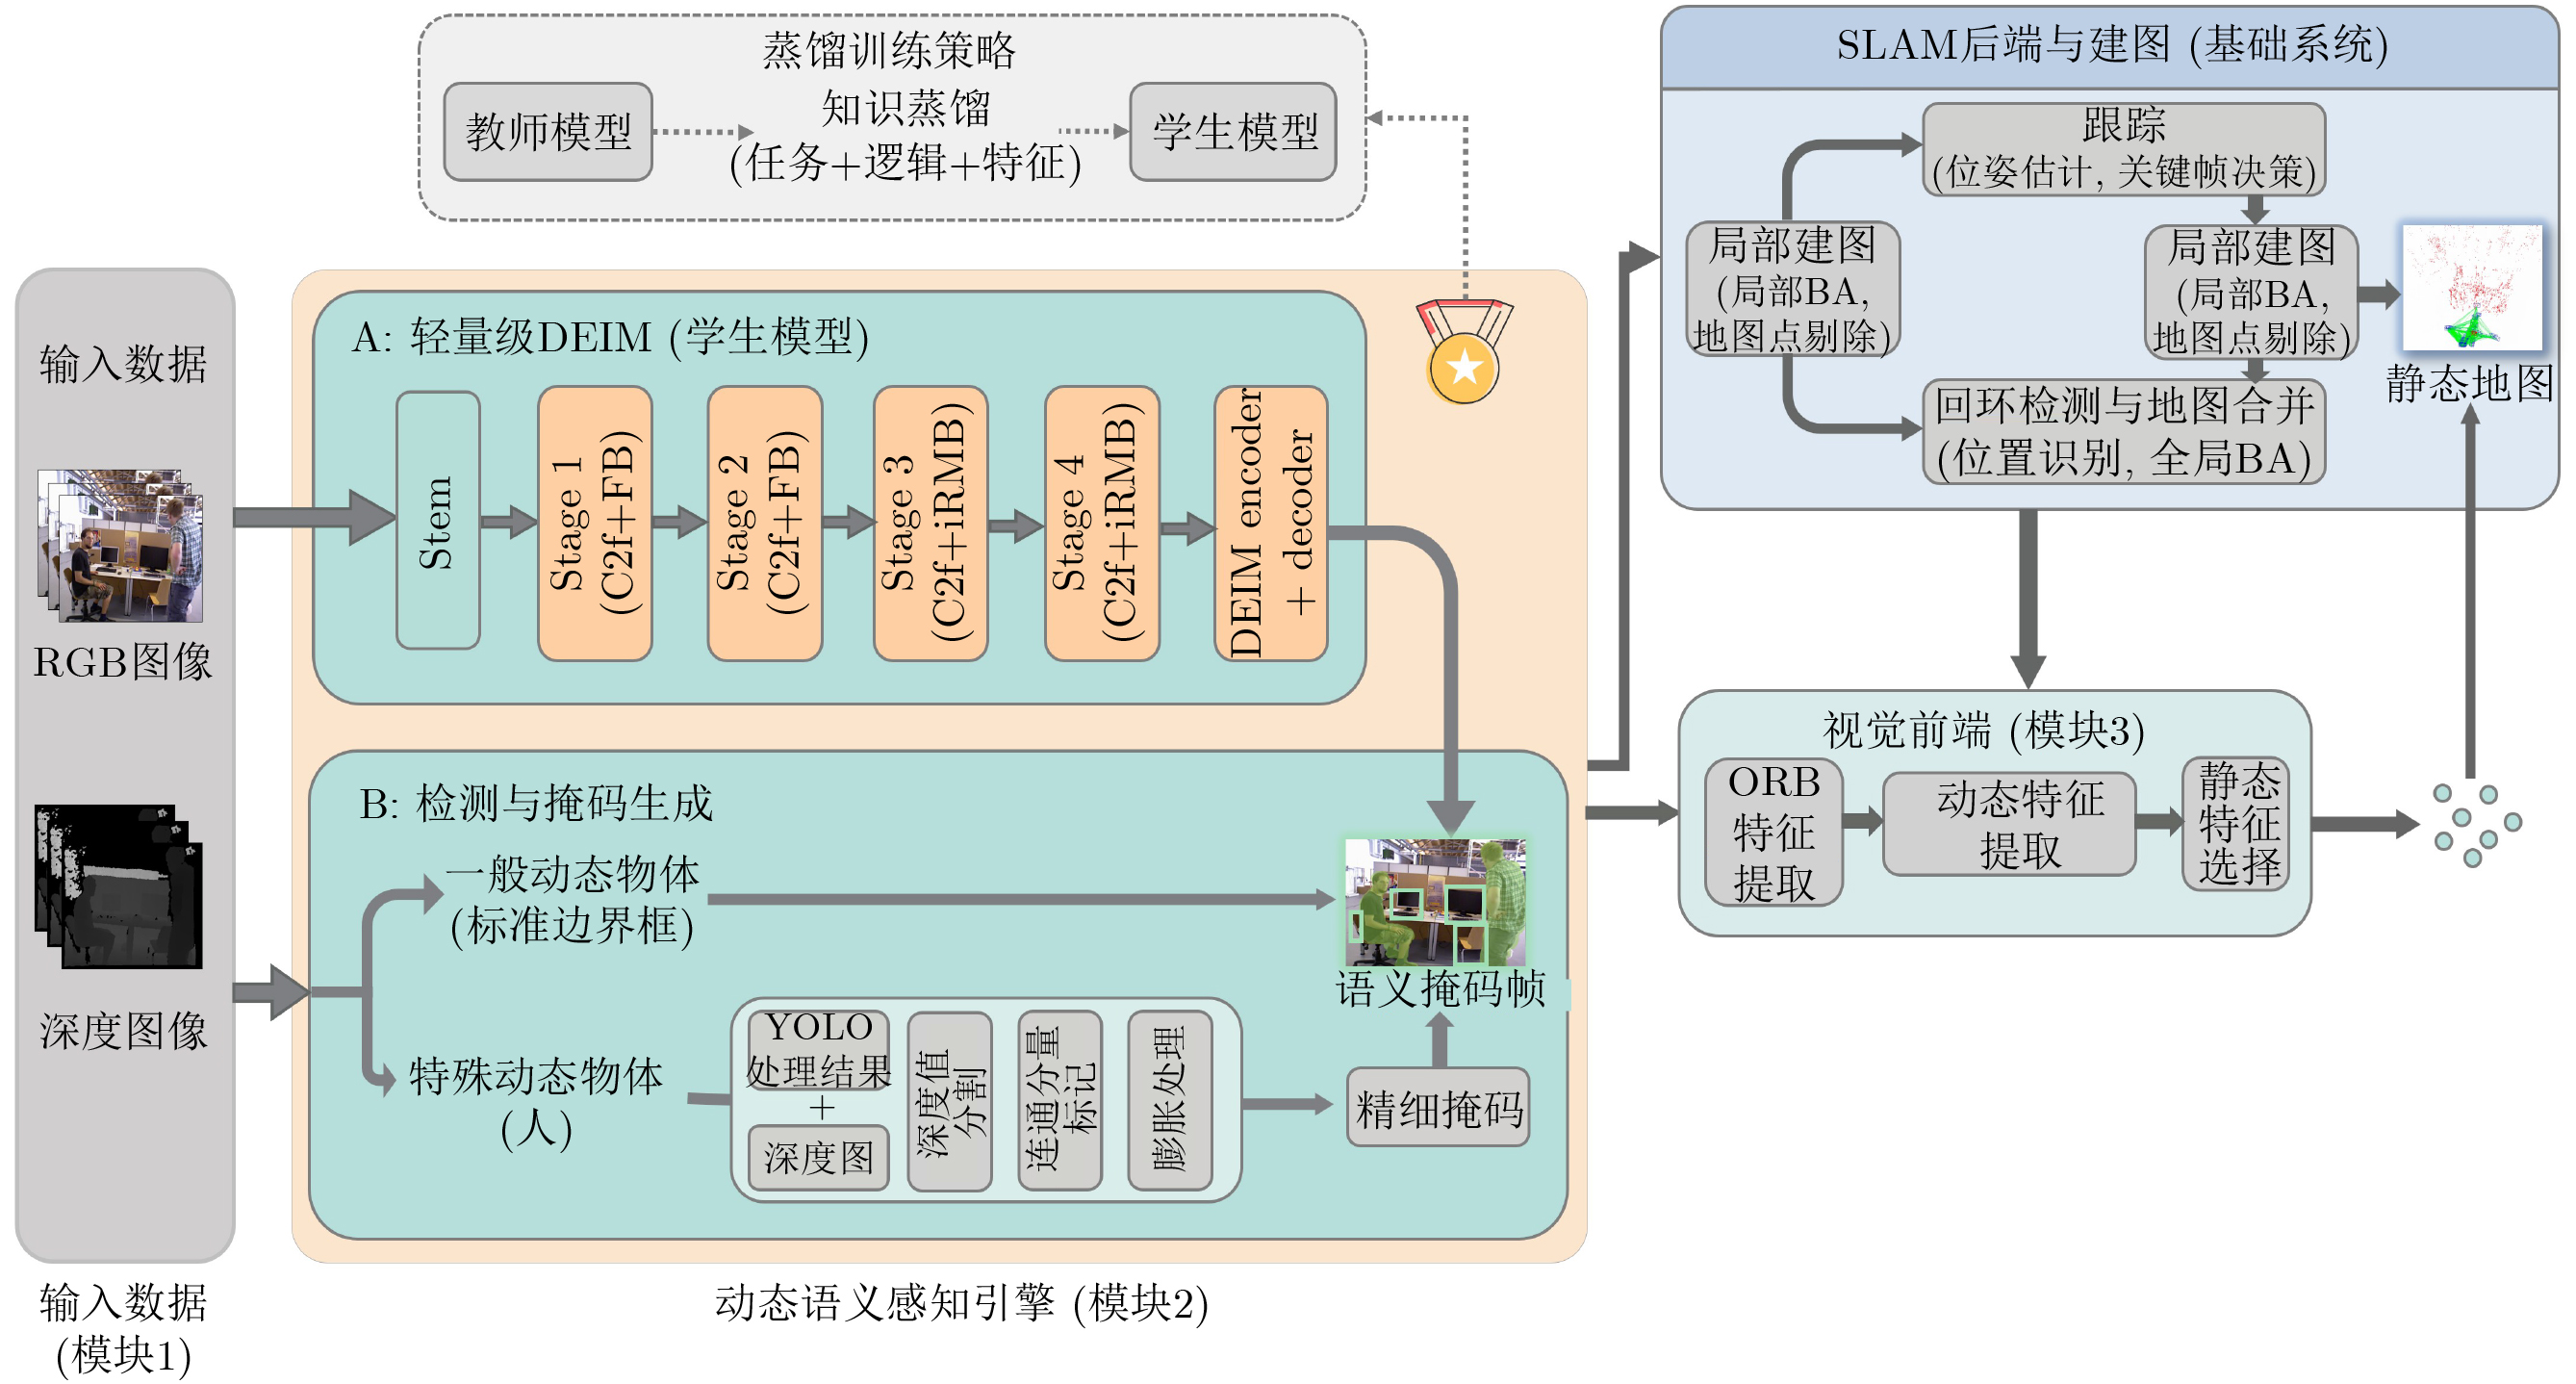
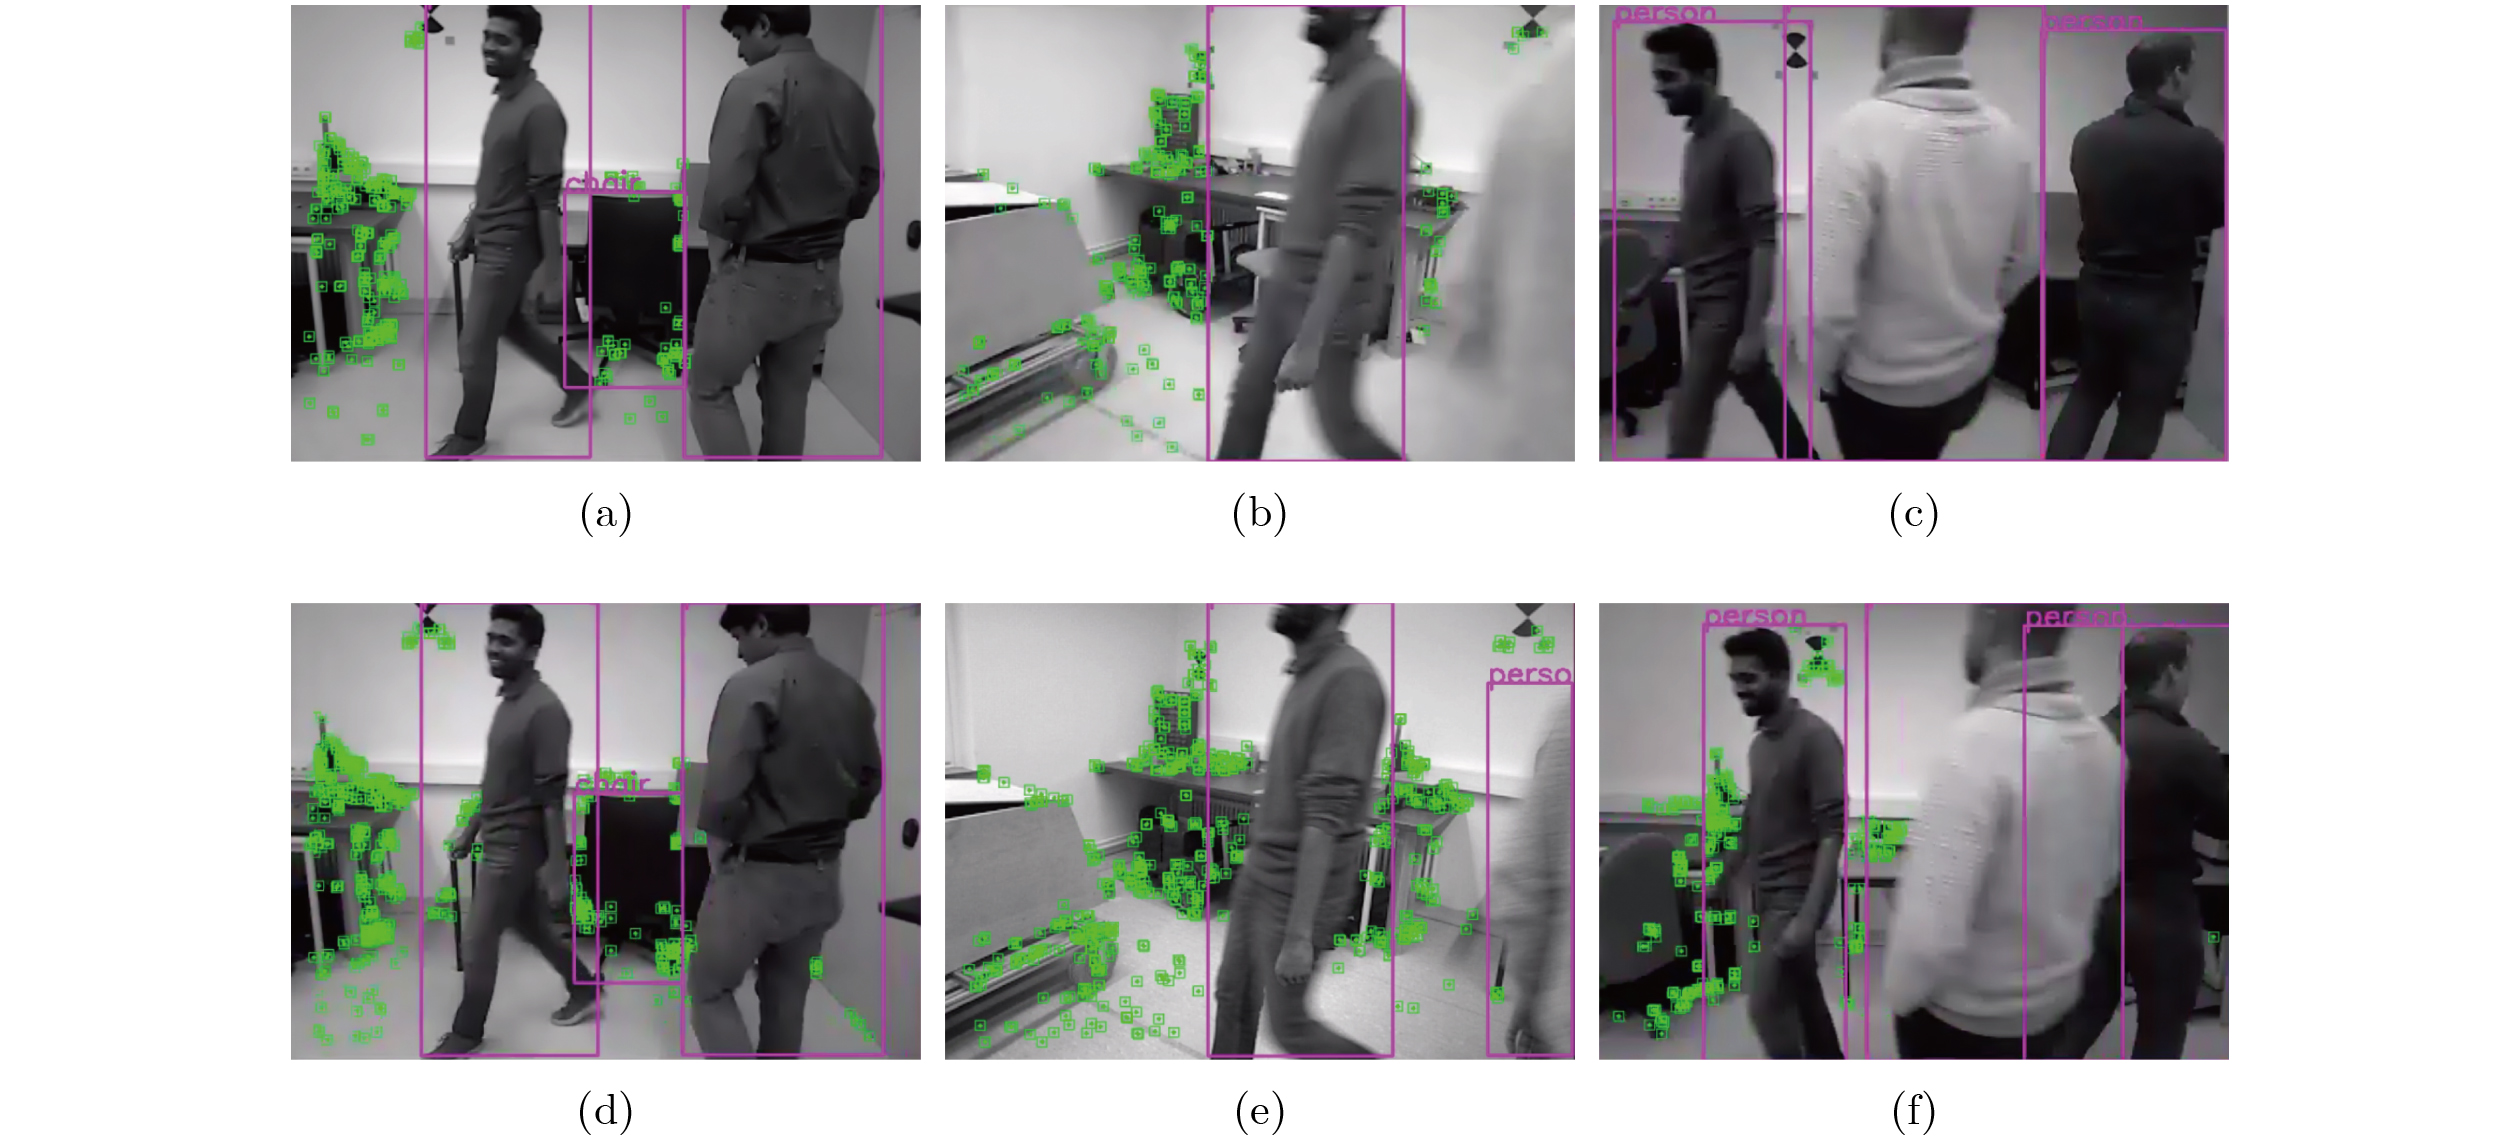
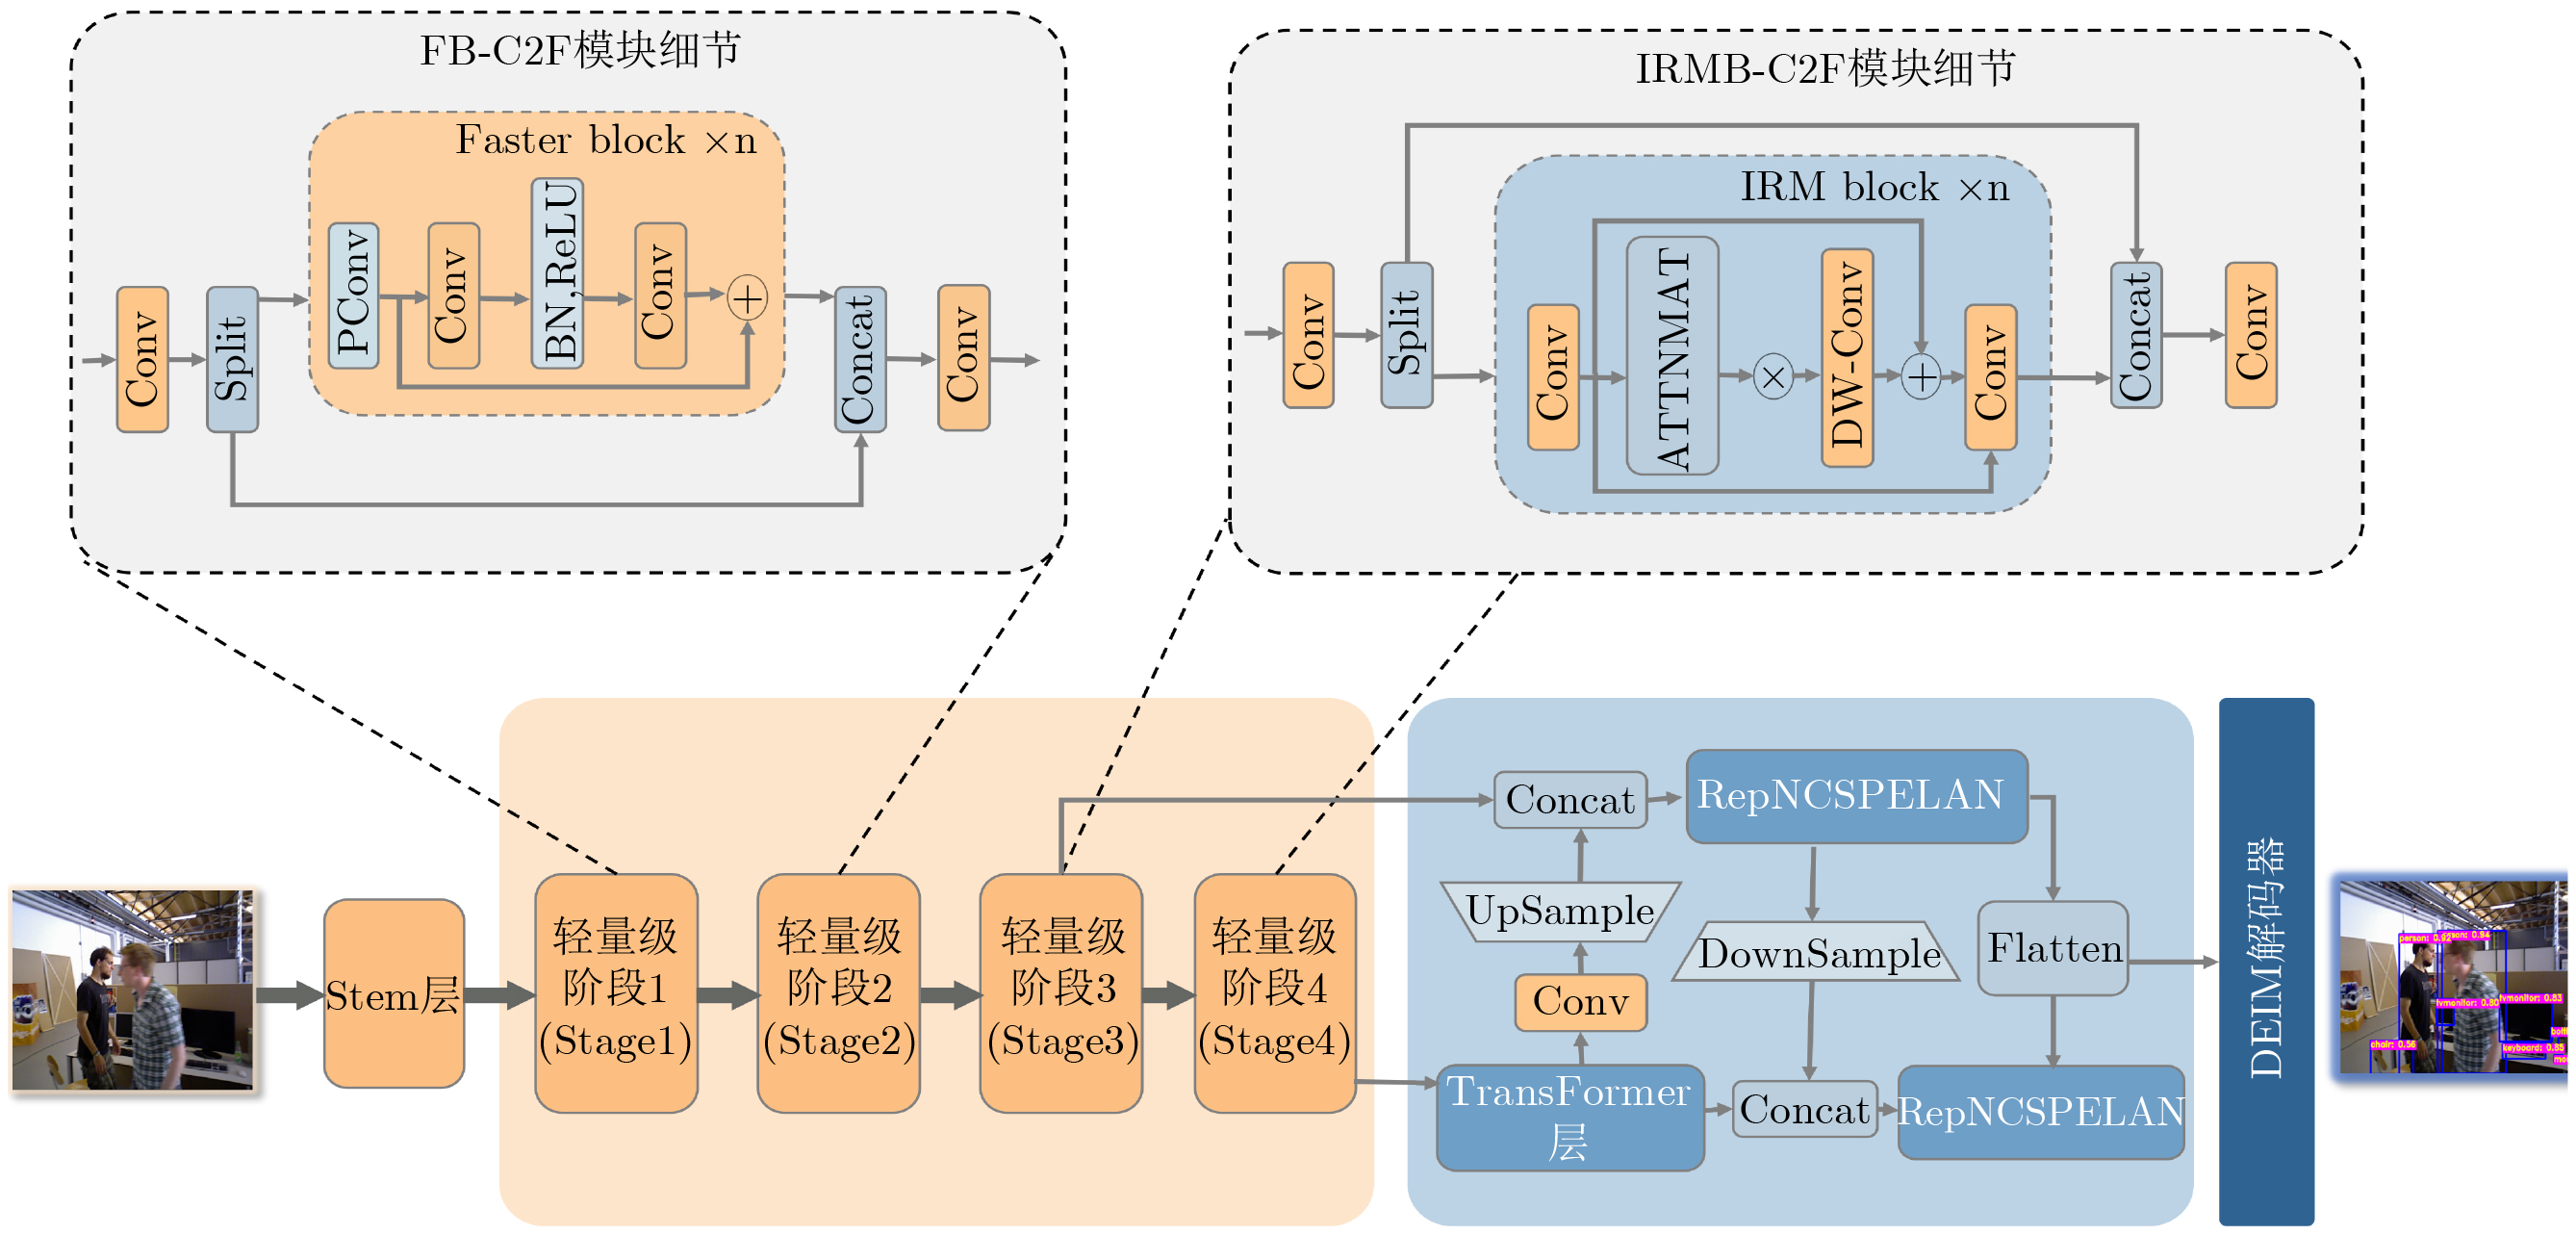
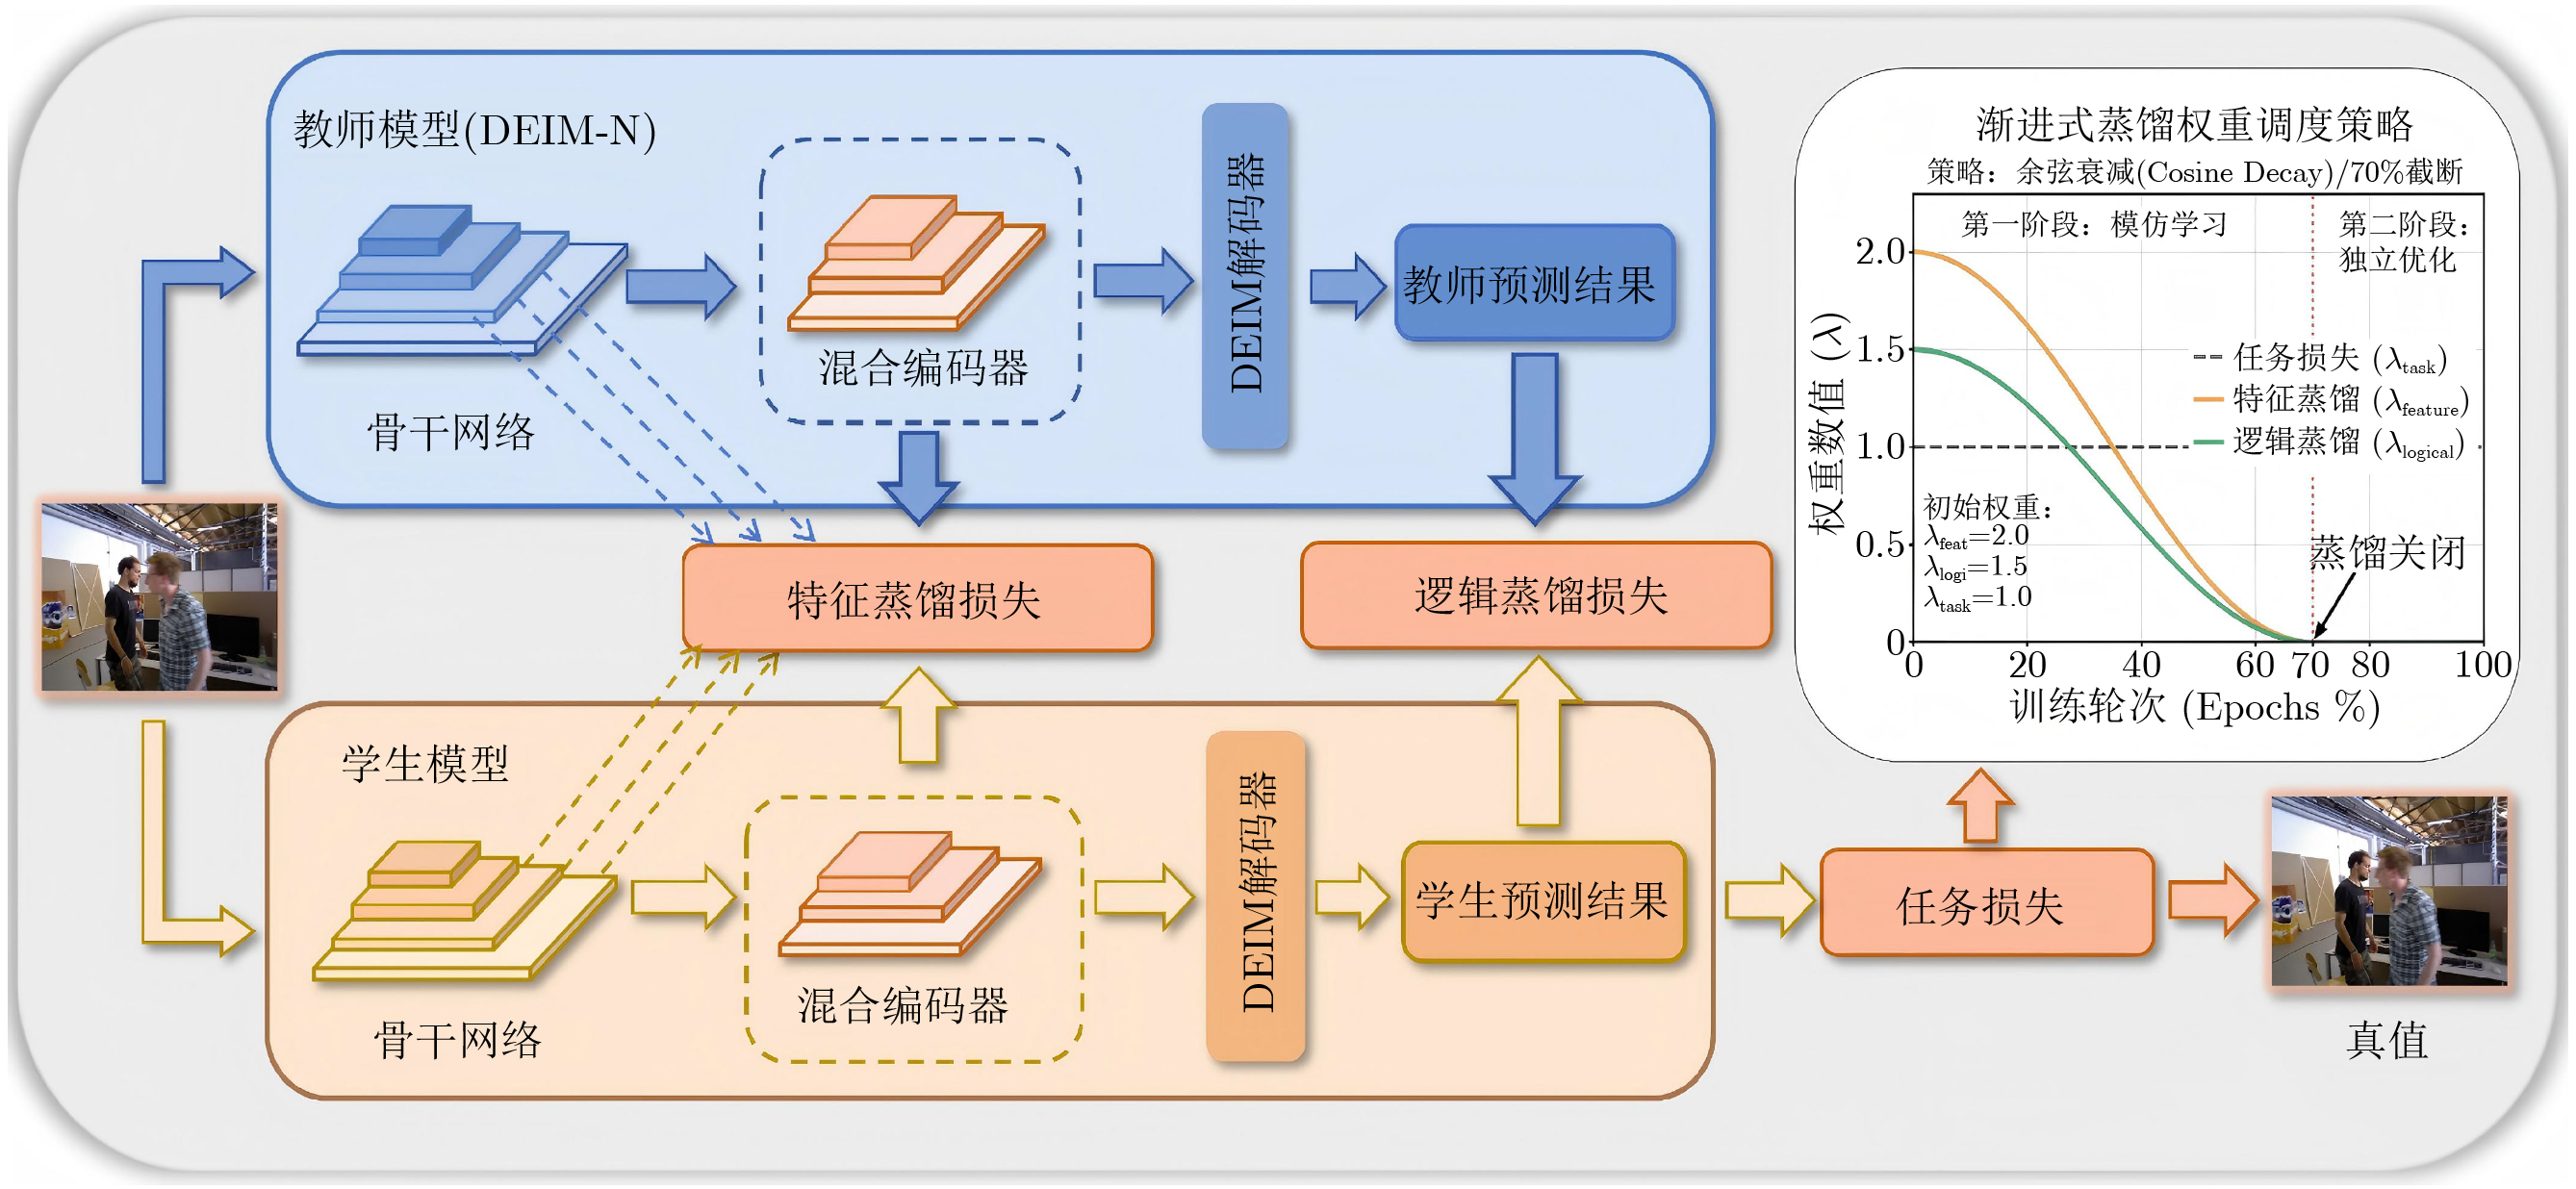
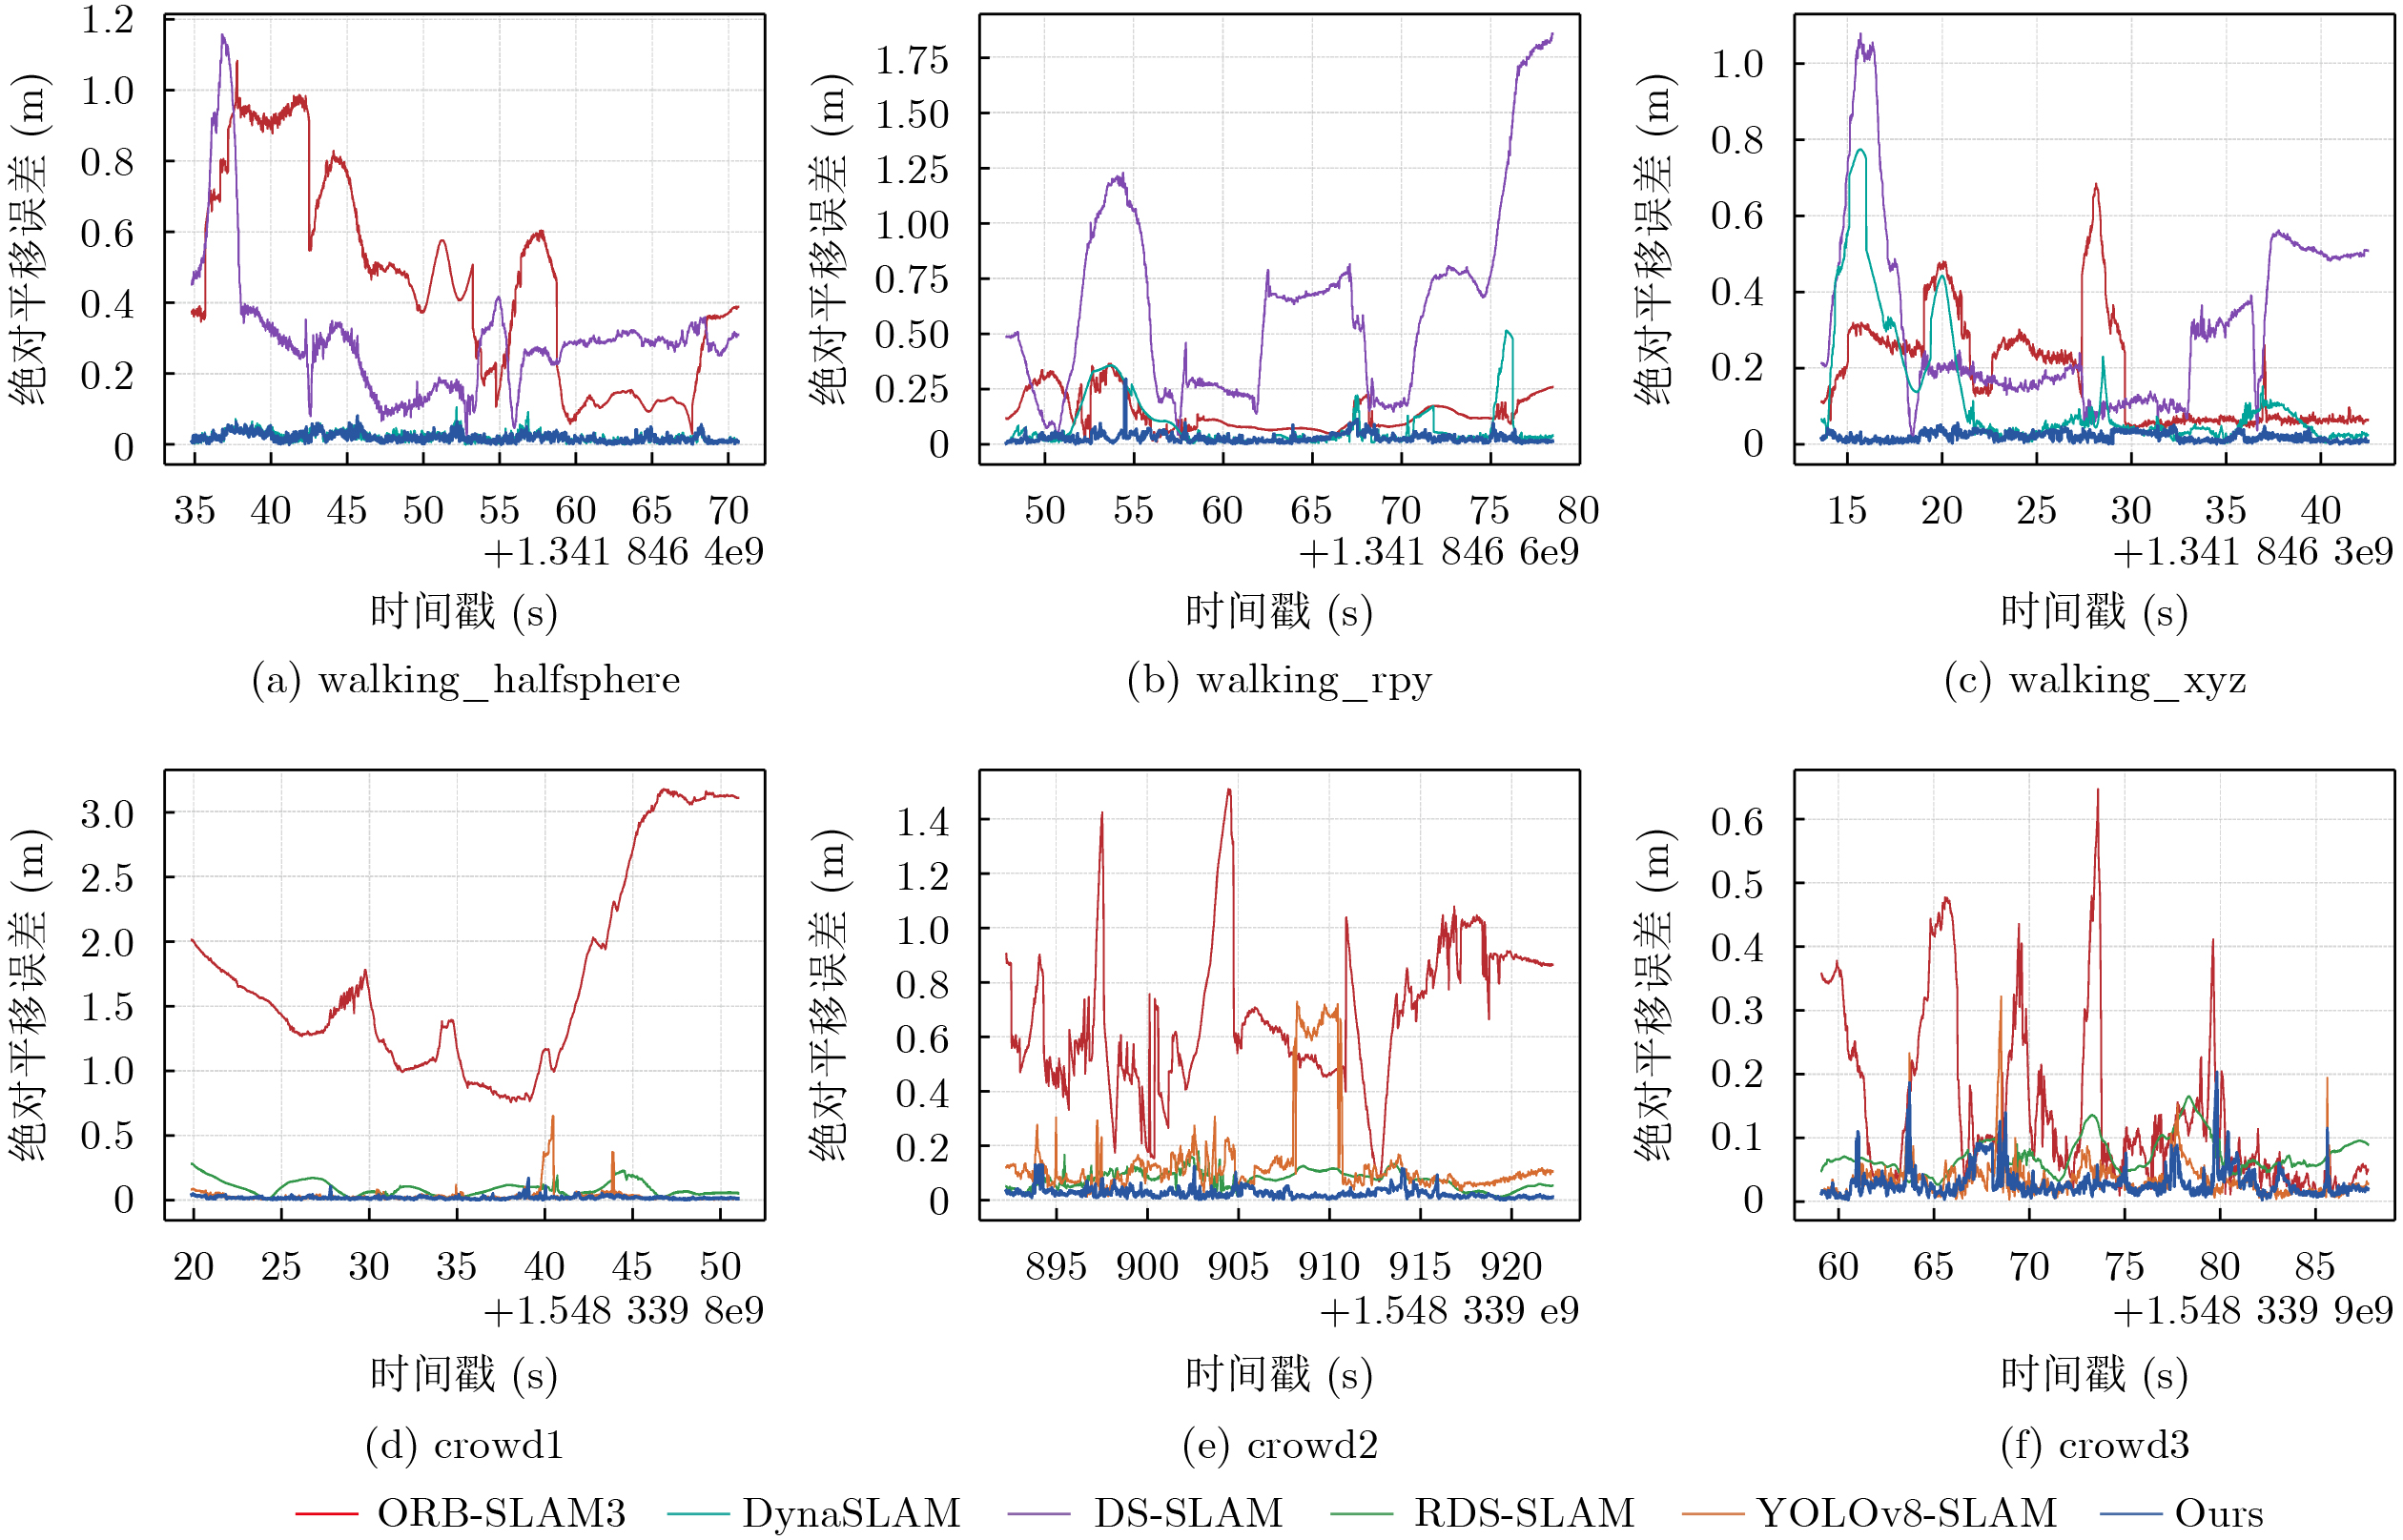
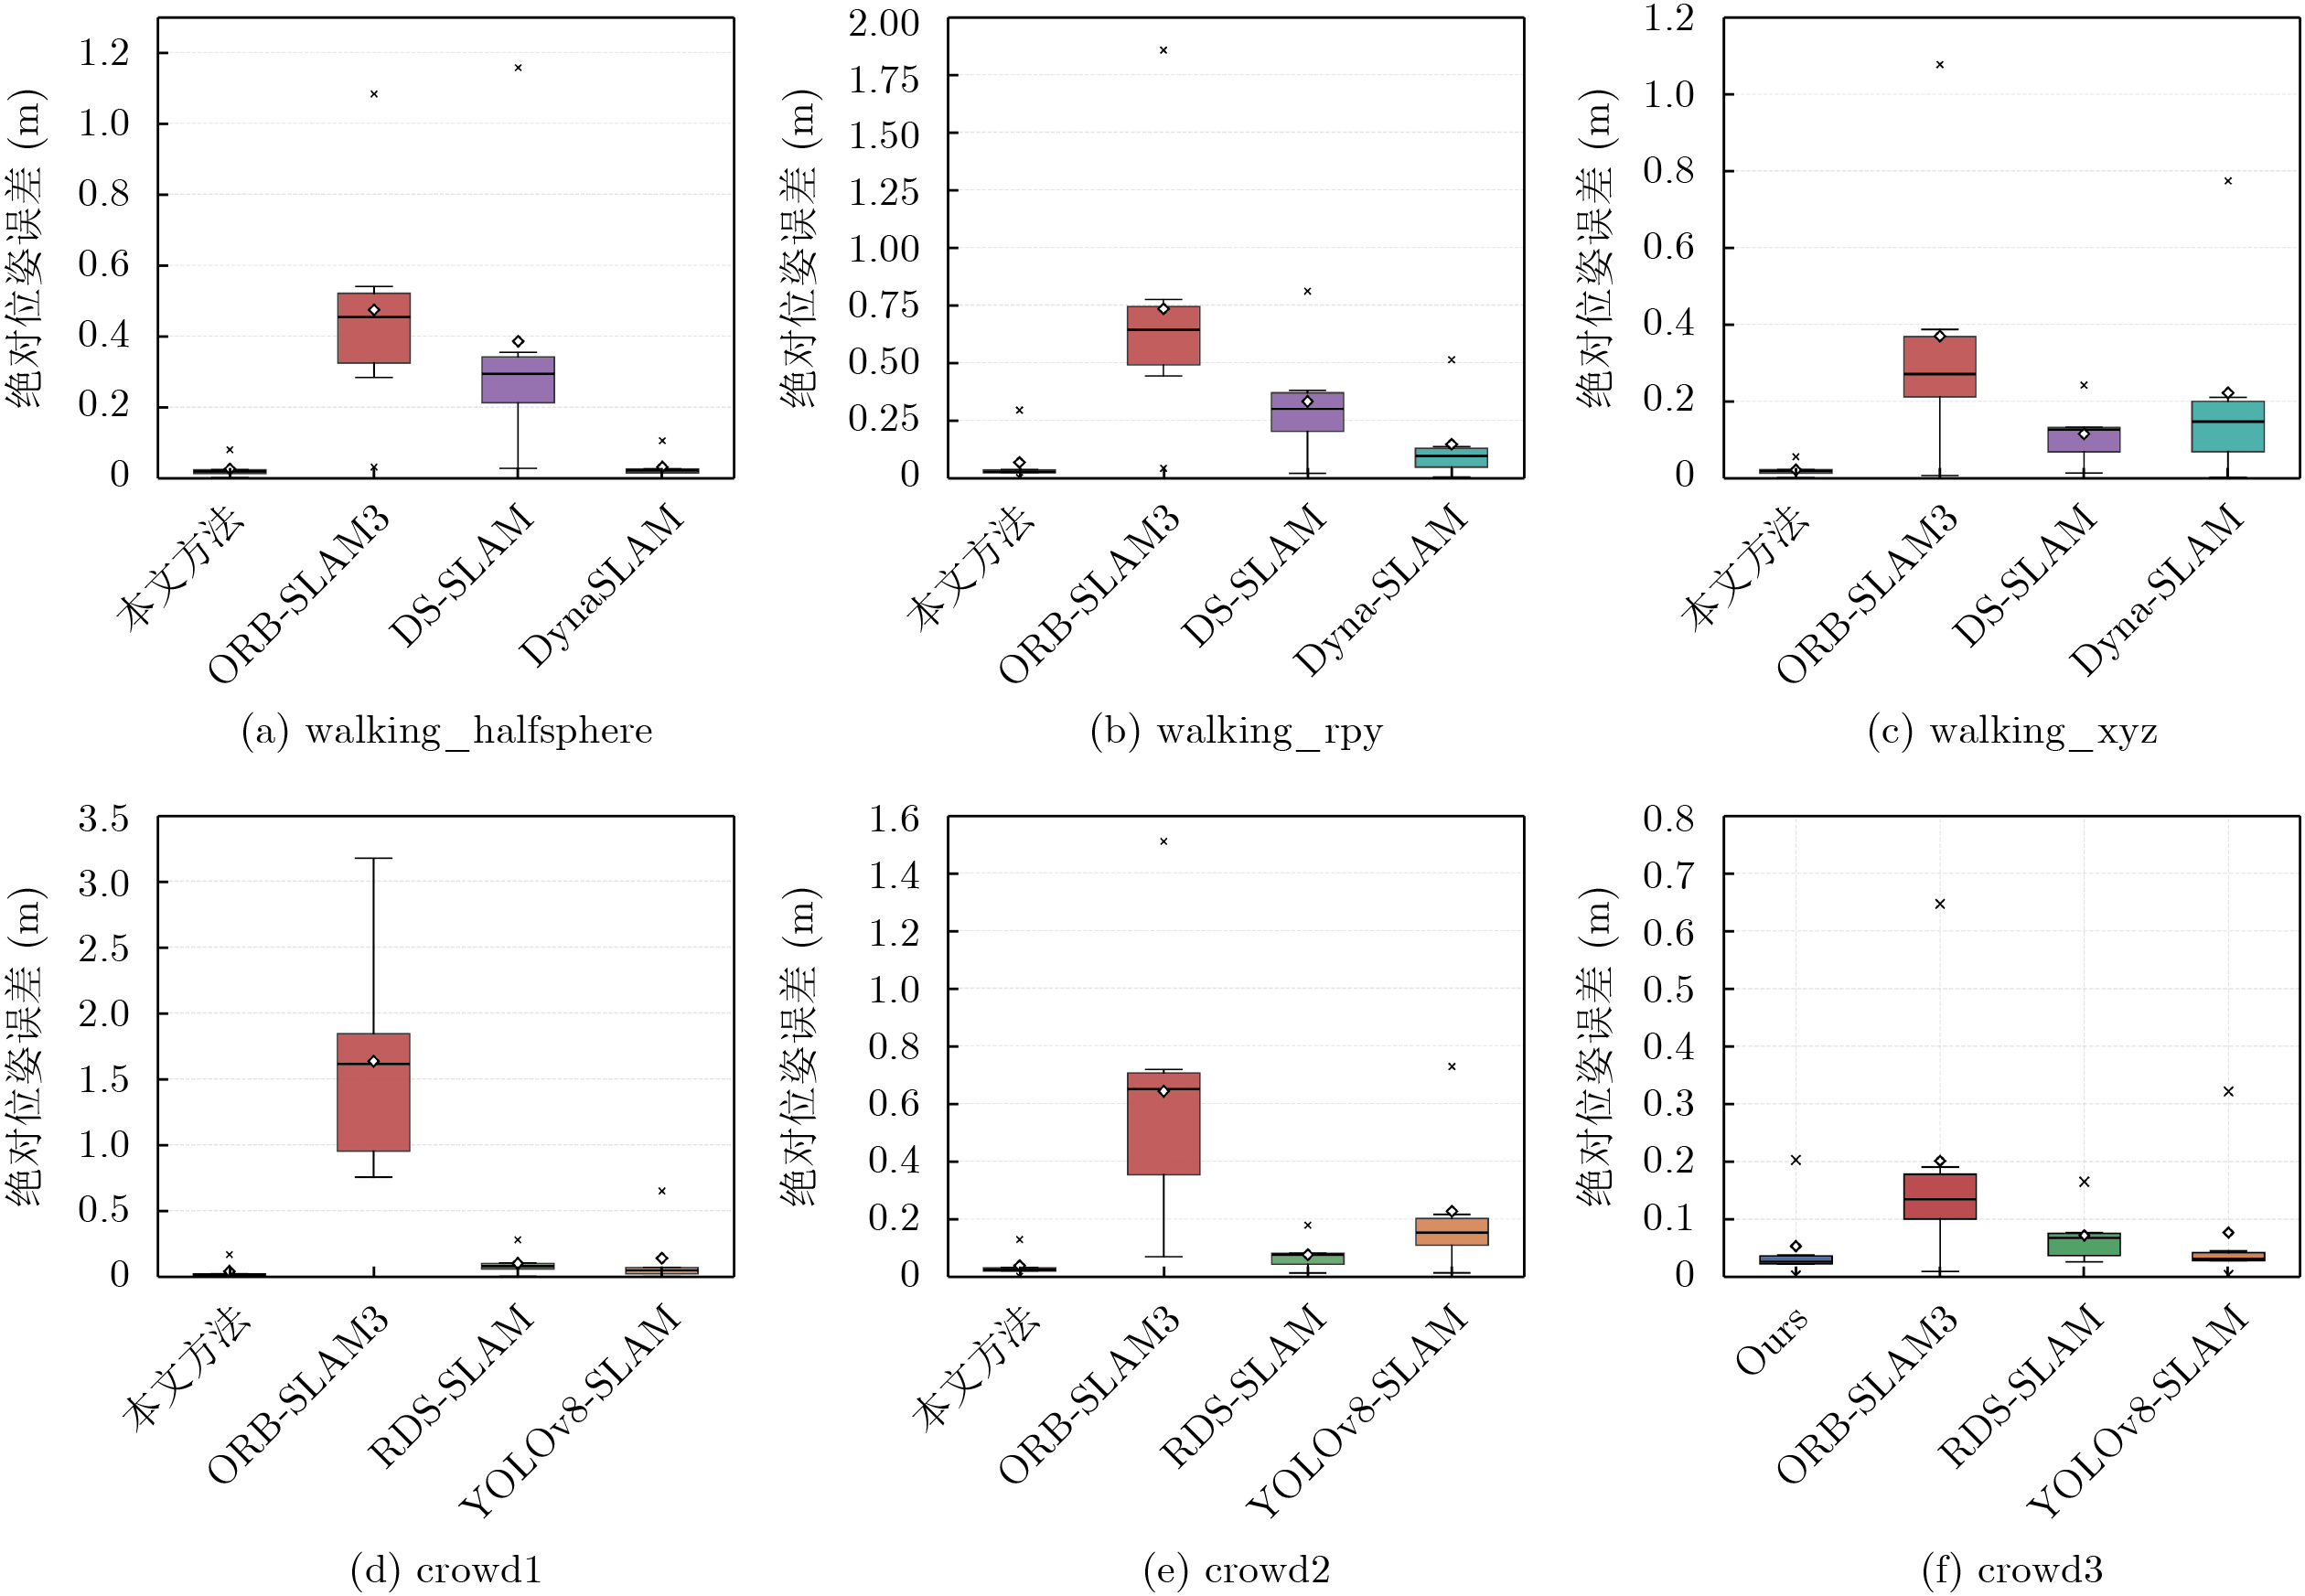
  •   Objective  Visual Simultaneous Localization and Mapping (SLAM) is a fundamental technology for autonomous navigation and environmental perception in Global Navigation Satellite System (GNSS)-denied environments. However, conventional visual SLAM systems generally rely on a static-scene assumption. In dynamic environments containing pedestrians, vehicles, and other moving objects, dynamic feature mismatches may violate geometric constraints and introduce unstable observations into pose estimation, resulting in trajectory drift or tracking degradation. Existing dynamic SLAM methods commonly incorporate semantic priors to suppress such interference. Semantic segmentation-based methods can provide fine-grained pixel-level dynamic regions, but usually require relatively high computational cost. In contrast, object detection-based methods provide higher inference efficiency, but their rectangular detection boxes inevitably contain static background regions, which may lead to the erroneous removal of valid static features and cause an over-masking problem. This issue becomes more pronounced in texture-poor or crowded scenes where sufficient static features are important for maintaining stable geometric constraints. To alleviate the trade-off between dynamic-feature filtering accuracy and computational efficiency, this paper proposes Depth-Consistency and Progressive-Distillation SLAM (DCPD-SLAM), a lightweight dynamic visual SLAM system for real-time state estimation under moderate computational resources.  Methods  DCPD-SLAM adopts a parallel dual-thread architecture comprising semantic perception and visual SLAM tracking. Semantic inference and feature extraction run concurrently, with frame-level synchronization before dynamic-feature filtering to align semantic results with the current Red-Green-Blue-Depth (RGB-D) frame. First, a depth-aware masking strategy refines coarse detection boxes. For selected non-rigid dynamic targets, such as pedestrians, valid depth pixels within the Region of Interest (ROI) are used to estimate a robust reference depth. The reference depth combines the median and the lower 33rd percentile of valid depth measurements to reduce the influence of background pixels and isolated depth noise. An adaptive depth-consistency threshold is then used to generate an initial foreground mask. When the valid-depth ratio is insufficient, the original detection box is retained as a fallback to maintain filtering reliability. Connected Component Analysis (CCA) and morphological dilation suppress isolated noise and compensate for boundary leakage, yielding a compact pixel-level pseudo-mask. Other predefined dynamic categories retain detection-box-based filtering to avoid additional mask-generation overhead.Second, a lightweight detector, Light-DEIM, reduces semantic perception costs. Partial Convolution (PConv) is incorporated into shallow C2f-FasterBlock stages to reduce spatial redundancy, while deeper C2f-Inverted Residual Mobile Block (iRMB) modules with window attention preserve semantic representations. Balanced width scaling further reduces model complexity while retaining sufficient high-level semantic capacity. Finally, progressive knowledge distillation compensates for representation loss caused by model lightweighting. Masked Generative Distillation (MGD) aligns intermediate features, while DETRDistill-based logits distillation aligns teacher–student predictions. During the first 70% of training epochs, Light-DEIM is trained with ground-truth supervision and feature and output distillation from a frozen DEIM-N teacher. For the remaining epochs, the distillation branches are disabled, and the student is optimized solely with ground-truth labels.  Results and Discussions  Experiments are conducted on the TUM RGB-D and Bonn RGB-D dynamic datasets. For the detection network, Light-DEIM reduces the parameter count from 4.0 M to 3.0 M and the computational complexity from 7.1 Giga Floating-point Operations (GFLOPs) to 5.6 GFLOPs. Without knowledge distillation, the lightweight model achieves an $ \text{mAP}_{50-95}^{\text{val}} $ of 36.2%. After progressive knowledge distillation, the $ \text{mAP}_{50-95}^{\text{val}} $increases to 41.9%, approaching the 42.5% performance of the DEIM-N teacher model while maintaining a validation throughput of 323 Frames Per Second (FPS) (Table 1). Ablation experiments further show that PConv mainly contributes to computational efficiency, whereas iRMB and Window Attention improve semantic representation. The combination of feature-level and output-level distillation provides better accuracy recovery than either distillation term alone (Table 2, Table 3).For SLAM evaluation, DCPD-SLAM achieves an Absolute Trajectory Error (ATE) of 0.019 $ \pm $0.002 $ 0.019\pm 0.002 $ m on the highly dynamic walking_xyz sequence, compared with 0.387 m for ORB-SLAM3 (Table 4). The trajectory-error curves and error distributions further indicate relatively stable localization performance in highly dynamic scenes (Fig. 5, Fig. 6). In four representative dynamic sequences, the proposed depth-aware masking strategy achieves an average dynamic-point rejection rate of 95.4% while limiting the static-point erroneous rejection rate to 12.4% (Table 6), indicating that it can reduce unnecessary removal of static background features while maintaining effective dynamic-feature filtering. At the complete-system level, DCPD-SLAM achieves average processing rates of 24.71 FPS and 27.11 FPS on the TUM RGB-D and Bonn RGB-D datasets, respectively (Table 7), demonstrating real-time processing capability on the moderate-compute Graphics Processing Unit (GPU) platform.  Conclusions  DCPD-SLAM balances localization accuracy and computational efficiency in dynamic RGB-D environments. Depth-aware masking mitigates over-masking from detection-box filtering, preserving static background features. Light-DEIM and progressive knowledge distillation reduce semantic perception overhead while retaining detection capability for dynamic-feature filtering. Experiments demonstrate real-time processing and stable localization on a moderate-compute GPU platform. However, pseudo-mask quality depends on depth measurements, with potential degradation under severe depth noise, strong illumination changes, reflective or transparent surfaces, distant targets, and severe occlusions. Future work will explore Light Detection and Ranging (LiDAR)-visual fusion to improve adaptability and measurement stability in complex, large-scale environments.
  • loading
  • [1]
    陈丹, 陈浩, 王子晨, 等. 多层ICP闭环检测下的误差状态卡尔曼滤波多模态融合SLAM[J]. 电子与信息学报, 2025, 47(5): 1517–1528. doi: 10.11999/JEIT240980.

    CHEN Dan, CHEN Hao, WANG Zichen, et al. Error state Kalman filter multimodal fusion SLAM based on MICP closed-loop detection[J]. Journal of Electronics & Information Technology, 2025, 47(5): 1517–1528. doi: 10.11999/JEIT240980.
    [2]
    CAMPOS C, ELVIRA R, RODRÍGUEZ J J G, et al. ORB-SLAM3: An accurate open-source library for visual, visual-inertial, and multimap SLAM[J]. IEEE Transactions on Robotics, 2021, 37(6): 1874–1890. doi: 10.1109/TRO.2021.3075644.
    [3]
    罗元, 沈吉祥, 李方宇. 动态环境下基于深度学习的视觉SLAM研究综述[J]. 半导体光电, 2024, 45(1): 1–10. doi: 10.16818/j.issn1001-5868.2023112202.

    LUO Yuan, SHEN Jixiang, and LI Fangyu. Review of visual SLAM research based on deep learning in dynamic environments[J]. Semiconductor Optoelectronics, 2024, 45(1): 1–10. doi: 10.16818/j.issn1001-5868.2023112202.
    [4]
    BESCOS B, FÁCIL J M, CIVERA J, et al. DynaSLAM: Tracking, mapping, and inpainting in dynamic scenes[J]. IEEE Robotics and Automation Letters, 2018, 3(4): 4076–4083. doi: 10.1109/LRA.2018.2860039.
    [5]
    YU Chao, LIU Zuxin, LIU Xinjun, et al. DS-SLAM: A semantic visual SLAM towards dynamic environments[C]. 2018 IEEE/RSJ International Conference on Intelligent Robots and Systems, Madrid, Spain, 2018: 1168–1174. doi: 10.1109/IROS.2018.8593691.
    [6]
    梅天灿, 秦宇晟, 杨宏, 等. 动态场景下基于视觉同时定位与地图构建技术的多层次语义地图构建方法[J]. 电子与信息学报, 2023, 45(5): 1737–1746. doi: 10.11999/JEIT220153.

    MEI Tiancan, QIN Yusheng, YANG Hong, et al. Multilevel semantic maps based on visual simultaneous localization and mapping in dynamic scenarios[J]. Journal of Electronics & Information Technology, 2023, 45(5): 1737–1746. doi: 10.11999/JEIT220153.
    [7]
    ZHANG Yuhao, BUJANCA M, and LUJÁN M. NGD-SLAM: Towards real-time dynamic SLAM without GPU[C]. 2025 IEEE/RSJ International Conference on Intelligent Robots and Systems, Hangzhou, China, 2025: 3467–3473. doi: 10.1109/IROS60139.2025.11246202.
    [8]
    ZHONG Fangwei, WANG Sheng, ZHANG Ziqi, et al. Detect-SLAM: Making object detection and SLAM mutually beneficial[C]. 2018 IEEE Winter Conference on Applications of Computer Vision, Lake Tahoe, USA, 2018: 1001–1010. doi: 10.1109/WACV.2018.00115.
    [9]
    WU Wenxin, GUO Liang, GAO Hongli, et al. YOLO-SLAM: A semantic SLAM system towards dynamic environment with geometric constraint[J]. Neural Computing and Applications, 2022, 34(8): 6011–6026. doi: 10.1007/s00521-021-06764-3.
    [10]
    LI Feng, LIU Yuanyuan, ZHANG Kelong, et al. DDETR-SLAM: A transformer-based approach to pose optimisation in dynamic environments[J]. International Journal of Robotics and Automation, 2024, 39(5): 407–421. doi: 10.2316/J.2024.206-1063. (查阅网上资料,未找到本条文献年卷期信息,请确认).
    [11]
    余浩扬, 李艳生, 肖凌励, 等. 面向动态环境的巡检机器人轻量级语义视觉SLAM框架[J]. 电子与信息学报, 2025, 47(10): 3979–3992. doi: 10.11999/JEIT250301.

    YU Haoyang, LI Yansheng, XIAO Lingli, et al. A lightweight semantic visual simultaneous localization and mapping framework for inspection robots in dynamic environments[J]. Journal of Electronics & Information Technology, 2025, 47(10): 3979–3992. doi: 10.11999/JEIT250301.
    [12]
    LIU Yubao and MIURA J. RDS-SLAM: Real-time dynamic SLAM using semantic segmentation methods[J]. IEEE Access, 2021, 9: 23772–23785. doi: 10.1109/ACCESS.2021.3050617.
    [13]
    LIU Yang, GUO Chi, LUO Yarong, et al. DynaMeshSLAM: A mesh-based dynamic visual SLAMMOT method[J]. IEEE Robotics and Automation Letters, 2024, 9(6): 5791–5798. doi: 10.1109/LRA.2024.3396103.
    [14]
    HUANG Shihua, LU Zhichao, CUN Xiaodong, et al. DEIM: DETR with improved matching for fast convergence[C]. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, USA, 2025: 15162–15171.
    [15]
    CHEN Jierun, KAO S H, HE Hao, et al. Run, don’t walk: Chasing higher FLOPS for faster neural networks[C]. 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, Canada, 2023: 12021–12031. doi: 10.1109/CVPR52729.2023.01157.
    [16]
    ZHANG Jiangning, LI Xiangtai, LI Jian, et al. Rethinking mobile block for efficient attention-based models[C]. Proceedings of the 2023 IEEE/CVF International Conference on Computer Vision, Paris, France, 2023: 1389–1400. doi: 10.1109/ICCV51070.2023.00134.
    [17]
    LIU Ze, LIN Yutong, CAO Yue, et al. Swin transformer: Hierarchical vision transformer using shifted windows[C]. Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision, Montreal, Canada, 2021: 9992–10002. doi: 10.1109/ICCV48922.2021.00986.
    [18]
    TAN Mingxing and LE Q V. EfficientNet: Rethinking model scaling for convolutional neural networks[C]. Proceedings of the 36th International Conference on Machine Learning, Long Beach, USA, 2019: 6105–6114.
    [19]
    陈雷, 杨吉斌, 曹铁勇, 等. 一种基于Transformer特征金字塔的自蒸馏目标分割方法[J]. 电子与信息学报, 2025, 47(2): 551–560. doi: 10.11999/JEIT240735.

    CHEN Lei, YANG Jibin, CAO Tieyong, et al. A self-distillation object segmentation method based on transformer feature pyramid[J]. Journal of Electronics & Information Technology, 2025, 47(2): 551–560. doi: 10.11999/JEIT240735.
    [20]
    YANG Zhendong, LI Zhe, SHAO Mingqi, et al. Masked generative distillation[C]. Proceedings of the 17th European Conference on Computer Vision, Tel Aviv, Israel, 2022: 53–69. doi: 10.1007/978-3-031-20083-0_4.
    [21]
    CHANG Jiahao, WANG Shuo, XU Haiming, et al. DETRDistill: A universal knowledge distillation framework for DETR-families[C]. Proceedings of the 2023 IEEE/CVF International Conference on Computer Vision, Paris, France, 2023: 6875–6885. doi: 10.1109/ICCV51070.2023.00635.
    [22]
    STURM J, ENGELHARD N, ENDRES F, et al. A benchmark for the evaluation of RGB-D SLAM systems[C]. 2012 IEEE/RSJ International Conference on Intelligent Robots and Systems, Vilamoura-Algarve, Portugal, 2012: 573–580. doi: 10.1109/IROS.2012.6385773.
    [23]
    PALAZZOLO E, BEHLEY J, LOTTES P, et al. ReFusion: 3D reconstruction in dynamic environments for RGB-D cameras exploiting residuals[C]. 2019 IEEE/RSJ International Conference on Intelligent Robots and Systems, Macau, China, 2019: 7855–7862. doi: 10.1109/IROS40897.2019.8967590.
    [24]
    WANG Ao, CHEN Hui, LIU Lihao, et al. YOLOv10: Real-time end-to-end object detection[C]. Proceedings of the 38th International Conference on Neural Information Processing Systems, Vancouver, Canada, 2024: 3429.
    [25]
    SAPKOTA R, FLORES-CALERO M, QURESHI R, et al. YOLO advances to its genesis: A decadal and comprehensive review of the You Only Look Once (YOLO) series[J]. Artificial Intelligence Review, 2025, 58(9): 274. doi: 10.1007/s10462-025-11253-3.
    [26]
    LI Yanke, SHEN Huabo, FU Yaping, et al. A method of dense point cloud SLAM based on improved YOLOV8 and fused with ORB-SLAM3 to cope with dynamic environments[J]. Expert Systems with Applications, 2024, 255: 124918. doi: 10.1016/j.eswa.2024.124918.
    [27]
    SOARES J C V, GATTASS M, and MEGGIOLARO M A. Crowd-SLAM: Visual SLAM towards crowded environments using object detection[J]. Journal of Intelligent & Robotic Systems, 2021, 102(2): 50. doi: 10.1007/s10846-021-01414-1.
  • 加载中

Catalog

    通讯作者: 陈斌, bchen63@163.com
    • 1. 

      沈阳化工大学材料科学与工程学院 沈阳 110142

    1. 本站搜索
    2. 百度学术搜索
    3. 万方数据库搜索
    4. CNKI搜索

    Figures(6)  / Tables(7)

    Article Metrics

    Article views (105) PDF downloads(16) Cited by()
    Proportional views
    Related

    /

    DownLoad:  Full-Size Img  PowerPoint
    Return
    Return